Workstation ब्लॉग
AI Agents
AI Agents टैग वाली पोस्ट।
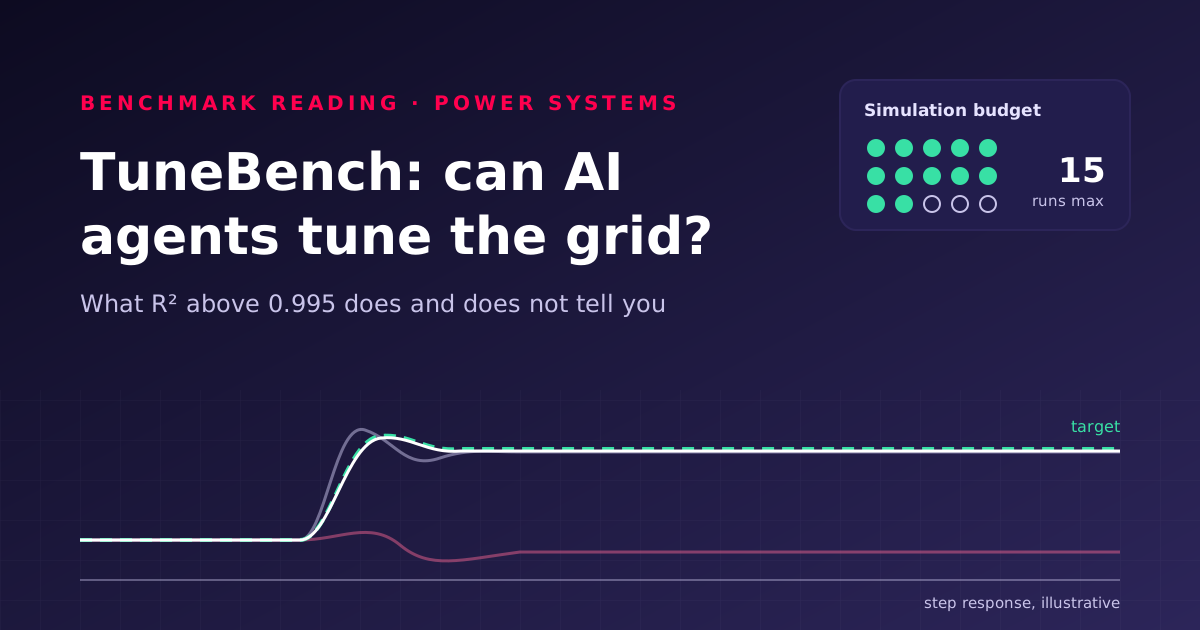
TuneBench: How Well Can AI Agents Calibrate Power System Models?
TuneBench tests LLM agents on calibrating generator and battery models within 15 simulations. Only Opus 5.5 and GPT-6 hit median R² above 0.995 in every test. What that figure means, its limits, and how to build the same kind of benchmark.

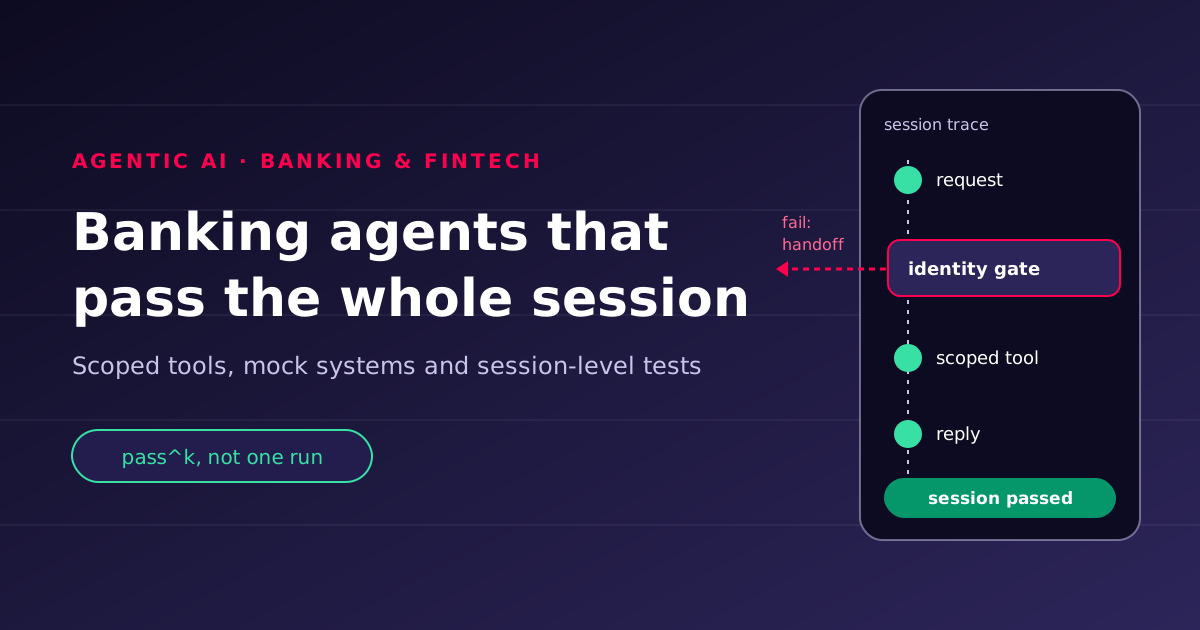
Agentic AI in banking: efficiency you can defend to a risk committee
Banking AI agents rarely fail on one bad reply; they fail across a session. How to scope tools, test whole conversations against mock systems and measure reliability with pass^k, so the time saved survives audit and production.
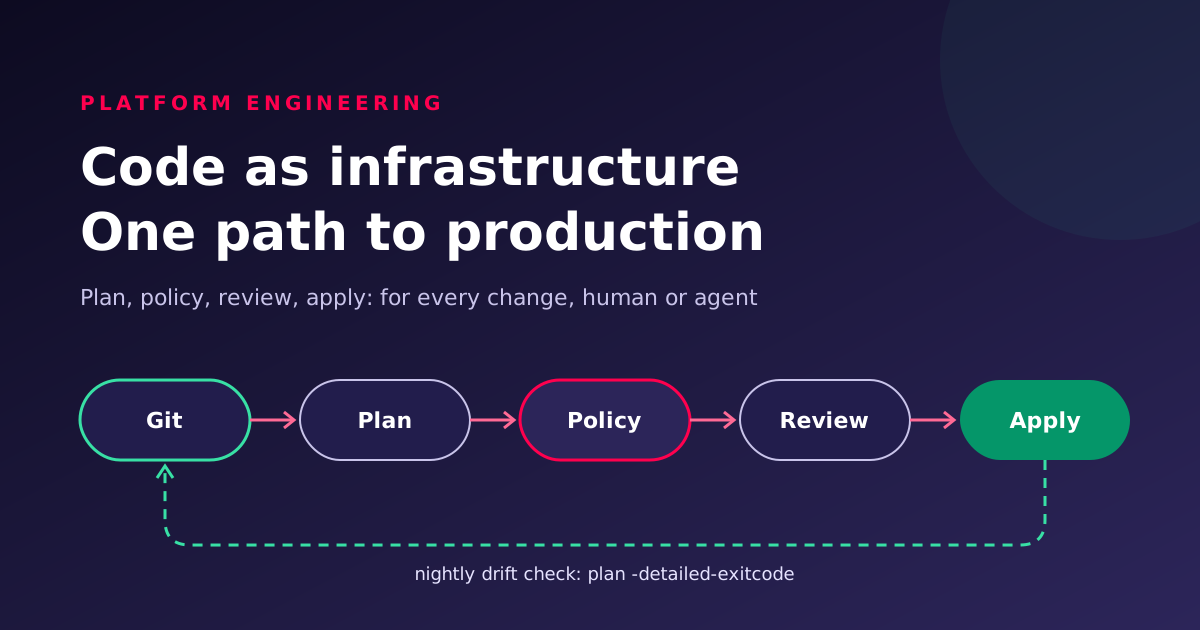
Code as infrastructure: one reviewed path for every production change
Infrastructure as code made servers into files. Code as infrastructure goes further: desired state, policy, pipelines and AI agent access all live in Git, are checked by policy, applied by automation and watched for drift. A practical playbook.
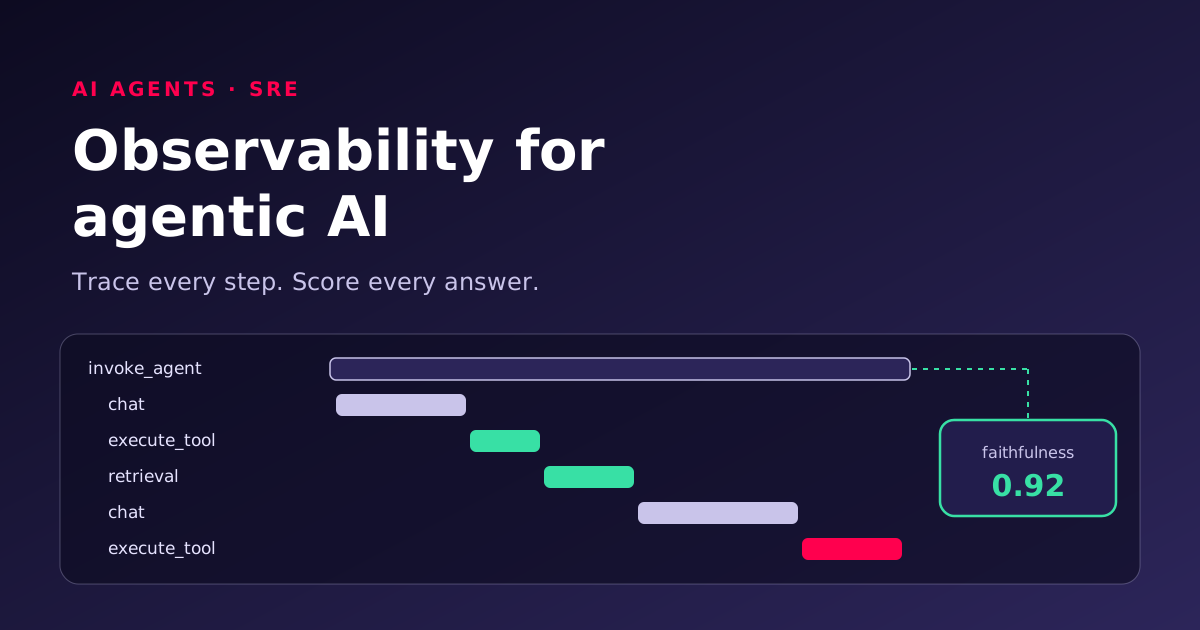
Observability for Agentic AI: Tracing, Evaluating and Auditing Agents
AI agents fail quietly: a confident answer from the wrong document, a tool called with the wrong argument. Learn how to trace every model, retrieval and tool step with OpenTelemetry, attach quality scores, and keep the records auditors ask for.
Trading costs with agents: what an AI agent really costs to run
AI agents move cost rather than remove it. Learn why the token bill grows with the square of loop steps, how caching and compaction bend the curve, and a playbook for pricing, budgeting and capping an agent before it reaches production.
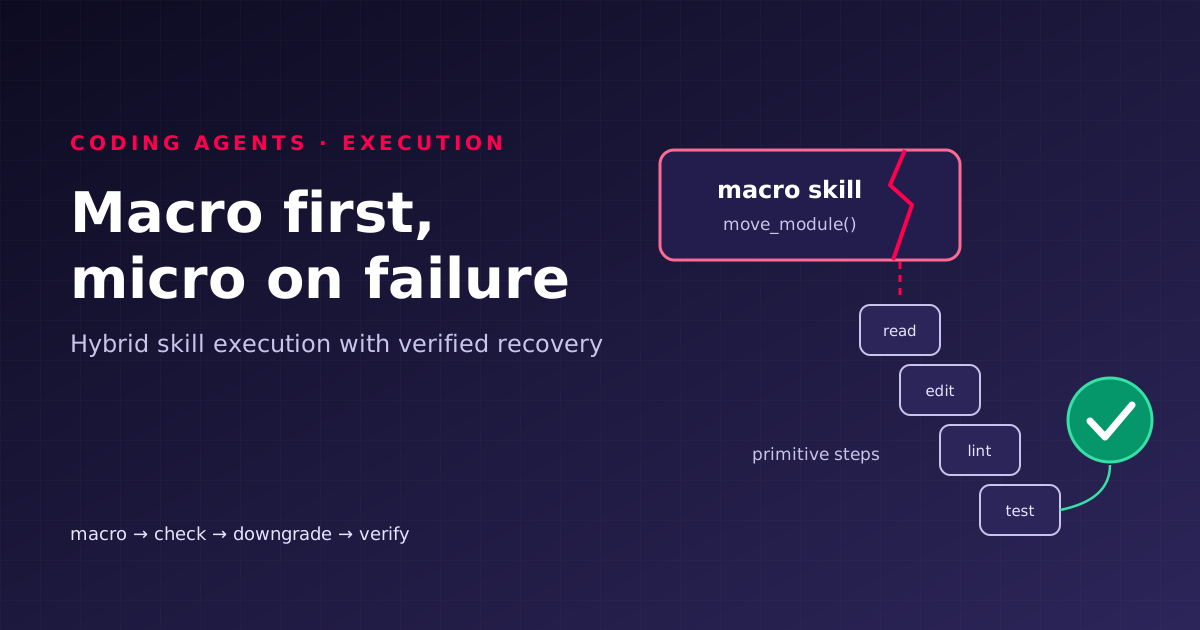
Hybrid Execution for Coding Agents: Macro Skills, Micro Recovery
Bundled macro skills make coding agents cheap but brittle; primitive tool calls make them robust but costly. Here is how to run macros first, verify every result, and fall back to small steps only when the workspace shows it is needed.
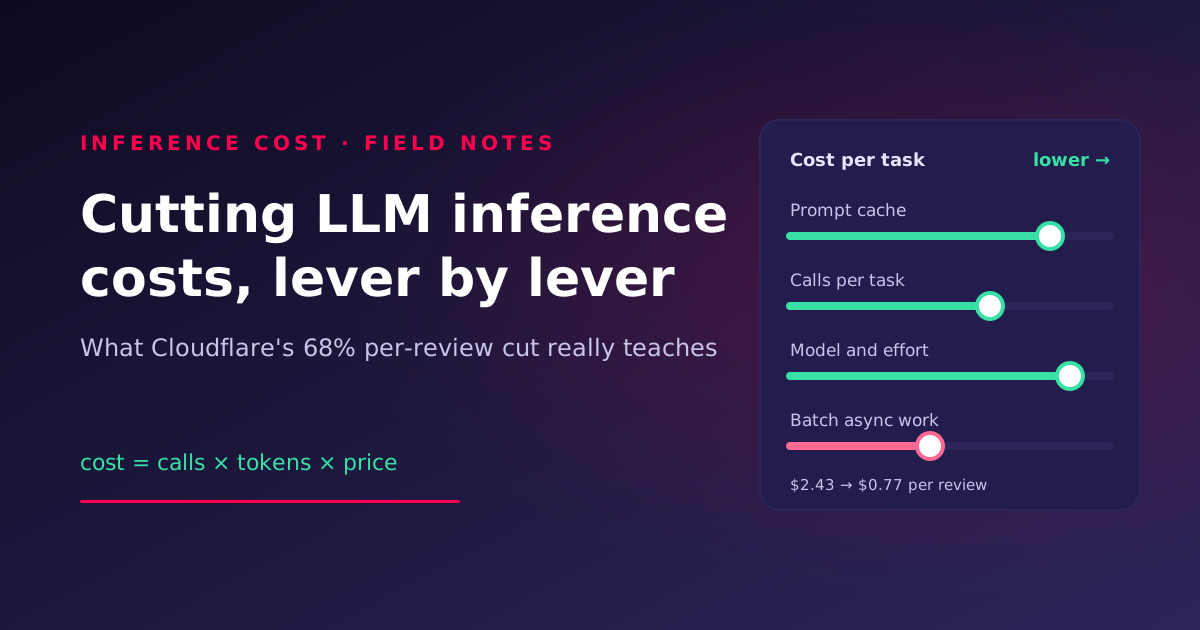
Cutting LLM Inference Costs: Lessons from Cloudflare's 68% Cut
Cloudflare cut its AI code reviewer's average cost per review by 68%. Here is what that number does and does not mean, and a measured playbook for your own workload: prompt cache breakpoints, fewer agent calls, right-sized models and batch.
AI's Double-Edged Impact on DevOps: Faster Changes, Shakier Releases
DORA's research links AI adoption to lower delivery stability. A new simulation shows why: AI-written code overloads review and enlarges deployments, while CI agents can mask defects. Here is how to measure it and keep the speed.
Agentic AI in Production: Permissions, Approval Gates, Traces and Evals
A practical playbook for running AI agents in production: classify every tool by side effect, gate mutations behind a human, set hard stop conditions, trace each step with OpenTelemetry and evaluate continuously.
MCP for DevOps: Give Agents Pipeline Context Without the Keys
How platform teams can use the Model Context Protocol safely: start with read-only servers and scoped identities behind a gateway, trace every tool call, and add write tools only behind human approval. Includes RBAC, tool and task examples.