Hybrid Execution for Coding Agents: Macro Skills, Micro Recovery

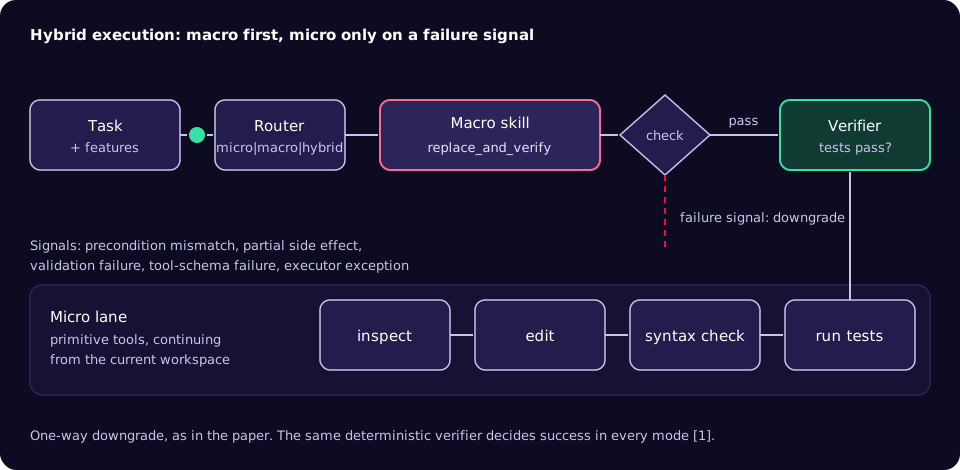
A coding agent that runs everything through big, bundled skills is cheap until a skill does not fit the repository in front of it, and then it simply fails. An agent that does everything with small tool calls rarely fails but spends far more steps and tokens. This post shows how to get most of the cheapness of the first with the robustness of the second: run macro skills first, detect failure with real checks, and drop to primitive tools only when that actually helps.
Three ways for an agent to do the same job
Take a routine change: move a Python module into a new package and fix every import that points at it. A coding agent can do this at three levels of granularity.
- Micro. Only primitive tools: list files, search, read, edit, run a syntax check, run the tests. The model decides every step. Slow and verbose, but it adapts to whatever it finds.
- Macro. One bundled skill such as
move_module_and_update_importsthat performs the whole procedure as a single extended action. Fast when its assumptions hold, brittle when they do not. - Hybrid. Start with the macro. If it reports a failure or a validation check rejects the result, switch to primitive tools and continue from the current state of the workspace.
"Skill" here means a packaged, reusable procedure. In Anthropic's Agent Skills format, for example, a skill is a directory with a SKILL.md file (YAML frontmatter with a name and description, then instructions) plus optional scripts that the agent runs through bash. Only the name and description sit in context until the skill is triggered, and a bundled script's code never enters context, only its output [2]. That makes macro skills attractive: they move work out of the model and into deterministic code.
Most published work on skills is about finding and composing the right skill before execution. A paper from October 2026, "Adaptive Skill Granularity for Coding Agents" by Zhang and colleagues, looks instead at what happens during execution, and frames granularity as a control variable the agent can change at run time [1]. Its conclusion is the useful frame for practitioners: skill libraries should be treated not only as retrievable resources but as controllable, verifiable and recoverable execution abstractions [1].
What the research measured
The authors built a small benchmark, GranBench-Code, where every task has an isolated workspace and a deterministic verifier, and a run only counts as a success if the verifier accepts the final workspace, whatever the model claims [1]. They wrote three macros (inspect_python_module, replace_and_verify and move_module_and_update_imports) and compared fixed and routed policies [1]. On 12 mixed tasks:
| Policy (12 mixed tasks) | Success | Mean steps | Mean tokens |
|---|---|---|---|
| Micro only | 100% | 6.00 | 7,218 |
| Macro only | 58% | 2.71 | 3,609 |
| Hand-written routing rules | 75% | 3.22 | 4,098 |
| Learned router (decision tree) | 100% | 4.17 | 5,518 |
Source: Tables 2 and 4 of [1]. The pattern matches what most teams see in practice: macros roughly halve cost and steps, and lose a large share of tasks when they do not fit. A router that picks the mode per task recovers the success rate at a cost between the two extremes.
Treat the numbers as directional. The authors call it a pilot study: the evaluated subsets are 12 and 7 tasks against a target of 80, the macros are Python-only, and the tables carry no confidence intervals [1]. The design ideas are more transferable than the percentages.
The finding most teams miss: when the failure happens matters
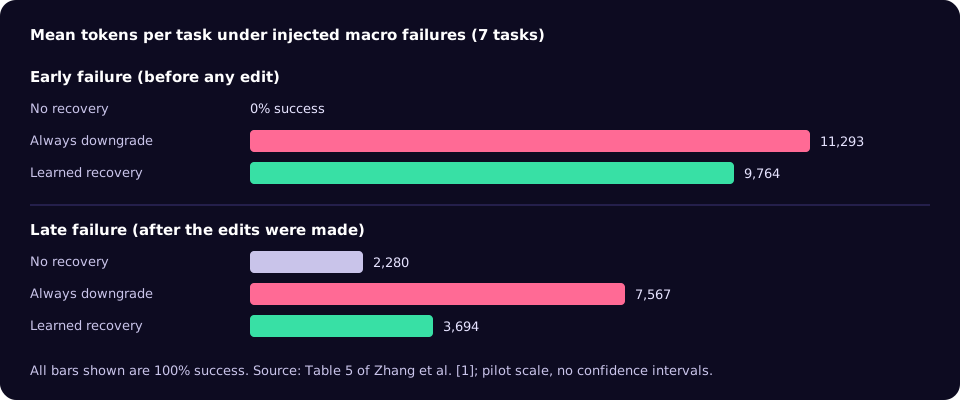
The paper's recovery experiment injected faults into macros either before they changed anything or after they had already made the correct edits [1]. The results split cleanly:
- Early failure. With no recovery, every task failed. With an unconditional downgrade to micro tools, every task succeeded, at an average of about 11,300 tokens [1].
- Late failure. The macro had already done the work, so the no-recovery baseline passed verification on every task at about 2,400 tokens. The unconditional downgrade also passed, but spent about 7,600 tokens redoing work that was already done [1].
A learned recovery policy that skipped fallback when the macro had already completed the changes kept full success and cut late-failure cost to about 3,700 tokens, triggering a downgrade in only 1 of 7 cases [1]. The practical rule is simple: an error message from a macro is not proof the work is undone. Run the verifier before you decide to recover.
Micro, macro and hybrid compared
| Micro only | Macro only | Hybrid with routing | |
|---|---|---|---|
| Cost per task | Highest | Lowest | In between; depends on how often fallback fires |
| Behaviour on mismatch | Adapts step by step | Fails, or leaves a partial change | Detects the failure, then adapts |
| Auditability | Every step visible | One opaque action unless the macro logs internally | Macro plus explicit transition log |
| Engineering effort | Low: tools only | Medium: write and test macros | Highest: macros, signals, executor, router, logs |
| Good fit | Unfamiliar or messy codebases | Well-understood, repetitive changes | Mixed workloads where cost matters |
Playbook: adding hybrid execution to your agent
- Make the verifier the source of truth. Before you write a single macro, define a deterministic check for "done": the test suite, a type check, a lint run, a schema diff. In the paper, success requires verifier acceptance regardless of what the model reports [1]. Without this, nothing else here is measurable.
- Get your primitives solid. Inspect, search, edit, syntax check and test are the fallback path. If they are flaky, recovery is flaky.
- Promote only proven procedures to macros. Look through agent transcripts for sequences that recur and succeed. Write each as a skill with stated preconditions, a deterministic script for the work, and its own validation step at the end.
- Name your failure signals. Each macro should return a structured result, not prose. The paper uses five labels: precondition mismatch, partial side effect, validation failure, tool-schema failure and executor exception [1]. "Partial side effect" is the dangerous one, because the workspace is now neither before nor after.
- Write the executor as a small state machine. Macro, then either done, recover, or stop. Keep the downgrade one-way at first, as the paper does [1]; agents that bounce between levels are hard to reason about.
- Check before recovering. On a macro failure, run the verifier first. If it passes, log a late failure and stop.
- Route on cheap, pre-execution features. The paper's router uses ten static features such as file counts, AST size and depth, import and cross-file dependency counts, and task-type flags, deliberately avoiding anything derived from running the task [1]. Start with hand-written rules; replace them with a shallow model trained on your logs once you have enough runs.
- Log every transition. Mode chosen, macro failures, failure label, whether recovery fired, tokens, steps and verifier outcome. This is your training data for step 7 and your audit trail.
A macro as an Agent Skill
Here is a sketch of the module-move macro as a skill. The name must be lowercase letters, numbers and hyphens, and the description must say what the skill does and when to use it [2]. The script it calls is yours to write.
---
name: move-module-and-update-imports
description: Move a Python module to a new package path and rewrite every import that references it. Use when asked to move, rename or relocate a Python module.
---
# Move module and update imports

## Preconditions (stop and report if any fail)
- The source module exists and `python -m py_compile SRC` succeeds.
- The destination path does not exist.

## Steps
1. Run `python scripts/move_module.py SRC DEST`.
2. Run `python -m compileall -q .` then `pytest -q`.

## On failure
Return one label: precondition_mismatch, partial_side_effect,
validation_failure, tool_schema_failure or executor_exception.
Do not retry. The executor decides whether to continue with primitive tools.
The executor
The control logic is short. This Python sketch assumes your own macro, micro_agent and verifier objects; the important parts are the order of the checks and the log records.
def execute(task, mode, macro, micro_agent, verifier, log):
    """Run one task in micro, macro or hybrid mode. Returns True on verified success."""
    if mode == "micro":
        micro_agent.run(task)
        return verifier.accepts(task.workspace)

    result = macro.run(task)  # structured: .ok, .failure, .trace
    log.append({"task": task.id, "skill_id": macro.name, "level": "macro",
                "ok": result.ok, "failure": result.failure})
    if result.ok:
        return verifier.accepts(task.workspace)

    # The macro reported a failure. Is the work actually undone?
    if verifier.accepts(task.workspace):
        log.append({"task": task.id, "event": "late_failure_no_recovery_needed"})
        return True

    if mode != "hybrid":
        log.append({"task": task.id, "event": "macro_failure_no_recovery"})
        return False

    log.append({"task": task.id, "event": "downgrade", "from": "macro",
                "to": "micro", "reason": result.failure})
    micro_agent.run(task, context=result.trace)  # continue from current workspace
    return verifier.accepts(task.workspace)
Checklist
- Every task type has a deterministic verifier, and success is recorded from it, not from the model.
- Each macro states its preconditions and checks them before changing anything.
- Macros return a structured result with a failure label.
- Fallback signals are defined in code, not left to prompt wording.
- The executor runs the verifier before starting recovery.
- Primitive tools are tested on their own, because they are the safety net.
- Each run logs mode, transitions, failure label, tokens, steps and outcome.
- Routing rules are reviewed against the logs at a fixed interval.
Common mistakes
- Trusting the macro's own success message. A macro that says "done" while the tests fail is the main reason fixed macro execution looks better in demos than in production.
- Recovering on every error. As the late-failure results show, blind recovery can roughly triple the cost of tasks that were already complete [1].
- Retrying the macro instead of downgrading. If the precondition did not hold the first time, it will not hold the second.
- Ignoring partial side effects. A macro that moved the file but did not rewrite the imports leaves a broken workspace. The micro agent needs to know that, so pass the macro's trace into recovery.
- Routing with features that leak the answer. Do not route on signals you only get by running the task; the paper avoids them for this reason [1].
- Too many macros too early. Each macro is code to maintain. Promote procedures only after they have succeeded repeatedly as micro sequences.
Related approaches
Hybrid execution is one point in a wider design space. SkillLens, for example, organises skills into a four-layer graph of policies, strategies, procedures and primitives, and uses a verifier to accept, decompose, rewrite or skip each unit, reporting an ALFWorld success rate rising from 45.00% to 51.31% [3]. The common thread is the same: let a verifier, not the model's confidence, decide when to go finer-grained.
What to do this week
- Pick one repetitive change your agent makes often (a dependency bump, a rename, a config migration) and write down the command that proves it is done.
- Pull ten recent agent transcripts for that change and count steps and tokens. That is your micro baseline.
- Write one macro skill for it with explicit preconditions and a structured failure label.
- Add the "verify before recover" check to your executor, even if your routing is still a single hand-written rule.
- Start logging mode, failure label, tokens and verifier outcome per run, so next month's routing decisions come from data.
Hybrid execution is mostly ordinary engineering: deterministic checks, small state machines and good logs wrapped around a model. If you are building coding or operations agents and want a second pair of eyes on the execution and verification design, our AI agents team works on exactly this.
References
- Zhang, Jiang, Wang and Zhou, "Adaptive Skill Granularity for Coding Agents: Runtime Routing and Macro-to-Micro Recovery", arXiv:2610.31461, October 2026
- Anthropic, "Agent Skills" overview, Claude Platform documentation
- Yu et al., "SkillLens: Adaptive Multi-Granularity Skill Reuse for Cost-Efficient LLM Agents", arXiv:2605.08386, 2026