Cutting LLM Inference Costs: Lessons from Cloudflare's 68% Cut

Most LLM bills are not driven by the price per token. They are driven by how many calls a task makes, how much of each prompt is paid for at full price, and whether the model is bigger than the job needs. Cloudflare's write-up of cutting its AI code reviewer's cost per review by 68% is a rare, well-measured example of fixing all three, and the method transfers to almost any production workload.
What the 68% actually measured
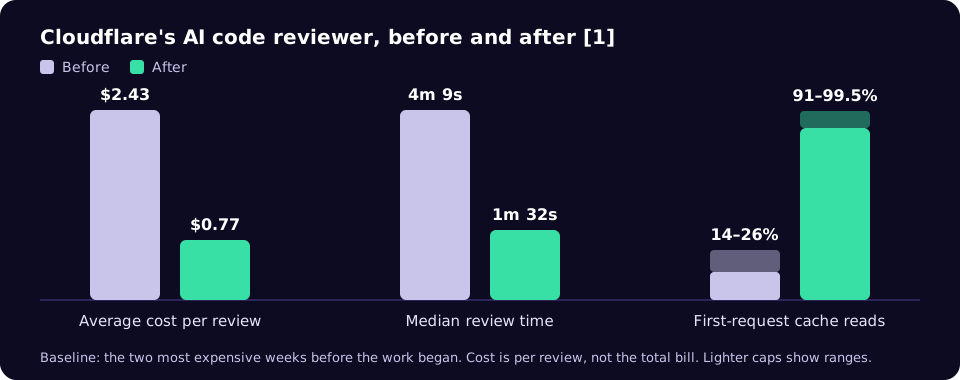
The number in Cloudflare's headline needs reading carefully. It is not the company's whole inference bill. It is the average cost per review of one internal workload, an AI code reviewer that runs several specialist sub-reviewers over each merge request. According to the post, "an average review now costs $0.77 instead of $2.43", measured against the two most expensive weeks before the work started, and the median review now finishes in 1m 32s instead of 4m 9s [1]. That is a 68% reduction per review. The post does not report total spend or say whether review volume stayed constant, so do not quote it as "Cloudflare cut its AI bill by 68%".
Two other details matter more than the headline:
- Roughly 40% of the saving came from engineering changes to the reviewer's code; the rest came from choosing models and effort levels per task [1].
- Quality was tracked, not assumed. Important findings per review went from 0.28 to 0.30 with overlapping intervals, and the team notes that the performance and security reviewers missed some real findings at medium effort, so those will be re-tested at high effort [1].
That second point is the real lesson. A cost cut that quietly lowers quality is not a saving; it is a deferred incident.
The cost equation, and where each lever sits
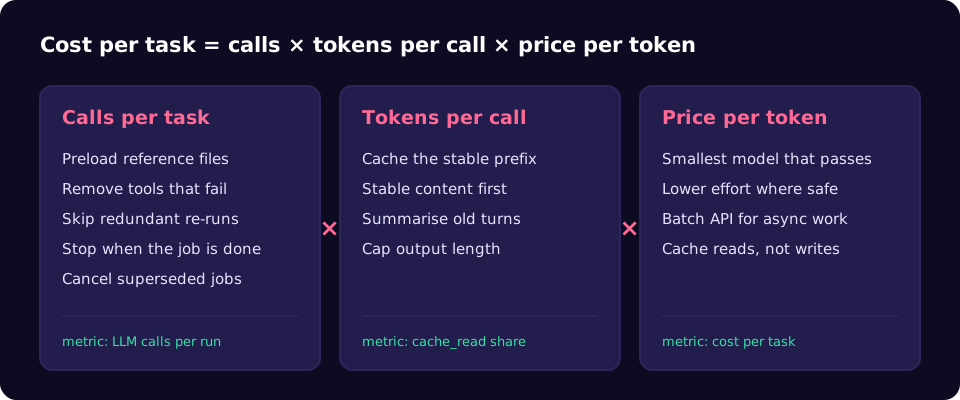
Every LLM bill decomposes into three terms. Writing them down stops teams arguing about GPUs when the waste is in the prompt.
Lever 1: make the prompt cache actually hit
Prompt caching lets a provider reuse the processed form of a prompt prefix it has seen recently, so you pay a fraction of the input price for those tokens. On Anthropic's API, writing a prefix to the default 5-minute cache costs 1.25 times the base input price, writing to the optional 1-hour cache costs 2 times, and reading costs 0.1 times (0.05 times on some newer models) [2]. The 5-minute lifetime is refreshed for free each time the entry is read. The arithmetic is simple: two requests that share a prefix cost 2.0 units uncached and 1.25 + 0.1 = 1.35 units cached, so caching pays for itself from the first reuse.
The catch is that the cache key is the exact prefix. Anthropic caches tools, then system, then messages, in that order, up to each breakpoint, and any change at one level invalidates that level and everything after it [2]. Cloudflare found that its coding agent placed its only cache breakpoint after a block containing repository-specific text. Because every repository produced a different prefix, the first request of a session found a cached prefix only 14% to 26% of the time [1]. Splitting the system prompt so that the shared part got its own breakpoint raised first-request cache reads to 91–99.5%, and the overall cache hit rate rose from 85.7% in April to 97% by September [1].
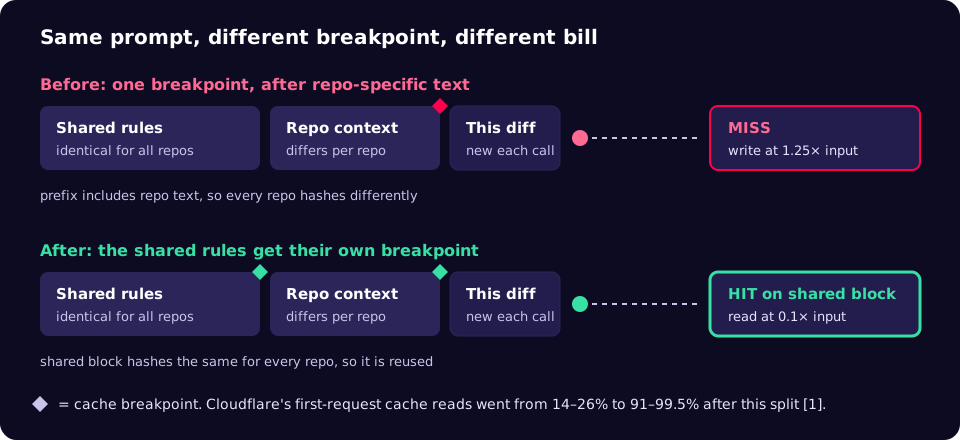
In practice, structure the request so that everything shared comes first and carries its own breakpoint, and everything variable comes last. Anthropic allows up to four breakpoints per request [2]:
{
  "model": "claude-sonnet-5-5",
  "max_tokens": 2048,
  "system": [
    {
      "type": "text",
      "text": "<review rules and reference index: identical for every request>",
      "cache_control": {"type": "ephemeral"}
    },
    {
      "type": "text",
      "text": "<repository conventions: identical within one repo>",
      "cache_control": {"type": "ephemeral"}
    }
  ],
  "messages": [
    {"role": "user", "content": "<the diff to review: changes every call>"}
  ]
}
OpenAI caches automatically for prompts of 1,024 tokens or more and gives the same advice: put stable instructions and shared reference material first, and move timestamps and user-specific data to the end [3]. If you self-host on vLLM, its automatic prefix caching reuses the KV cache (the attention state already computed for earlier tokens) for shared prefixes; it speeds up the prefill phase, not token generation [4].
Two traps catch most teams. First, prompts below the model's minimum cacheable length are silently not cached, with no error returned [2]. Second, small edits such as a timestamp in the system prompt, a reordered tool list or a changed thinking setting invalidate everything after them [2]. Measure, do not assume. Every response reports the split:
def request_cost(usage, price_in, price_out, write_mult=1.25, read_mult=0.10):
    """Cost of one Anthropic Messages call. Prices are per million tokens.
    Check read_mult for your model: some newer models bill cache reads at 0.05x."""
    return (
        usage["input_tokens"] * price_in
        + usage["cache_creation_input_tokens"] * price_in * write_mult
        + usage["cache_read_input_tokens"] * price_in * read_mult
        + usage["output_tokens"] * price_out
    ) / 1_000_000


def first_request_hit_rate(sessions):
    """sessions: list of sessions, each a list of usage dicts in call order."""
    firsts = [s[0] for s in sessions if s]
    hits = sum(1 for u in firsts if u["cache_read_input_tokens"] > 0)
    return hits / len(firsts) if firsts else 0.0
Track the first-request hit rate separately from the overall rate. An agent's later turns hit the cache naturally because they extend their own history; the first request is where a misplaced breakpoint hides, which is exactly what Cloudflare's data showed [1].
Lever 2: cut calls that do no work
Agents spend money on turns that only fetch context. Cloudflare's standards reviewer used its first three turns reading reference files with tool calls. Moving its reference index into the prompt cut its LLM calls per run from 15.9 to 9.6 and its cost per run from $1.12 to $0.72 [1]. The same post lists smaller fixes that add up: removing a tool that sub-reviewers kept trying to call (saving a wasted call and about 2.9k tokens per request), reading shared context and patches in parallel in the first response, skipping reviewers on re-reviews when nothing relevant changed, stopping jobs once results are posted, and having jobs check every 15 seconds whether they have been cancelled [1].
The pattern: read your agent traces and count the turns that end in a tool call whose result could have been known before the run started.
Lever 3: right-size the model and effort per task
About 60% of Cloudflare's saving came from model and effort choices [1]. In a 50/50 split test, Sonnet 5.5 was 62% cheaper per run than Sonnet 5 for the code-quality reviewer, 58% cheaper for performance and 47% cheaper for security [1]. But the team also found that two reviewers lost real findings at medium effort [1]. Model downgrades need an evaluation set of real tasks with known answers, run before and after, per task type. A single global "use the cheaper model" switch is how quality regressions reach production.
Lever 4: move work that can wait to batch
Anthropic's Message Batches API charges 50% of standard prices for asynchronous work, with most batches finishing within an hour and a 24-hour limit [5]. Batch and caching discounts stack, although cache hits inside a batch are best-effort; the docs suggest the 1-hour cache for batches with shared context [5]. Nightly classification, evaluation runs, backfills and report generation rarely need a synchronous answer.
If you run your own GPUs, the equivalent lever is continuous batching: the serving engine schedules many requests onto the GPU together instead of one at a time. The vLLM paper reports 2–4 times the throughput of earlier serving systems at the same latency, largely from better KV-cache memory management [6]. A minimal server with prefix caching made explicit:
vllm serve meta-llama/Llama-3.1-8B-Instruct \
  --enable-prefix-caching \
  --max-model-len 8192 \
  --gpu-memory-utilization 0.90
Set --max-model-len to what your workload actually needs: a shorter maximum leaves more GPU memory for the KV cache and therefore for concurrent requests. Benchmark with your own prompts before and after; throughput gains depend heavily on prompt and output lengths.
Lever 5: stop paying twice
A gateway in front of your providers can remove waste that application code rarely handles. Cloudflare's AI Gateway buffers streaming responses independently of the agent's lifetime, so an interrupted agent can reconnect and collect the response without paying for the same output tokens again; it can route to another provider when one is down; and custom metadata on requests gives cost breakdowns by customer, plan or workflow [7]. Cost attribution by workflow is what makes the rest of this playbook possible.
Which lever to pull first
| Lever | Typical symptom | Evidence it works | Main risk |
|---|---|---|---|
| Fix cache breakpoints | Low cache_read share on first requests | 14–26% to 91–99.5% first-request reads [1] | Silent invalidation by small prompt edits |
| Preload context | Agent's first turns are file reads | 15.9 to 9.6 calls, $1.12 to $0.72 per run [1] | Bigger prefix if it is not cached |
| Model and effort | Large model on routine sub-tasks | 47–62% cheaper per run by reviewer [1] | Lost findings at low effort [1] |
| Batch API | Synchronous calls for overnight jobs | 50% list-price discount [5] | Up to 24 h latency |
| Self-hosted batching | Idle or under-filled GPUs | 2–4× throughput in the vLLM paper [6] | Results vary by workload |
A playbook for your own workload
- Pick one unit of work. A review, a ticket, a document. Cost per unit is the metric; total spend moves with volume and hides progress.
- Baseline cost and quality together. Log the usage fields for every call, tagged by workflow, and build a small evaluation set of real tasks with known good outputs.
- Decompose the bill. Split cost per unit into calls, uncached input, cache writes, cache reads and output. The biggest slice is your first target.
- Fix caching. Order prompts stable-first, add breakpoints after each shared block, remove timestamps and per-request data from the prefix, and watch the first-request hit rate.
- Remove empty turns. Preload known context, delete tools the model misuses, skip work that re-runs on unchanged inputs, and stop or cancel promptly.
- Test cheaper models and lower effort per task type against the evaluation set. Keep the change only where quality holds.
- Move non-urgent work to batch and use a longer cache lifetime for batches with shared context.
- Re-measure weekly and record each change with its date, so savings can be attributed rather than guessed.
Checklist
- Cost per unit of work is on a dashboard, split by workflow.
- Usage fields (
cache_creation_input_tokens,cache_read_input_tokens,input_tokens,output_tokens) are stored per call. - Shared prompt content comes first and has its own cache breakpoint.
- No timestamps, request IDs or user data in the cached prefix.
- Every tool the agent can see is one it can successfully use.
- Each model or effort change has a before/after quality result.
- Asynchronous jobs use the batch endpoint.
Common mistakes
- Quoting a percentage without its denominator. "68% cheaper" per review, per token or in total are three different claims.
- Assuming caching works because it is enabled. A breakpoint in the wrong place, or a prompt below the minimum length, quietly caches nothing [2].
- Paying for cache writes that are never read. A write costs more than an uncached input; a prefix used once is cheaper uncached.
- Downgrading models without an evaluation set. Cloudflare saw real findings lost at medium effort and caught it only because it measured [1].
- Buying hardware first. Faster GPUs do not help if half the calls are unnecessary.
What to do this week
- Export one day of usage data for your busiest LLM workflow and compute its first-request cache hit rate.
- Read ten agent traces and count turns that only fetch context that was known in advance.
- Move any timestamp or per-request field out of your system prompt and re-check the hit rate.
- List the jobs that do not need an answer within the hour and estimate their cost on the batch endpoint.
- Write down 20 real tasks with known good answers as the start of an evaluation set.
None of this needs new infrastructure: it needs per-call measurement and the discipline to change one thing at a time. If you would rather run models on your own hardware, where the same equation applies but the price term becomes GPU utilisation, our private AI work covers sizing and serving.
References
- Cutting our inference bill by 68% by being obsessive about optimization, Cloudflare Blog, 19 October 2026.
- Prompt caching, Claude API documentation, Anthropic.
- Prompt caching, OpenAI API documentation.
- Automatic prefix caching, vLLM documentation.
- Batch processing, Claude API documentation, Anthropic.
- Efficient Memory Management for Large Language Model Serving with PagedAttention, Kwon et al., SOSP 2023.
- Cloudflare's AI Platform: an inference layer designed for agents, Cloudflare Blog, 16 April 2026.