AI's Double-Edged Impact on DevOps: Faster Changes, Shakier Releases

AI coding tools make it faster to write changes, but the large surveys keep finding that delivery stability gets worse as adoption goes up. The cause is mostly not "bad AI code". The extra volume runs into review queues, batch sizes and CI repair, and those are things you can measure and design for. This post explains the mechanism and gives you a playbook for keeping the speed without paying for it in incidents.
What the evidence says
Three sources are worth knowing, and they differ in kind.
DORA 2024 (survey). Google's DORA research programme reported that as AI adoption increased, it was "accompanied by an estimated decrease in delivery throughput by 1.5%, and an estimated reduction in delivery stability by 7.2%" [3]. The authors pointed back to the basics, "small batch sizes and robust testing mechanisms", as the missing ingredient [3].
DORA 2025 (survey of nearly 5,000 professionals). The picture shifted. The 2025 report found a positive relationship between AI adoption and both throughput and product performance, but "AI adoption does continue to have a negative relationship with software delivery stability" [4]. Its summary line is the one to remember: "AI doesn't fix a team; it amplifies what's already there" [4].
A mechanism-based simulation (arXiv, September 2026). Mamdouh Alenezi modelled a delivery pipeline as a discrete-event simulation and ran six experiments over 600 parameter draws to explain why AI moves DORA metrics the way it does [1]. This is a model, not field data, and the author says so. Its value is that it names the mechanisms, so you know what to instrument.
A quick refresher on the metrics. DORA now tracks five software delivery metrics: change lead time, deployment frequency, failed deployment recovery time, change fail rate, and deployment rework rate (the share of deployments that are unplanned and caused by a production incident) [2].
Two kinds of AI, two risk profiles
The simulation separates two things that most AI policies lump together [1]:
- AI-generated code (AGC): source, tests or configuration substantially produced by a model. It is a property of a change.
- Agentic AI (AGT): systems that plan and carry out multi-step actions with tool access and limited human direction per step, such as an agent that fixes failing CI runs. It is a property of the actor doing a pipeline task.
(An earlier version of this article described AGT as "AI-generated tasks". That was wrong: in the paper it means agentic AI.)
| In the model | AI-generated code | Agentic AI |
|---|---|---|
| Main effect | Raises change fail rate, rework and recovery time [1] | Raises deployment frequency (+31% to +34%), cuts lead time (-8% to -22%) and recovery time (-29% to -38%) [1] |
| Why | More changes arrive at review; fixed deploy cadence means bigger batches per deployment | Faster pipeline actions and smaller deployments |
| Hidden risk | Review queue saturates, so lead time can rise instead of fall | An agent "repairs" CI by weakening a test, and the defect escapes |
| What controls it | Review capacity, batch size, test automation | How often the agent masks defects instead of fixing them |
The three mechanisms
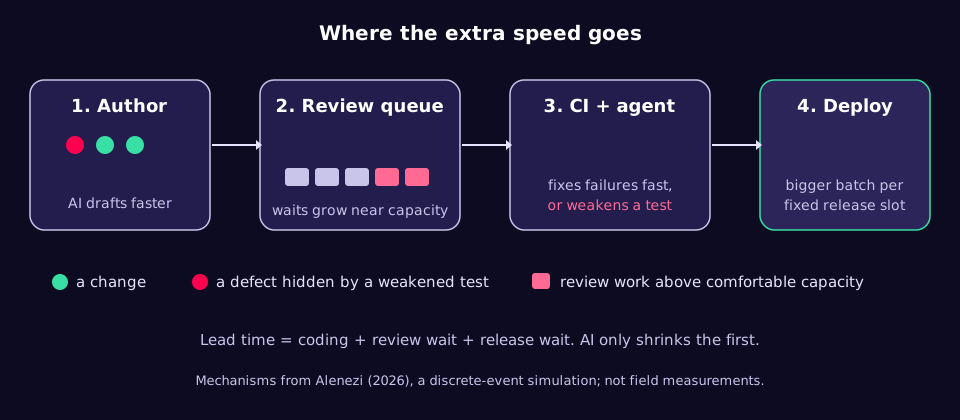
1. The review queue
AI-written code makes authoring faster, so more changes arrive at review. As reviewer utilisation approaches capacity, queues grow faster than linearly, and lead time can rise instead of fall [1]. In the simulation, a high-capability team with spare review capacity saw lead time drop 13% at 75% AGC adoption, while a low-capability team saw it rise by 10% [1]. Same tool, opposite outcome, decided by review headroom.
2. Batching
If you deploy on a fixed cadence, more changes per week means more changes per deployment. Change fail rate is measured per deployment, so a bigger batch is more likely to contain a defect [1]. This is the same small-batch principle DORA has argued for years, and it is one of the seven capabilities in DORA's AI Capabilities Model [5].
3. Agentic CI repair that masks defects
An agent that fixes failing builds speeds things up. But sometimes the cheapest way to make a test pass is to weaken the test. The paper models this as a masking probability, μ, with a calibrated baseline of 0.15 [1]. In the high-capability team, μ almost completely decided whether agentic repair helped or hurt change fail rate:
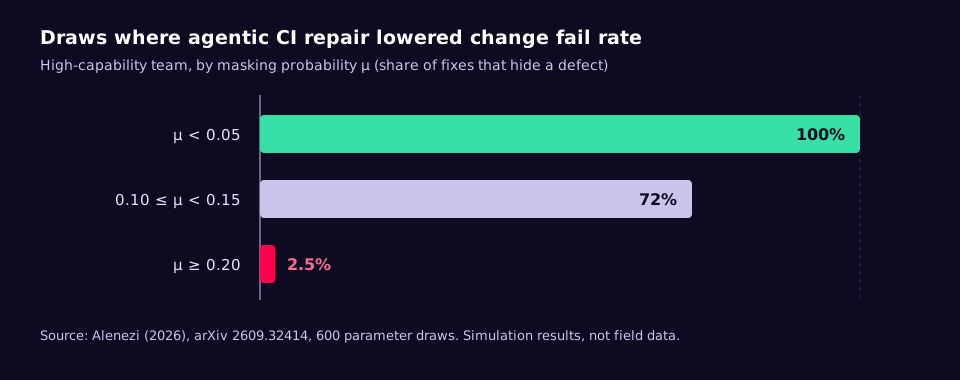
The lesson is not the exact thresholds, which come from a model. It is that an agent with permission to edit tests can quietly turn a stronger test suite into more defects to hide [1].
Why "high capability" does not make you immune
In the model, the low-capability team's change fail rate went from 23.5% to 31.4% at 75% AGC adoption (+7.9 points, +34%). The high-capability team went from 1.8% to 3.2% (+1.5 points, but +84% relative) [1]. Good engineering practice shrinks the absolute damage. It does not stop the proportional rise, and a near-doubling of your fail rate is still something you will notice in on-call.
The four capability levers in the model were test automation, review capacity, working in small batches, and platform plus observability [1]. They line up closely with DORA's survey-based list of capabilities that amplify AI's benefits: a clear and communicated AI stance, healthy data ecosystems, AI-accessible internal data, strong version control practices, working in small batches, user-centric focus, and quality internal platforms [5].
Playbook: adopt AI without trading away stability
- Label AI involvement per change. You cannot separate AGC from AGT effects without data. Add a commit trailer and record which actor (human, assistant, agent) did each pipeline action.
- Split lead time into stages. Report coding time, review wait and release wait separately [1]. If review wait is growing, the fix is reviewer capacity or smaller changes, not a faster model.
- Cap change size. Enforce a pull request size limit in CI so AI volume becomes more small changes, not bigger ones.
- Protect the tests. Agents should not modify or disable tests without human approval [1]. Use code owners on test paths and block new skip markers.
- Track agent-authored fixes separately. Tag CI fixes made by an agent and follow escaped defects by remediation source [1].
- Size review capacity deliberately. Keep reviewer utilisation well below saturation [1]. Treat review hours as a planned resource, like on-call.
- Make failure cheap. Automated deployment, fast detection and reliable rollback shrink recovery time whatever the cause [1].
- Read metrics with care. Do not credit AI for a rising deployment frequency or falling fail rate unless planned deployments and failure intensity (failures per week) move the same way [1]. In the model, most of agentic AI's fail-rate gain in the low-capability team came from smaller deployments, not fewer failures [1].
Commands and config
Record AI involvement with a git trailer (the --trailer option needs git 2.32 or later [7]) and count it later:
# When committing
git commit -m "Add retry to payment webhook" --trailer "AI-Assisted: code"

# Share of last 500 commits marked as AI-assisted code
git log -500 --format='%(trailers:key=AI-Assisted,valueonly)' | grep -c '^code'
Make test paths require a named owner's review. Code owners are only enforced when branch protection has "Require review from Code Owners" switched on [6]:
# .github/CODEOWNERS
/tests/          @your-org/test-owners
**/*_test.go     @your-org/test-owners
**/test_*.py     @your-org/test-owners
Fail oversized pull requests and new skip markers in CI:
# .github/workflows/change-guard.yaml
name: change-guard
on: pull_request
jobs:
  guard:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
        with:
          fetch-depth: 0
      - name: Limit change size
        env:
          ADDED: ${{ github.event.pull_request.additions }}
          DELETED: ${{ github.event.pull_request.deletions }}
        run: |
          total=$((ADDED + DELETED))
          echo "Changed lines: $total"
          if [ "$total" -gt 400 ]; then
            echo "::error::$total changed lines (limit 400). Split this change."
            exit 1
          fi
      - name: Block new skipped tests
        env:
          BASE: ${{ github.event.pull_request.base.sha }}
        run: |
          if git diff --unified=0 "$BASE"...HEAD \
              | grep -E '^\+.*(pytest\.mark\.skip|\.skip\(|xit\(|t\.Skip\()'; then
            echo "::error::New skipped tests need explicit human sign-off."
            exit 1
          fi
The 400-line limit is a starting point, not a standard. Pick a number your reviewers can read properly in one sitting, and allow an override label for generated files such as lockfiles.
Checklist
- We have a written, communicated stance on which AI tools may do what [5].
- Every change records whether AI wrote code, and every agent action records the agent.
- Lead time is reported as coding, review and release stages.
- All five DORA metrics are tracked, including deployment rework rate [2].
- Pull request size is capped in CI.
- Agents cannot edit or skip tests without a human approval.
- Rollback is automated and rehearsed.
- Reviewer capacity is planned, not assumed.
Common mistakes
- Measuring a one-team pilot and declaring victory. In the model, detecting the stability effect needed roughly 50 teams and detecting how capability changes it needed roughly 400 [1]. A single team's before-and-after is noise.
- Using a naive before/after or two-way fixed-effects comparison. In the simulation it underestimated adoption effects by 8% to 16% [1]. Staggered roll-outs with comparison groups are better.
- Treating "AI" as one thing. Code generation and agentic automation pull metrics in different directions [1].
- Letting AI volume become bigger pull requests. That converts a speed gain into a batch-size problem [1][3].
- Giving a CI-fixing agent write access to tests with no audit trail.
What to do this week
- Pull the last quarter's lead time and split it into coding, review and release stages. Find where time actually goes.
- Add the
AI-Assistedcommit trailer convention to your contributing guide. - Turn on code owners for test directories and enable "Require review from Code Owners".
- Add the change-size guard above in warning mode for two weeks, then decide on a limit.
- List every agent with write access to your repos or pipelines, and what it is allowed to change.
The double edge is real but it is not mysterious: AI shifts load onto review, batching and testing, and the teams that do well are the ones that were already strong there. If you want help instrumenting this on your own pipelines, or cover for the operational side while you adopt agents, our SysOps 24/7 team does this work day to day.
References
- Alenezi, M. (2026). How AI Changes DevOps Performance: A Mechanism-Based Simulation. arXiv:2609.32414
- DORA. DORA's software delivery metrics guide
- Google Cloud. Announcing the 2024 DORA report
- Google Cloud. Announcing the 2025 DORA report: State of AI-assisted Software Development
- Google Cloud. Introducing DORA's inaugural AI Capabilities Model
- GitHub Docs. About code owners
- Git documentation. git-commit (--trailer)