
Polyglot Benchmarks: Choosing the Right Tool for the Right Job
How polyglot benchmarks help you pick the right stack for each application — not one language to rule them all
 Balinder WaliaMay 16, 20263 min read
A short, skim-readable companion. For the full architecture deep-dive — harness layout, decision matrix, anti-patterns, and how to fork the benchmarks — read the long article.
Your org picked one stack in 2019. Your workloads did not.
Most teams still standardise on a single language for every new service: everything in Node, everything in Python, everything in Java, or a heroic bet on Rust for greenfield only. That habit is understandable — hiring, CI templates, and security review all get easier when the stack is uniform. The problem is that workloads are not uniform. An API gateway, a nightly ETL job, an NGINX edge transform, a JVM microservice estate, and a chat backend with long-lived connections stress different parts of the runtime. Picking one winner from a hallway debate or a single micro-benchmark is how you end up with the wrong tool carrying the wrong load.
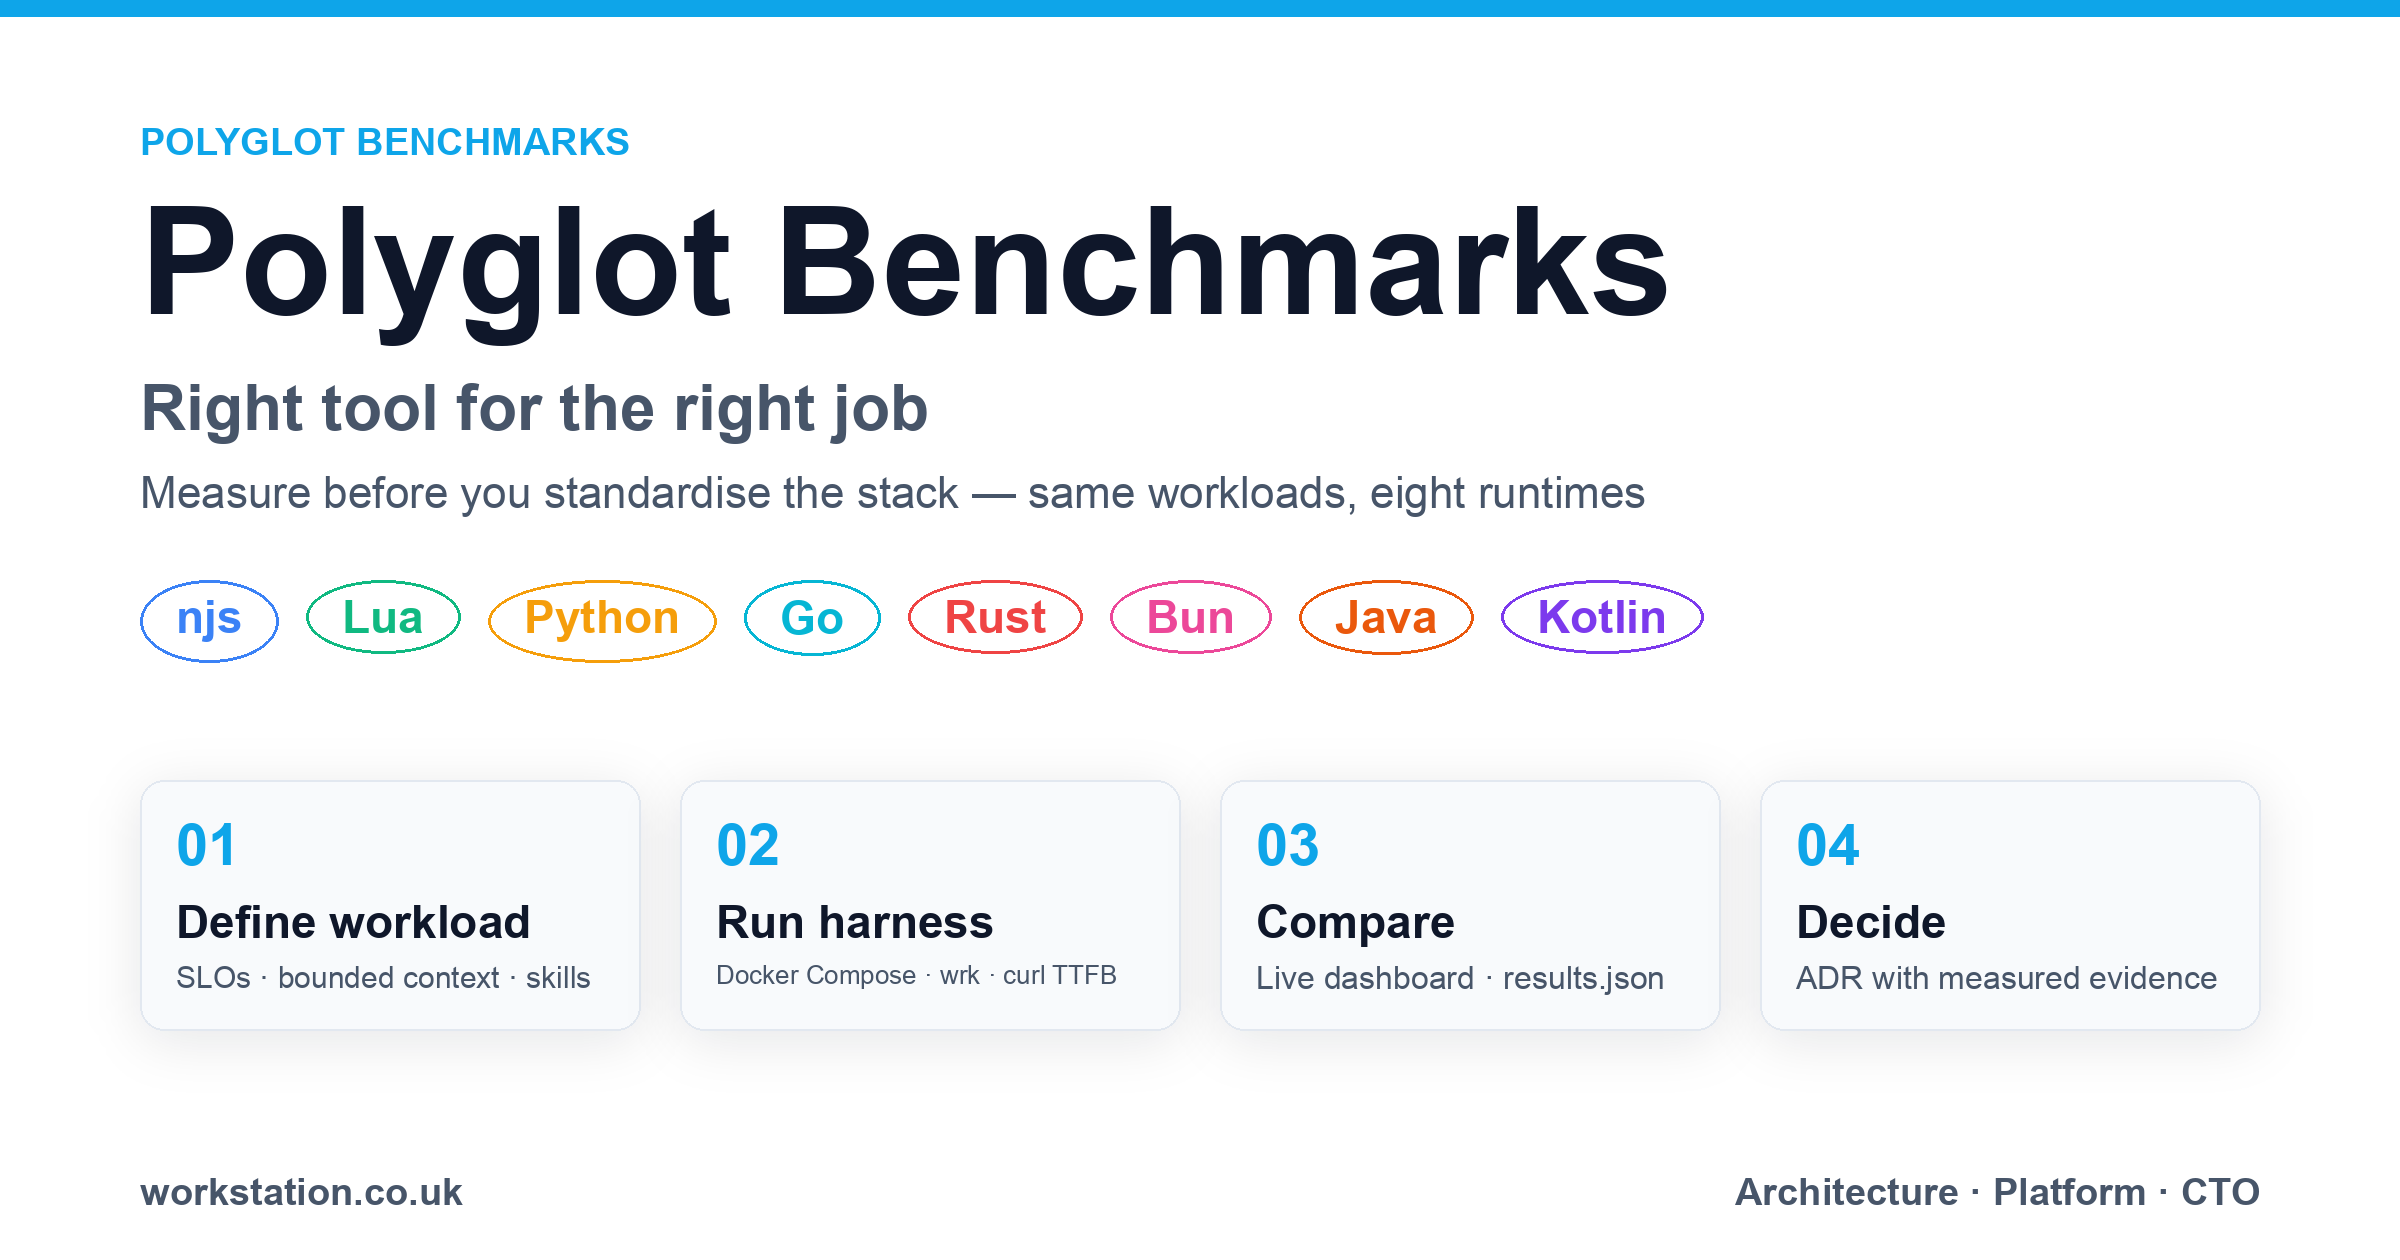
Polyglot Benchmarks is the antidote: a reproducible harness and live dashboard that compares eight runtimes on the same HTTP workloads, so architects can match evidence to bounded contexts instead of default-stack bias.
What it measures
The public dashboard compares NGINX njs, OpenResty Lua, Python (FastAPI), Go (net/http), Rust (Actix), Bun, Java (Javalin / Jetty), and Kotlin (Ktor / Netty) across seven synthetic tests that mirror real API and edge patterns: plain text baseline, JSON serialization, CPU-bound fibonacci, string manipulation, request inspection, internal subrequest + transform, and routing logic. Each test reports requests per second, average and tail latency (including P99), time to first byte from curl, and error counts — streamed live as bench.sh completes.
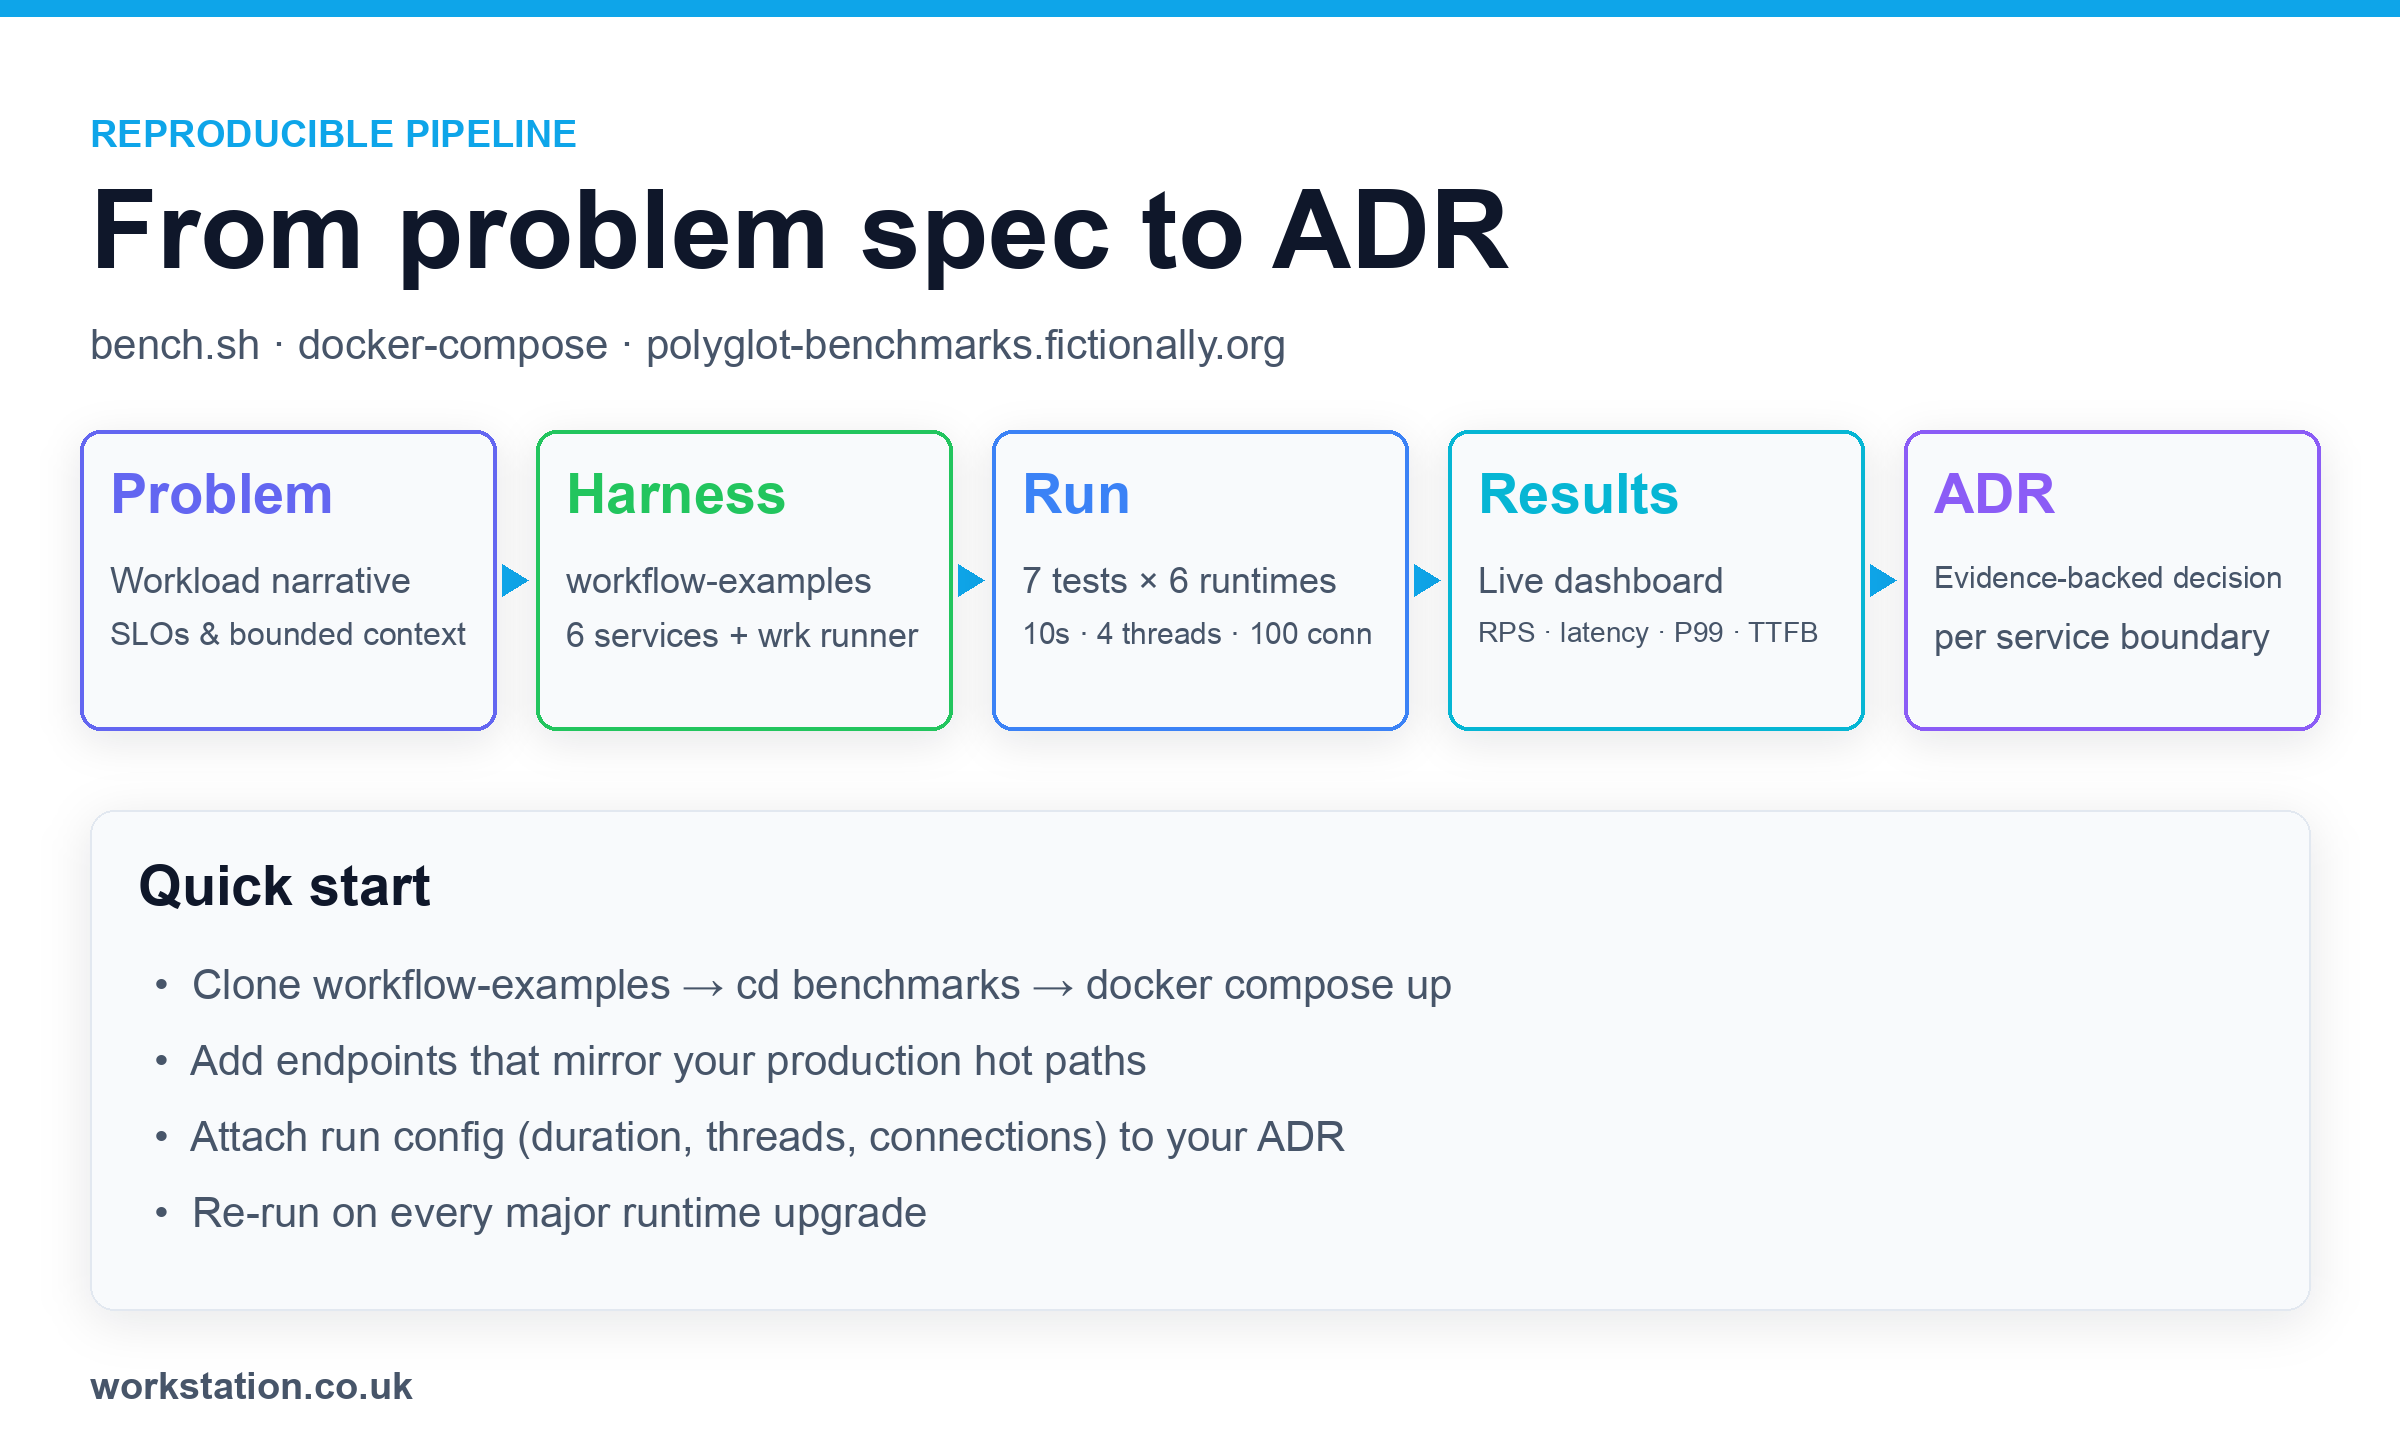
Java and Kotlin sit alongside the compiled and scripting runtimes so JVM shops can see how Javalin and Ktor trade against Go, Rust, Bun, and FastAPI on identical routes — not against a hand-wavy “enterprise vs greenfield” narrative. The harness lives in workflow-examples/benchmarks: Docker Compose services, a shared wrk profile (10 seconds, 4 threads, 100 connections), and JSON results consumed by the dashboard. You can fork it for your own candidates and hot paths.
Why this is a decision framework, not a leaderboard
Polyglot Benchmarks does not crown one language for all time. Winners change per test row — exactly what you want when designing microservices. The dashboard’s verdict section maps results to use cases (edge routing in Lua/njs, core concurrency in Rust/Go, JVM services in Java/Kotlin, velocity in Python). That is the thesis: polyglot by design, with data for architecture review boards instead of opinion.
Six benefits for platform and engineering leads
- Evidence over opinion — attach charts and config to ADRs; settle stack debates with measured runs.
- Workload-specific winners — latency-sensitive paths vs batch vs edge transforms vs JVM estates get different leaders.
- Total cost of ownership — raw RPS is not enough; weigh build time, image size, team skill fit, and ops burden.
- Reproducible workflows — same repo, same Compose file, same wrk script; rerunnable in CI.
- Legitimate polyglot microservices — different languages per service boundary without shame or surprise.
- Risk reduction — prototype in the runner-up before an org-wide mandate.
Quick start
- Open the live dashboard while a run is in progress (or start one locally).
- Clone
workflow-examples,cd benchmarks,docker compose up— eight language services plus dashboard and bench runner. - Read
results.jsonon the dashboard volume and map winners to your workload rows. - Write the ADR — include duration, threads, connections, and hardware class.
Read the long version
The long article covers the full repo layout, a criteria table, the decision-matrix diagram, case patterns per test family (including Java and Kotlin), anti-patterns, limitations, and SEO-ready snippets for sharing with your ARB. Published by Workstation; benchmark site hosted at polyglot-benchmarks.fictionally.org.
#Rust #GoLang #Bunjs #Java #Kotlin #Lua #Python #njs #FastAPI #Javalin #Ktor #OpenResty #polyglot #benchmarks