
Muse Glimmer on Ollama: Always-On Local Agents on One GPU
Meta’s 30B Apache 2.0 agent model — tool use, vision, failure recovery — and what it means for private AI on workstations
 Balinder WaliaAugust 12, 20262 min read
Meta’s Muse Glimmer is a 30B open model tuned for always-on local agents — tool use, long tasks, failure recovery, vision — and it ships on Ollama under Apache 2.0 for a single GPU or Apple Silicon. Here is the Workstation business take. Specs, benches, methodology, and a production checklist in the long article.
ollama launch. Privacy, air-gap, and predictable unit cost become product features — not research projects.
What shipped (in business terms)
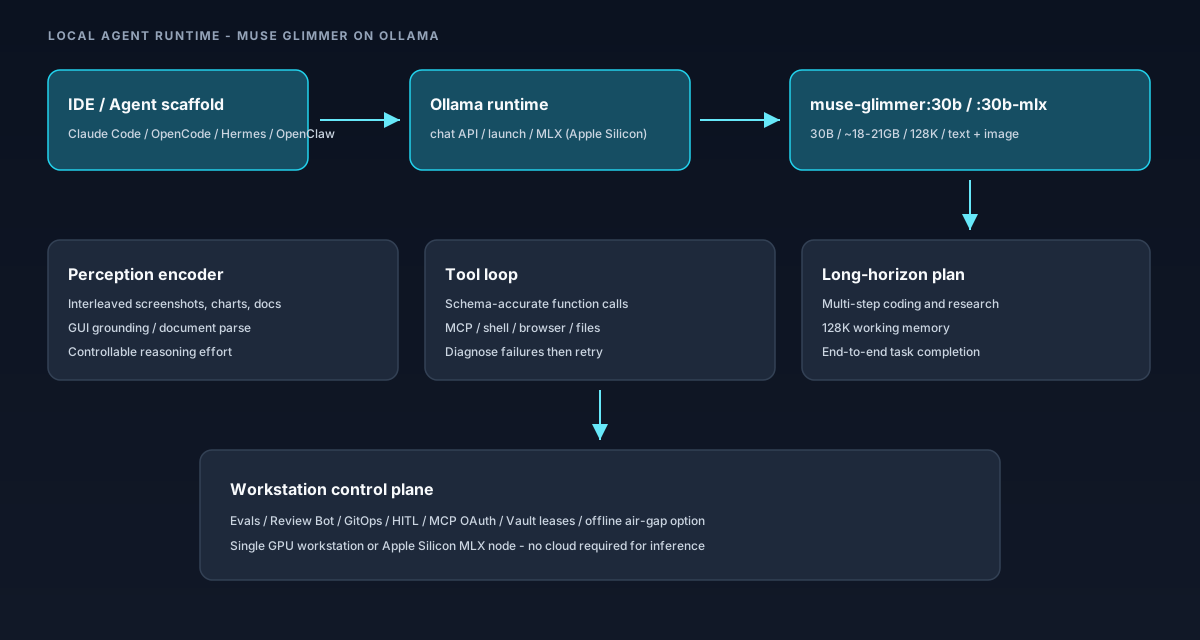
- Always-on local agents: designed to keep working through multi-step jobs without round-tripping every token to a hyperscaler.
- Tool discipline: schema-accurate function calling across long workflows — the difference between a demo chatbot and an agent that files tickets, edits code, or queries MCP tools.
- Failure recovery: when a tool errors or returns nonsense, the model diagnoses and retries instead of freezing the run.
- Multimodal: screenshots, charts, and documents go in alongside text — useful for ops consoles, invoices, and UI automation.
- Controllable effort: dial reasoning strength up for hard tickets, down for latency-sensitive paths.
- Licence: Apache 2.0 — a cleaner commercial story than many “open weights” cards with SaaS carve-outs.
Why boards and SMEs should care
- Data residency: customer PII, source code, and financial docs can stay on the workstation or private VPC.
- Unit economics: inference cost becomes hardware amortisation + electricity, not per-token invoices that spike with agent loops.
- Continuity: offline or degraded-network sites (factories, clinics, field teams) keep agents running.
- Procurement clarity: Apache 2.0 + Ollama distribution lowers legal and ops friction versus opaque weight dumps.
Where it does not replace the cloud
Keep closed APIs (or larger open MoEs on a cluster) for peak-critical paths, brand-sensitive generation, and workloads that need vendor support SLAs. Muse Glimmer is the strong local / private lane in a hybrid router — not a mandate to rip out Bedrock or Anthropic overnight. Pair it with evals, HITL, and the controls in our agentic security brief.
Workstation advice
- SMEs / Mac shops: start with
ollama run muse-glimmer:30b-mlxon Apple Silicon (or the standard 18GB tag on a single mid/high GPU workstation). - Dev teams: wire scaffolds with
ollama launch claude --model muse-glimmer(or OpenCode / Hermes / OpenClaw) and measure your golden tasks — not Meta’s leaderboard alone. - Enterprises: pilot air-gapped agent pods with Review Bot + GitOps; keep a cloud failover for overflow.
Full technical rewrite — architecture, Ollama tags, benchmark matrix vs Gemma4-31B / Qwen3.6-27B, Meta evaluation methodology, and a production checklist: long article. Published by Workstation.