Workstation technical brief on choosing and operating AI GPU workstations: NVIDIA DGX Spark and DGX Station (Grace Blackwell / Blackwell Ultra class), Apple Mac Studio with M5 Max and M5 Ultra, and partner enterprise GPU boxes. Companion: business summary · Products hub: /products#hardware · Packages: AI SME packages.
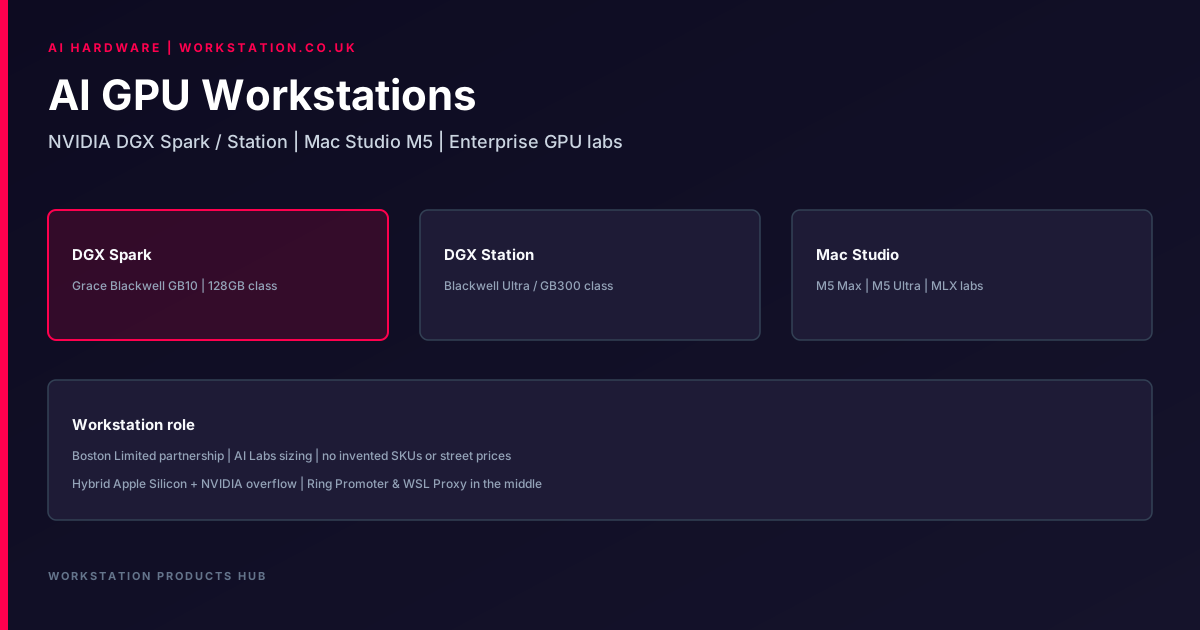
- DGX Spark: Grace Blackwell GB10 desktop; NVIDIA positions ~200B-parameter local agents; ~128 GB unified memory class; NVIDIA AI software stack.
- DGX Station: Blackwell Ultra / GB300-class personal AI supercomputer; trillion-parameter-class positioning; MIG; enterprise software options.
- Mac Studio: Current public lineup is M5 Max and M5 Ultra with unified memory — strong for MLX / Ollama / quiet RAG labs.
- Workstation stance: No invented SKUs or street prices; size in discovery with Boston Limited where enterprise accelerators are needed.
1. Why hardware still matters for AI products
Cloud GPUs remain essential for burst training and elastic serving. Desk-side and lab hardware still win when you need data residency, predictable latency, air-gapped pilots, or FinOps control over always-on inference. Workstation’s products hub treats hardware as a first-class catalog section — not a footnote under software.
This article is a buyer and architect brief. Product names and positioning reflect public vendor pages as of September 2026 research. Exact memory SKUs, GPU counts, and list prices change; confirm with vendor quotes and our discovery workshop before you purchase.
2. NVIDIA DGX Spark — desk-side Grace Blackwell
NVIDIA markets DGX Spark as a desktop AI system built on the Grace Blackwell GB10 superchip class. Public positioning emphasises:
- Secure local agents and models in the up-to-~200 billion parameter class NVIDIA associates with this form factor
- On the order of 128 GB unified system memory
- A preloaded NVIDIA AI software stack so the box is not a bare GPU chassis
For Workstation customers, Spark-class machines fit private RAG, fine-tuning experiments, and agent sandboxes that must stay on the desk or in a locked lab. Pair them with WSL Proxy at the edge when agents call tools over HTTP, and with Ring Promoter when you promote models or agent configs through rings.
3. NVIDIA DGX Station — Blackwell Ultra personal supercomputer
DGX Station is positioned for heavier desktop-to-lab workloads: Blackwell Ultra / GB300-class hardware, trillion-parameter-class marketing claims, Multi-Instance GPU (MIG) for partitionable capacity, and enterprise deployment options including Windows paths where NVIDIA documents them.
Station-class boxes are the usual step when Spark-class memory or FLOPS are insufficient, or when you need a single machine to host multi-tenant inference for a small team before you jump to a full GPU cluster.
| Form factor | Typical fit | Watch-outs |
|---|---|---|
| DGX Spark | Local agents, mid-size open models, desk-side RAG | Not a substitute for multi-node training clusters |
| DGX Station | Heavier inference, team lab, MIG tenants | Power, cooling, and software licence planning |
| GPU cluster | Training, high-QPS serving, HA | Networking, storage, ops headcount |
4. Apple Mac Studio — M5 Max and M5 Ultra
Apple’s current Mac Studio lineup (public product page) centres on M5 Max and M5 Ultra, with unified memory and higher memory bandwidth claims versus prior generations. For AI Labs we still recommend Mac Studio when:
- You want quiet, low-power local inference with MLX, Ollama, or similar stacks
- Knowledge workers share a small on-prem chat / RAG appliance
- You hybridise: Apple Silicon for day-to-day local models, NVIDIA overflow for CUDA-heavy or large-batch jobs
Related reading on this site still includes the earlier M4 Max unboxing guide; treat M5 as the current purchase target and use the M4 article for workflow patterns that remain valid (mactop, first LLM boot, RAG path).
5. Enterprise GPU boxes and Boston Limited
When the requirement is multi-GPU racks, Grace-class servers, or air-gapped clusters, Workstation partners with Boston Limited — a relationship spanning more than two decades. See Partnership details. We size systems to workload classes (generative SME packages, agentic packages, OpenClaw labs) rather than publishing speculative price sheets.
6. How Workstation packages this
- Discover — data residency, model size, concurrent users, tool-calling load.
- Select — Spark / Station / Mac Studio / partner rack, or a hybrid.
- Install — AI SME package software, observability, edge controls.
- Operate — Ring Promoter for promotion, WSL Proxy for agent/API edge, FinOps dashboards for token and GPU burn.
Start from Products → Hardware, AI Labs, or AI SME packages.
7. Sources and honesty limits
- NVIDIA DGX platform / DGX Spark / DGX Station public product pages (positioning for Grace Blackwell GB10, Blackwell Ultra / GB300, memory and software stack claims)
- Apple Mac Studio public product page (M5 Max / M5 Ultra)
- This article does not invent list prices, boutique SKU codes, or unpublished benchmarks
Published by Workstation.
Continue: Products hardware section · Contact us