Governed Loop Architecture for Enterprise AI

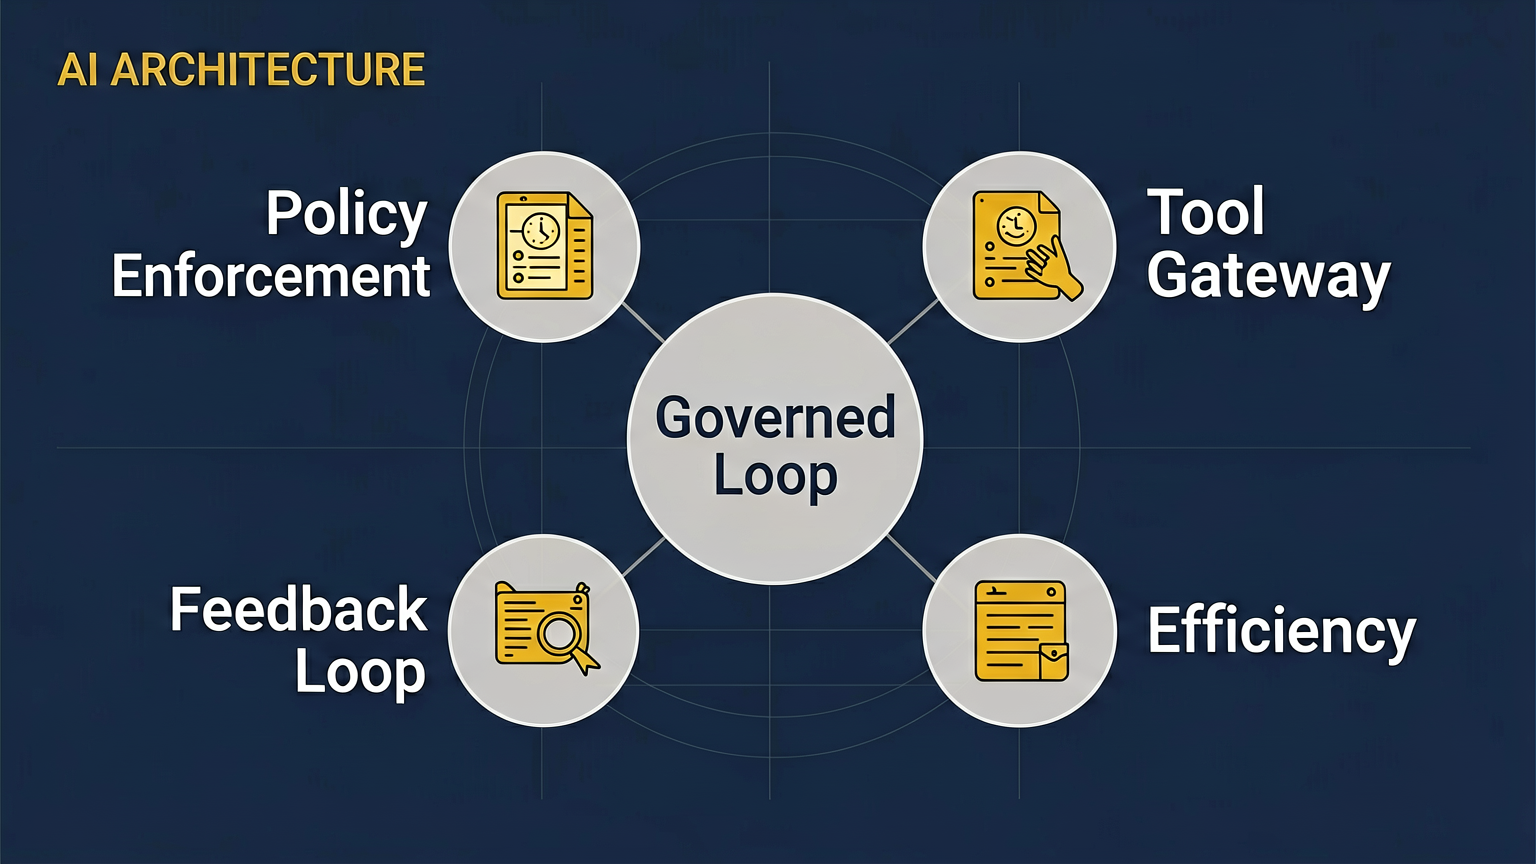
Enterprise AI agents in Banking, Education, HealthTech, FinTech and Tax Returns cannot be left to reason freely. The workloads are regulated, data-sensitive, and high-stakes: a tax return agent must not hallucinate a deduction, a healthtech agent must not leak PHI, a bank agent must not move money without consent. A governed, observable loop architecture gives you a repeatable way to break goals down, enforce policy on every tool call, learn from failures, and keep an audit trail.
The governed loop is Understand → Plan → Act via Tool Gateway + Policy Enforcement → Observe → Revise. It provides a context and purpose for the article: a developer-operable pattern that makes agent behavior predictable, auditable, and safe in regulated domains. The loop is not a single component; it is an explicit sub-task graph, enforced policy on every tool call, feedback-driven replanning, and measurable efficiency controls.
Breaking Down User Goals into Sub-Tasks
The loop starts with understanding. The agent breaks the user's goal into a sequence of sub-tasks [1]. Complex goals might require multiple tool calls and intermediate reasoning steps. The result is an ordered task graph, a directed acyclic graph, or DAG [1].
In a tax returns context this means turning “file my return” into: authenticate taxpayer, pull prior year filing, ingest current year documents, classify income and deductions, run validation rules, generate draft return, request human approval, submit. In HealthTech it might be: verify patient consent, fetch record, summarize for provider, log access.
The DAG matters because it makes dependencies explicit. You can see which steps must finish before others start, and you can replan when one step fails. Decomposing the goal into an ordered task graph gives developers a concrete artifact to test, version, and audit. Without that graph, replanning is ad hoc.
Policy Enforcement Layer and Tool Gateway
No tool runs straight from the plan. Each call first passes through the tool gateway and policy enforcement layer, which checks permissions, inspects the input parameters, applies governance policy, and confirms the request is within budget [1].
For Banking and FinTech this is where you enforce role-based access, data residency, and spend caps. For Education and HealthTech it is where you enforce minimum necessary access and consent checks.
A minimal gateway pattern on AWS looks like:
def call_tool(user_id, tool_name, params):
  if not policy_enforcer.allow(user_id, tool_name, params):
  raise PermissionError("policy deny")
  if not budget_guard.within_limit(user_id):
  raise BudgetExceeded()
  audit.log(user_id, tool_name, params)
  return tool_gateway.invoke(tool_name, params)
The gateway is the choke point for observability. Every invocation is logged with who, what, when, and the policy decision.
The diagram now matches the text: the Agent never invokes Tool directly; the request is routed through Gateway and Policy before invocation, and the result returns to the Agent for observation.
Revising the Plan with Feedback Loop
A plan is not one-shot. When Reason sees that a sub-task failed or came back wrong, the agent can revise the plan by reordering the task graph, choosing a different tool, or splitting a stubborn step into smaller ones [1].
The feedback loop closes the loop: when a tool returns success, an error, or partial data, the result flows back into Understand and becomes part of the context for the next pass. Each pass through the loop uses this new context to move closer to the right answer [1].
In practice for tax returns: if the document classifier returns low confidence on a 1099, the agent splits the step into “extract image → OCR → re-classify” instead of retrying the same call. In banking: if a KYC lookup returns partial data, the agent reorders to request missing fields before attempting approval.
This revise-and-retry behavior is what separates a governed agent from a brittle chain of prompts. It also creates an audit trail of why the plan changed. For developers, the benefit is resilience without sacrificing governance: failures become observable events that feed back into planning, and every revision is logged for compliance review.
Improving Efficiency and Reliability
Governance adds latency. Efficiency measures keep it acceptable.
Caching by prompt hash can save 40% of API calls [2]. Invalidate after 1 hour for dynamic content, 24 hours for static. Saves 40% of API calls [2].
Parallel execution changes everything. Running 10 agents simultaneously turned 5-minute tasks into 30-second tasks [2].
State management matters. Stateless subagents are less prone to bugs and are easier to maintain [2]. Every time I added state 'just this once,' things broke within days [2]. For compliance-heavy industries like HealthTech and Banking, stateless workers simplify forensics: each execution is self-contained and replayable.
Monitoring must be explicit. Track these four things:
- Task success rate (are agents completing tasks?)
- Response quality (confidence scores, validation rates)
- Performance (latency, token usage, cost)
- Error patterns (what's failing and why?) [2]
These metrics feed back into the loop. High error patterns trigger plan revision strategies. Cost spikes trigger budget guardrails at the gateway.
Flexible and Auditable Architectures
Not all agents need the same architecture. The choice shapes efficiency, compliance, and operational complexity.
Skill-Based Architecture is more efficient because you can use cheaper models for simple skills and expensive models for complex reasoning. Each skill can be optimized independently [3]. This fits Education where grading essays needs different capability than checking enrollment status.
Workflow-Based Architecture is perfect for compliance-heavy industries because everything is predictable and auditable [3]. Perfect for compliance-heavy industries. Easy to optimize each step [3]. Tax returns and Banking lend themselves to this: steps are prescribed by regulation and must be reproducible.
Collaborative Architecture introduces complexity around security, billing, trust, and reliability that most companies aren't ready for [3]. Reality check: This sounds amazing but introduces complexity around security, billing, trust, and reliability that most companies aren't ready for. We're still figuring out the standards [3].
| Architecture | Efficiency | Auditability | Model Cost Strategy | Best Fit |
|---|---|---|---|---|
| Skill-Based | High - model per skill | Medium - skill boundaries logged | Cheaper models for simple skills, expensive for complex reasoning | Education, internal ops |
| Workflow-Based | Medium - fixed steps | High - predictable path, full step log | Uniform model per step, easy to validate | Banking, Tax, HealthTech |
| Collaborative | Low - coordination overhead | Low - hard to trace across agents | Variable, multi-party cost | Research pilots |
Trade-off example: A FinTech lender building an application review agent. Skill-Based would route document extraction to a cheap model and risk scoring to a larger model, saving cost. Workflow-Based would enforce a fixed order: identity verification → income verification → policy check → decision, with each step logged for regulators. The governed loop lets you start with Workflow-Based for auditability, then introduce Skill-Based specialization inside each step once success rates stabilize.
Trade-offs, Security and Operations
The governed loop trades raw speed for observability and control. Replanning adds cycles, gateway checks add latency, and DAG maintenance adds engineering overhead. The benefit is auditable correctness in regulated domains.
Security and compliance implications are enforced at the gateway and in the runtime. Using a read-only root file system prevents malicious binaries from writing to a system or a system takeover by attackers [4]. Running containers in privileged mode allows the container to gain access to the host’s critical resources [4]. Setting procMount=Default ensures the container doesn’t unsafely expose any parts of /proc [4].
Implementation in practice means the loop is deployed as stateless workers behind a gateway, with task graphs stored as versioned artifacts, and every tool call logged with policy decision. Integration with other systems happens through the tool gateway, which isolates agent logic from internal APIs, databases, and ML services.
Maintenance and updates are handled by versioning the planner prompts, policy rules, and task graph schemas. Stateless subagents are less prone to bugs and are easier to maintain [2]. Testing and validation rely on the four monitoring signals above: task success rate, response quality, performance, and error patterns [2]. Scalability is achieved via parallel execution and caching; cost control is enforced by the budget guard at the gateway and by prompt-hash caching that saves 40% of API calls [2].
Data governance requires keeping related information together within close proximity to avoid loss in chunking [5]. Explicit, consistent usage of product or feature names helps establish what content relates to which product features [5]. Important terms or concepts not present in a chunk may prevent it from being retrieved for relevant queries [5].
Limitations include higher latency, operational complexity of the gateway, and the need for human-in-the-loop for high-risk steps. Human factors matter: teams need clear ownership of policy rules, and developers need observability to trust replanning decisions. Technical debt accumulates if task graphs are not kept canonical.
Conclusion
The governed loop architecture gives developers a repeatable pattern for enterprise AI: decompose goals into an ordered DAG [1], enforce policy on every tool call via a gateway [1], revise plans with feedback [1], and control efficiency with caching, parallel execution, stateless workers, and explicit monitoring [2]. Architecture choice trades efficiency for auditability: Skill-Based is more efficient [3], Workflow-Based is perfect for compliance-heavy industries [3], and Collaborative introduces complexity most companies aren't ready for [3]. With explicit sub-task graphs, enforced policy on every tool call, feedback-driven replanning, and measurable efficiency controls, you get agents that are useful in regulated sectors without sacrificing safety or auditability.
References
- Inside an enterprise AI agent: A governed, observable loop architecture | Amazon Web Services — aws.amazon.com
- Best Practices for Building Agentic AI Systems: What Actually Works in Production — userjot.com (16 August 2025)
- A PM's Guide to AI Agent Architecture: Why Capability Doesn't Equal Adoption — productcurious.com (4 September 2025)
- Ultimate Guide to Kubernetes Security: 10 Best Practices for Protecting Your Clusters — cast.ai (30 September 2022)
- Writing documentation for AI: best practices | kapa.ai docs — docs.kapa.ai (18 June 2025)