Key takeaways
- Keep the planner generative; insert decision models at routing, safety and evaluation seams.
- Middleware beats prompt-only policy for tool risk.
- Record distributions, versions and gate outcomes for every decision.
Why this matters
Harnesses are where agents become software. The planner can be clever and still be unsafe, slow or bankrupt if every micro-decision is another frontier completion. LangChain’s public Jev post shows two concrete seams — model routing middleware and Auto Mode tool gating. Workstation generalises those seams into a full loop you can implement with Jev or with any calibrated decision backend.
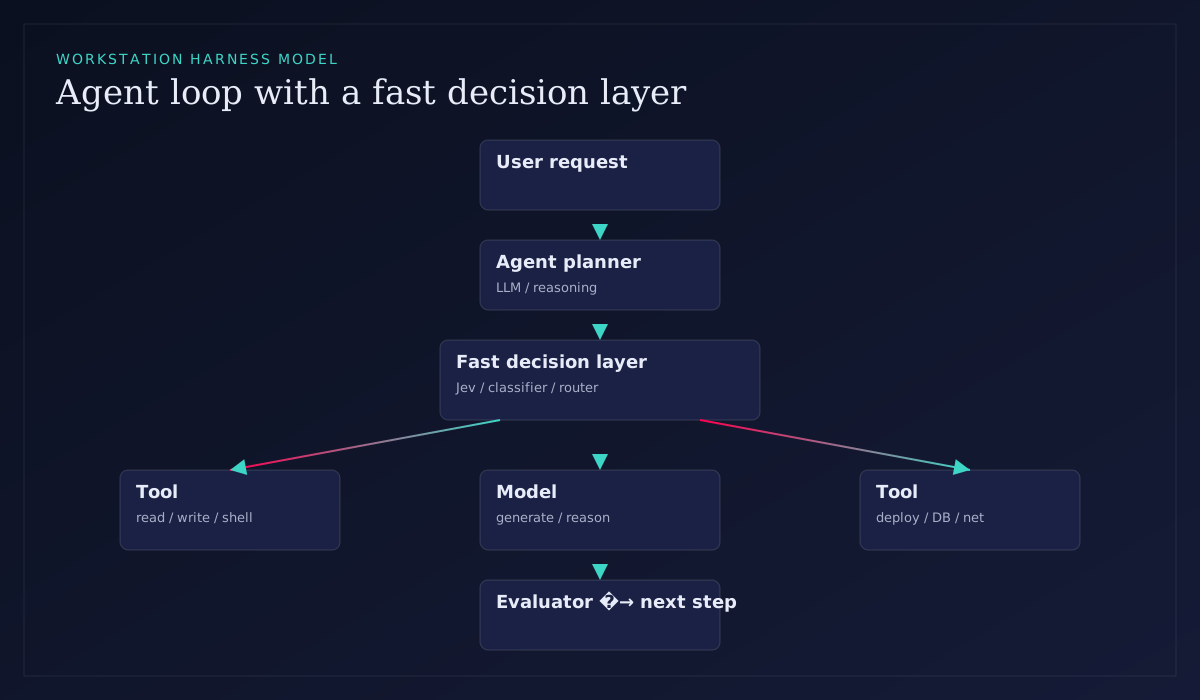
Reference loop
- Ingest user request and memory/context.
- Planner (LLM/reasoning) proposes next action.
- Fast decision layer scores routing, risk and stop conditions.
- Execute tool or generative step.
- Observe results.
- Evaluator classifies healthy / retry / escalate / failed.
- Repeat with budget caps.
Fast decision layer responsibilities
| Seam | Question shape | Action |
|---|---|---|
| Model routing | Choice over model tiers | Bind model for the run or step |
| Tool safety | Noul/Score on risk | Allow / deny / escalate |
| Failure detection | Choice over health labels | Retry policy or handoff |
| RAG answerability | Noul + Score on support | Answer, abstain, retrieve more |
Original Workstation sketch (TypeScript-ish)
type Gate = 'act' | 'review' | 'escalate'

async function safetyGate(toolCall, state): Promise<Gate> {
  const ans = await decisionModel.ask({
    state: { toolCall, transcripts: state.trace.slice(-6) },
    questions: {
      irreversible: { type: 'noul', instructions: 'Irreversible prod mutation?' },
      risk: { type: 'score', levels: ['low','medium','high','critical'] },
    },
  })
  if (ans.noul.irreversible > 0.8 || ans.score.risk >= 3) return 'escalate'
  if (ans.confidence < 0.65) return 'review'
  return 'act'
}This is Workstation sample logic. It is not a copy of LangChain AutoModeMiddleware source, and it is not an official TypeSafe cookbook.
Observability
Emit OpenTelemetry spans for each decision with attributes: model_version, question_ids, latency_ms, network_ms, argmax, confidence, gate_result, benchmark_suite_version. Without that, you cannot debug silent policy drift when jev-latest moves.
Limitations
A harness cannot invent ground truth. If your safety labels are wrong, a fast model will reliably enforce the wrong policy. Start with synthetic + shadowed production traces before enforcing denies.
Extended implementation notes
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 1: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 2: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 3: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 4: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 5: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 6: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 7: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 8: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 9: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 10: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 11: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 12: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 13: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 14: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 15: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 16: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 17: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Building a Jev agent harness: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 18: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Conclusion
The harness is the product. Jev is one possible engine for the decision seams. The architecture remains valuable even if you swap engines.
Related on Workstation
Sources
- TypeSafe AI — Introducing System One Models & Jev — Vendor announcement.
- LangChain — Building a Harness with Jev — Harness patterns.
- TypeSafe docs index — Official primitives and API.
- LangChain — Jev as agent evaluator — Judge variance experiment.
- OpenRouter — Jev vs LLM — Triage tables.
- AyAutomate independent benchmark — 791 decisions.
- JevBench RESULTS — Public harness.
- OpenAI — Introducing the Agents API — Agent platform context in the wider landscape.