Key takeaways
- Routing is a hypothesis: measure cost, latency, success and escalation together.
- Confidence cascades can recover frontier-like accuracy at lower average cost — when evaluated carefully.
- High-cardinality routing is a different problem than binary urgency.
Why this matters
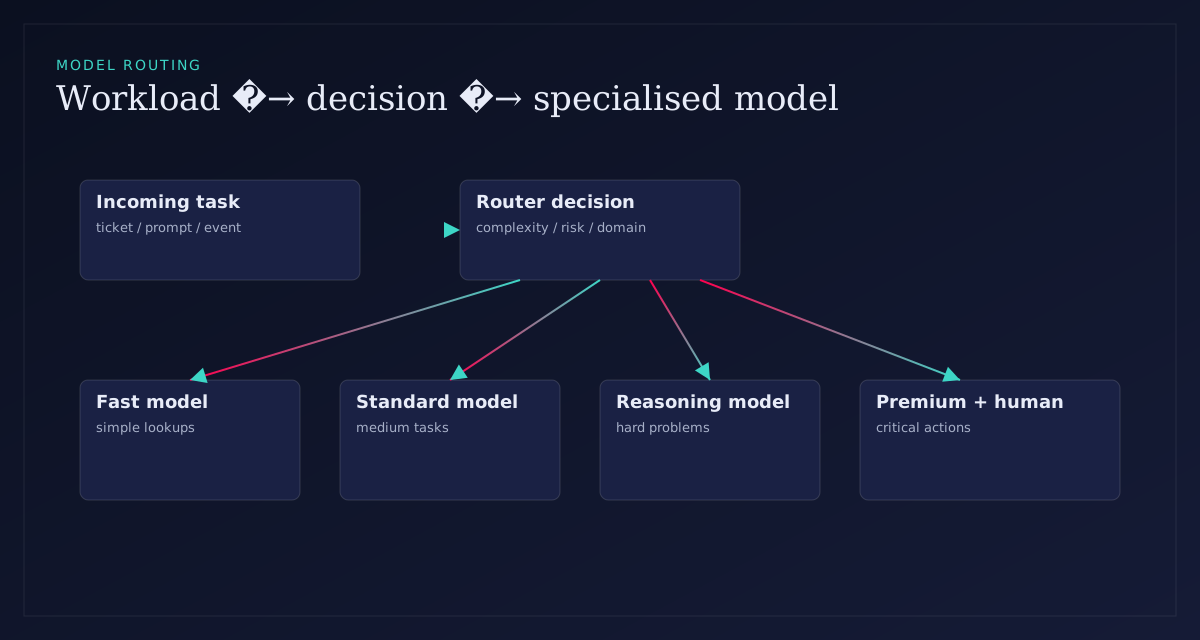
A single premium reasoning model is operationally simple and economically brutal. Routing promises Pareto improvement. Many routers quietly destroy quality by under-sending hard tasks or thrashing between models.
Patterns
- Static rules (regex/intent enums) — cheap, brittle.
- Decision-model router (Choice over tiers) — flexible, measurable.
- Confidence cascade — try cheap, escalate if confidence low (AyAutomate discusses cascades recovering accuracy).
- LangChain ModelRouterMiddleware-style binding for a run — see their public post.
What to measure
| Metric | Why |
|---|---|
| Task success | Did the user/job complete? |
| Escalation rate | How often did we climb tiers? |
| p50/p95 latency | Including network, labelled |
| Cost per successful task | Not cost per call alone |
| Error rate by tier | Catch under-routing |
What the public evidence suggests
OpenRouter’s triage example shows near-tied accuracy across Jev and strong LLMs with large cost gaps on a small set. AyAutomate finds high-cardinality routing still favours a frontier baseline on accuracy, with cascades as a mitigation. TypeSafe’s own cardinality note says Jev supports up to 255 choices and may use multi-stage scoring beyond that — an architectural constraint to design for.
Never ship a router because a blog table looked good. Replicate on your labelled tasks.
Workstation methodology (Benchmark B)
Our lab defines fixed-premium vs intelligent-routing arms on the same items, reporting success, cost, latency and escalation. Until a live measured Workstation run is published, the dashboard marks methodology rows accordingly.
Extended implementation notes
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 1: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 2: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 3: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 4: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 5: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 6: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 7: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 8: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 9: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 10: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 11: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 12: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 13: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 14: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 15: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 16: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 17: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 18: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 19: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for Model routing: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 20: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Conclusion
Routing is an optimisation problem under quality constraints. Decision models are strong candidates for the router — not automatic winners.
Related on Workstation
Sources
- TypeSafe AI — Introducing System One Models & Jev — Vendor announcement.
- LangChain — Building a Harness with Jev — Harness patterns.
- TypeSafe docs index — Official primitives and API.
- LangChain — Jev as agent evaluator — Judge variance experiment.
- OpenRouter — Jev vs LLM — Triage tables.
- AyAutomate independent benchmark — 791 decisions.
- JevBench RESULTS — Public harness.
- OpenAI — Introducing the Agents API — Agent platform context in the wider landscape.