 Workstation team
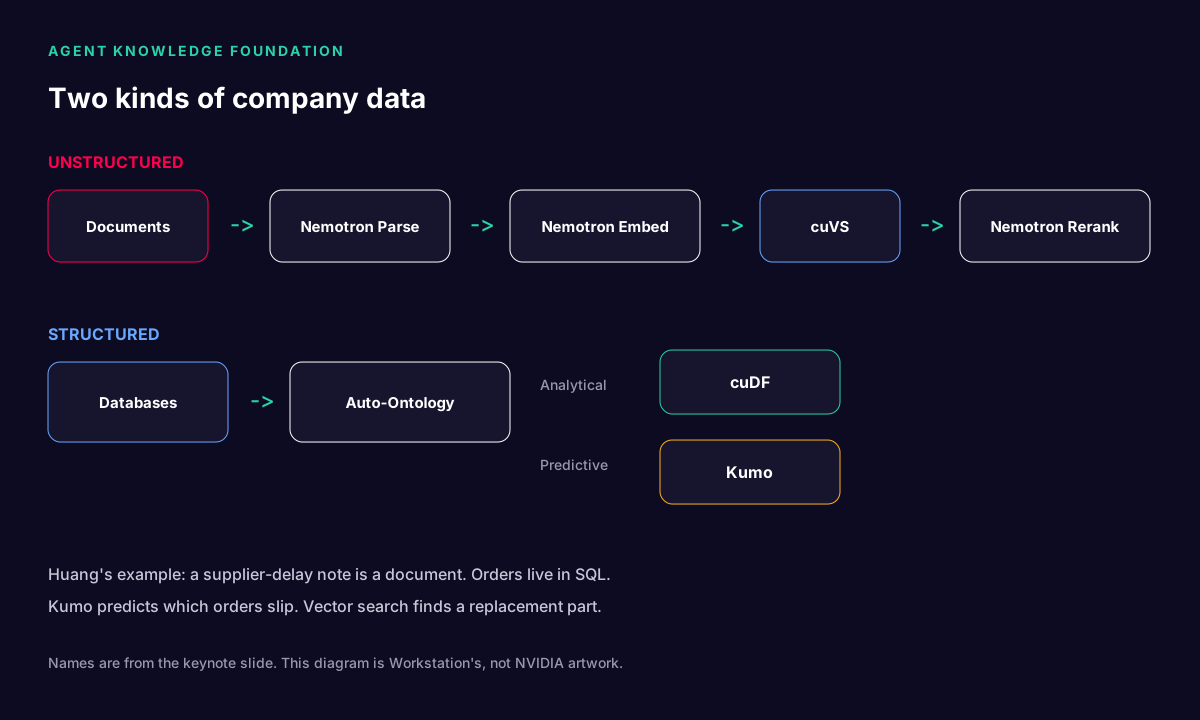
The Agent Knowledge Foundation slide at GTC Berlin splits company data in two. Documents go through Nemotron Parse, Nemotron Embed, cuVS and Nemotron Rerank. Databases go through Auto-Ontology, then cuDF for analysis and Kumo for prediction. This post explains each box, names the open-source frameworks that do the same jobs, and walks the pattern through two fields where both kinds of data collide every day: healthcare and scientific research. That includes the chat assistants and robots already working there.
What Huang said
A supplier delay arrives as a document. The orders that supplier feeds live in SQL. Huang said you use Kumo to predict which orders slip, and vector search to find a replacement part in the engineering files. The keynote transcript mangles Kumo as "QMO" and "CUMA." The slide spells Kumo. We follow the slide.
He also said Nemotron ships with weights, data and the scripts to rebuild it, and that it is not automatically a frontier language model until someone post-trains it. One of the partner examples he gave from the stage was a healthcare one: Palantir working with Tampa General Hospital. The full list, as he said it, is in the long article. They are his examples, not ours, and we have not verified the engagements.
The document lane, box by box
This is retrieval-augmented generation (RAG) drawn as four separate jobs rather than one box. Splitting it matters, because each step fails in its own way and needs its own test.
- Parse. Turn a PDF, scan or slide deck into clean text, tables and figure captions, with the page and position kept. Clinical letters and lab reports are full of tables, headers and handwriting. A parser that flattens a results table into a run of numbers will poison everything downstream. Nemotron Parse is NVIDIA's model for this. Open alternatives include Docling (from IBM), Unstructured and Marker. Cloud services include Azure Document Intelligence and AWS Textract.
- Embed. Turn each passage and each question into a vector, so that "shortness of breath" and "dyspnoea" land near each other. Nemotron Embed does this. Widely used open models include BGE-M3, E5 and Nomic Embed. Test any embedder on your own vocabulary before trusting it, because general models often handle drug names and gene symbols badly.
- Search. Find the nearest vectors quickly across millions of passages. cuVS is NVIDIA's GPU library for this, and its CAGRA graph index is also used inside Milvus and FAISS. For smaller collections, pgvector in an existing PostgreSQL database is often enough. Qdrant and Weaviate are other common choices. Combine vector search with plain keyword search (BM25), because identifiers such as NHS numbers, batch codes and gene names need exact matching.
- Rerank. Search returns fifty plausible passages. A reranker reads each one against the question and puts the five that actually answer it at the top. Nemotron Rerank does this. Open alternatives include the BGE rerankers and ColBERT-style late-interaction models. In our experience reranking is the cheapest accuracy gain in the whole pipeline.
The output of this lane should always be passages with their sources, not a finished answer. The agent writes the answer. The citation lets a person check it.
The table lane, box by box
- Auto-Ontology. Before a model can reason over a database, something has to say what the columns mean and how the tables join. "obs_cd 8867-4" means nothing to an agent until it knows that it is a LOINC code for heart rate. Huang's slide puts an automatic step here. In healthcare most of the ontology already exists: SNOMED CT for clinical terms (used across NHS primary care), LOINC for observations, dm+d for UK medicines, ICD-10 and OPCS-4 for diagnoses and procedures. In science there are ChEBI for chemicals, the Gene Ontology and UniProt. Map to these rather than inventing your own. dbt's semantic layer and knowledge-graph tools such as Neo4j are common ways to write the mapping down.
- Analytical: cuDF. cuDF is the GPU dataframe library from NVIDIA's RAPIDS project. Its
cudf.pandasmode accelerates existing pandas code without rewriting it, and Polars can use cuDF as a GPU engine. This is the "how many, how much, compared with last month" side. For most questions the honest first tool is SQL. A language model that writes SQL against a well-described schema (text-to-SQL) and shows the query is far easier to audit than one that guesses numbers. - Predictive: Kumo. Kumo builds predictions directly over many linked tables using graph neural networks, instead of a data scientist hand-building features. It has published a pretrained relational foundation model, KumoRFM. The academic benchmark for this style of work is RelBench from Stanford. The conventional alternative is still gradient-boosted trees such as XGBoost over engineered features. Use whichever you can validate, and validate on data from a period the model has never seen.
The frameworks that tie it together
The two lanes are libraries. Something has to decide when to call them, keep state and enforce limits. That is the agent harness, and the Berlin keynote put it in a sandbox first (see our OpenShell post).
| Job | NVIDIA stack | Common open-source or vendor options |
|---|---|---|
| Parse documents | Nemotron Parse, NeMo Retriever extraction | Docling, Unstructured, Marker, LlamaParse |
| Embed and rerank | Nemotron Embed, Nemotron Rerank | BGE-M3, E5, Nomic Embed, BGE reranker, ColBERT |
| Vector search | cuVS (CAGRA) | Milvus, FAISS, pgvector, Qdrant, Weaviate |
| Analyse tables | cuDF, RAPIDS | SQL, DuckDB, Polars, pandas, dbt |
| Predict over tables | Kumo (partner) | XGBoost, LightGBM, PyTorch Geometric |
| Knowledge graph | Auto-Ontology step | Neo4j, Microsoft GraphRAG, RDF and OWL tools |
| Agent orchestration | NeMo Agent Toolkit, AI-Q blueprint | LangGraph, LlamaIndex, Haystack, CrewAI, Microsoft Agent Framework (AutoGen), DSPy |
| Tool connections | NIM microservices | Model Context Protocol (MCP), Agent2Agent (A2A) |
| Language model | Nemotron | Llama, Qwen, Mistral, Gemma and MedGemma, or a hosted frontier model |
| Robots | Isaac Sim, Isaac Lab, Cosmos, GR00T, Holoscan | ROS 2, MoveIt, Hugging Face LeRobot, openpi |
None of these is required. A small team can build a solid first version with Docling, pgvector, a reranker, PostgreSQL and LangGraph or LlamaIndex on one GPU workstation. The NVIDIA parts earn their place when the corpus reaches tens of millions of passages or the tables reach billions of rows.
Healthcare: why both lanes are needed
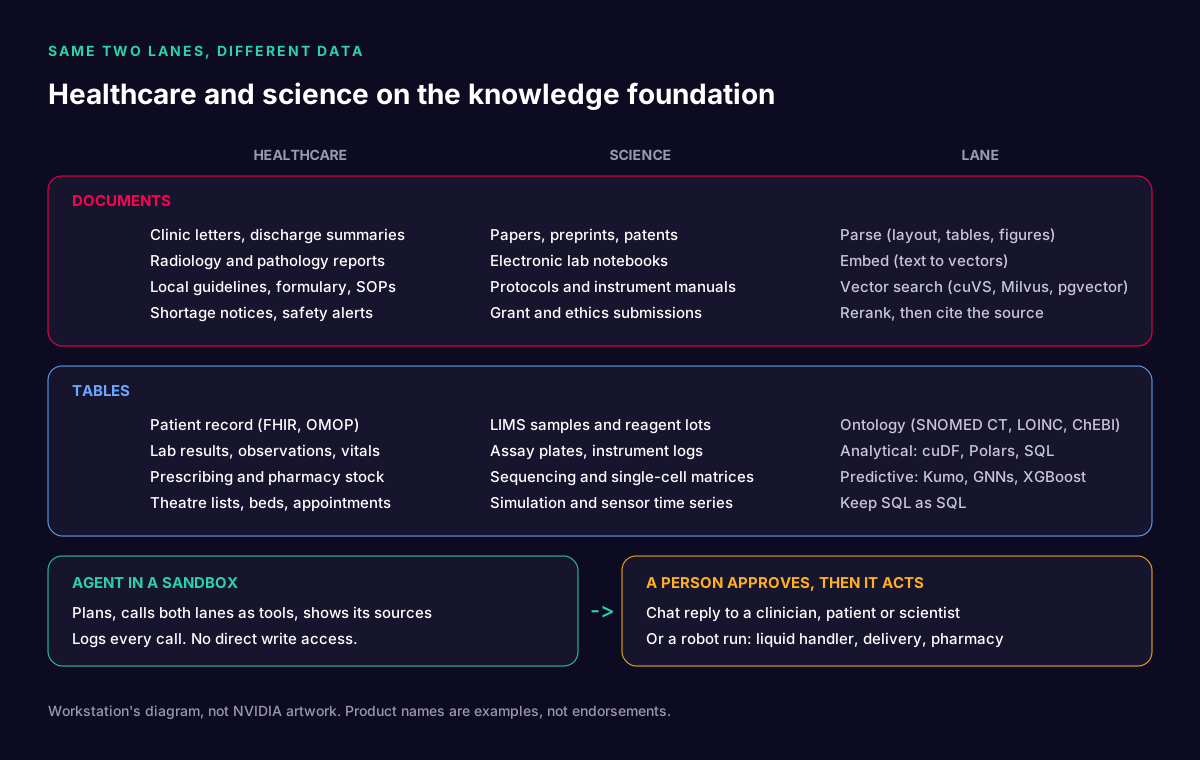
A hospital is the clearest example of Huang's split. Most of what clinicians know about a patient is written down: referral letters, clinic notes, discharge summaries, radiology and pathology reports. The things that are counted, such as results, prescriptions, bed states and appointments, sit in the electronic patient record and its data warehouse. Clinical questions almost always need both.
Huang's supplier example, translated
Replace the late supplier with a medicine shortage.
- A shortage notice or a Serious Shortage Protocol arrives as a PDF or email. The document lane parses it and extracts the product, strengths and dates.
- The table lane maps the product to dm+d codes and queries prescribing: which patients are on it, how much stock each pharmacy holds and when each patient's next supply is due.
- A predictive model ranks which patients run out first, using dispensing history and clinic schedules.
- Vector search over the local formulary, guidelines and the shortage notice finds the approved alternatives, with citations.
- The agent drafts a worklist for a pharmacist: patient, risk, suggested alternative and source. The pharmacist decides. Nothing is changed in the record by the agent.
That is the same shape as the supplier example: one document, several tables, one prediction, one search, one human decision.
Chat assistants already in use
These are real products and research systems. We list them to show the patterns, not to endorse any of them.
- Ambient clinical documentation. Microsoft Dragon Copilot (which grew out of Nuance DAX) and Abridge listen to a consultation and draft the note for the clinician to edit. NHS England published guidance on ambient voice technology in 2025, covering clinical safety, data protection and the need for the clinician to review every note. This is the document lane in reverse: the AI writes the document.
- Patient-facing triage and self-referral. Limbic Access is used by NHS Talking Therapies services for self-referral and is certified as a Class IIa medical device in the UK. It is a good example of a chatbot whose scope is deliberately narrow and regulated.
- Non-diagnostic care agents. Hippocratic AI builds voice agents for tasks such as pre-operative reminders and post-discharge check-ins, and announced a partnership with NVIDIA in 2024. The design choice that matters is "non-diagnostic": the agent follows up and escalates, it does not diagnose.
- Evidence search for clinicians. OpenEvidence answers clinical questions from the published literature with citations. It is the document lane run over journals rather than a hospital's own files.
- Medical models. Google's MedGemma is an open-weight family for medical text and images, and its AMIE research system studies diagnostic dialogue. Open weights mean a hospital can run them on its own hardware and test them on its own data.
- A warning from history. Babylon Health's symptom checker was widely promoted and the company collapsed in 2023. Ambitious diagnostic claims without matching evidence are the fastest way to lose clinicians' trust.
Robots in hospitals
- Surgical systems such as Intuitive's da Vinci and CMR Surgical's Versius (built in Cambridge) are teleoperated: the surgeon is in control. Research is moving towards autonomy for parts of a procedure. In 2025 a Johns Hopkins team reported a robot performing the steps of a gallbladder removal autonomously on ex vivo tissue, not on patients.
- Logistics robots such as Diligent Robotics' Moxi fetch and deliver supplies and samples so nurses spend less time walking. Pharmacy dispensing robots are already common in NHS hospital pharmacies.
- The NVIDIA stack for this work is Holoscan for real-time sensor and video processing in medical devices, Isaac for Healthcare for simulating and training medical robots, and MONAI, the open-source medical imaging framework NVIDIA started with King's College London.
Robots are where the knowledge foundation meets the physical world. A delivery robot needs the table lane (which ward, which bed, which sample is urgent) far more than it needs a chatbot.
The UK rules that shape the design
- Clinical safety: DCB0129 for the manufacturer and DCB0160 for the organisation deploying the system, each with a named clinical safety officer and a hazard log.
- Medical device law: software that diagnoses or recommends treatment may be a medical device under MHRA rules. The MHRA's AI Airlock is a regulatory sandbox for exactly these products. In the EU, the AI Act treats AI in medical devices as high risk.
- Data protection: health data is special category data under UK GDPR. Expect a data protection impact assessment, and keep identifiable data out of prompts, logs and model training unless there is a lawful basis.
- Buying: NHS organisations assess suppliers with the Digital Technology Assessment Criteria (DTAC) and the Data Security and Protection Toolkit (DSPT).
- Research access: NHS secure data environments and trusted research environments such as OpenSAFELY bring the code to the data rather than the other way round. An agent that runs inside that boundary, on hardware the organisation controls, fits this model far better than one that sends records to an outside API.
Scientific research: the same two lanes
Labs have the same split. Knowledge lives in papers, preprints, electronic lab notebooks, protocols and instrument manuals. Measurements live in the laboratory information management system (LIMS), plate readers, sequencers and simulation output, often in volumes that only GPUs handle comfortably.
The supplier example, in a lab
- A reagent supplier issues a lot recall. The notice is parsed.
- The LIMS shows every sample and plate that used that lot.
- An analytical query (cuDF or SQL) checks whether results from that lot drifted against controls. A predictive model flags which downstream experiments are most likely affected.
- Vector search over the lab's SOPs and notebooks finds the validated alternative reagent and any earlier bridging study.
- The agent drafts a re-run plan. A scientist approves it, and a liquid-handling robot executes the protocol.
Frameworks and models scientists already use
- Biology and chemistry models. NVIDIA BioNeMo packages models and training recipes for proteins, DNA and small molecules, including Evo 2, built with the Arc Institute. AlphaFold 3 from Google DeepMind and Isomorphic Labs predicts structures and interactions, and its creators shared the 2024 Nobel Prize in Chemistry. Open alternatives include OpenFold and Boltz, and EvolutionaryScale's ESM3 generates proteins.
- Data at scale. RAPIDS and cuDF speed up tabular work. The scverse project's rapids-singlecell runs single-cell analysis on GPUs. NVIDIA Parabricks accelerates genome sequencing pipelines. Earth-2 and PhysicsNeMo cover climate and physics simulation.
- Research agents. Coscientist (Carnegie Mellon, 2023) and ChemCrow showed language-model agents planning and running chemistry with tools. FutureHouse's PaperQA2 answers questions from the literature with citations. Google's AI co-scientist (2025) generates and ranks hypotheses. NVIDIA's AI-Q blueprint is a reference design for research assistants built on the parts in the slide.
Lab robots and self-driving labs
- Liquid handlers. Opentrons robots are programmed with an open Python protocol API, which makes them a natural tool for an agent to call: the agent writes or selects a protocol, a scientist reviews it, the robot runs it.
- Mobile robotic chemists. The University of Liverpool's mobile robot chemist, reported in Nature in 2020, ran hundreds of experiments over days and chose what to try next. Berkeley Lab's A-Lab automated materials synthesis. Some of its discovery claims were disputed, which is a useful reminder that autonomous labs need independent checking.
- Cloud labs such as Emerald Cloud Lab let scientists run experiments remotely in code.
- Robot learning. Isaac Sim and Isaac Lab simulate robots before they touch a real bench. Cosmos generates synthetic training video. GR00T is NVIDIA's foundation model for humanoid robots. In open source, ROS 2 and MoveIt remain the standard plumbing, and Hugging Face's LeRobot and Physical Intelligence's openpi publish robot policies anyone can fine-tune.
Five design rules that hold in both fields
- Route by data shape. Documents go to retrieval. Tables go to SQL, analysis or prediction. Ask the agent to say which lane it used.
- Cite or stay silent. Every answer about a patient or an experiment should link to the passage or query behind it. If retrieval finds nothing, the right answer is "I could not find this".
- Read-only by default. The agent proposes. A clinician, pharmacist or scientist approves. Writes to the record, orders and robot runs go through a separate, logged step.
- Evaluate on your own data. Build a test set of real questions with known answers from your own documents and tables, and run it every time a model, parser or prompt changes. Public leaderboards do not know your formulary or your assay.
- Keep sensitive data where it is. Open-weight models such as Nemotron, Llama, Qwen and MedGemma can run on hardware inside the hospital or the lab. That makes data protection, audit and research-governance conversations much shorter.
What a sensible first project looks like
Pick one question that people already answer by hand, that needs both a document and a table, and where a wrong answer is caught by a person before it matters. Shortage worklists, discharge-summary drafting reviewed by the clinician, literature triage for a research group or reagent-recall impact reports are all good candidates. Run it on a single GPU workstation inside your network, measure accuracy against your test set for a month, and only then talk about scale.
If you want help sizing that machine, or running the open models on hardware you own, talk to us. Our private-AI workstation guide shows the sizing method for another regulated profession.
Product and research names are given as examples of real systems and are trademarks of their owners. Nothing here is clinical, regulatory or legal advice. Check your own clinical safety, medical device and data protection obligations before deploying AI with patients or patient data.