
Asking an LLM to "make this faster" feels free, but every round of generation burns energy, and the code that comes back is often no more efficient than what you had. A 2026 study found that LLM-optimised code used more energy per run than the human reference in 42 of 44 configurations. This guide explains the break-even maths, how to measure energy yourself, and when an LLM optimisation pass is worth it.
Two energy bills, not one
When you use a large language model (LLM) to optimise code, you pay twice. First comes generation energy: the GPUs and CPUs running the model while it writes and rewrites the code. Then comes execution energy: the joules your service spends every time the resulting code runs in production. Most teams think about neither, and the few that do tend to look only at the second.
The most direct evidence on both comes from "Green Code or Costly Code?" by Emami and colleagues (October 2026) [1]. The authors asked 11 open-source models to iteratively self-optimise Python solutions to all 1,000 problems in the EffiBench performance benchmark, over five rounds of refinement, under four decoding configurations. They measured energy at hardware level using Intel RAPL counters (the CPU's built-in energy meters), nvidia-smi and performance counters, on a server with two NVIDIA L40 GPUs serving models through vLLM [1].
What the study found
- Generation is expensive. A full optimisation run over the benchmark used between 0.79 and 8.68 MJ (roughly 0.22 to 2.4 kWh) depending on model and settings [1].
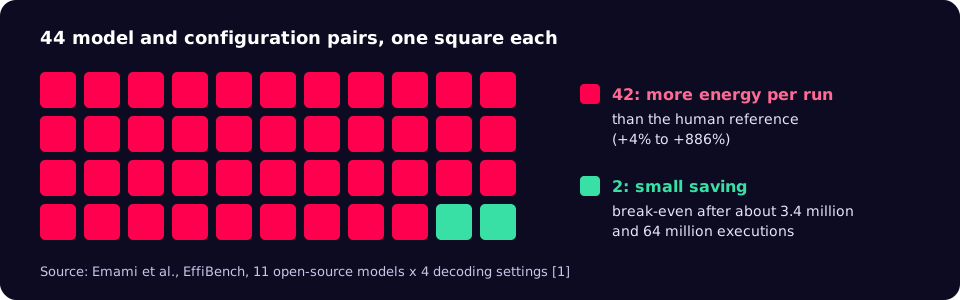
- The output was usually worse. In 42 of 44 model and configuration pairs, the optimised code used more energy per problem than the canonical human solution, with overheads from +4% to +886% [1].
- Iterating often made it worse still. In 24 of 44 configurations (54.5%), the code regressed over the optimisation trajectory, ending up less efficient than the model's own first attempt [1].
- Even the winners barely won. The two configurations that beat the human reference would need about 3.4 million and 64 million executions per problem respectively before the energy saved repaid the energy spent generating it [1].
- Output caps and model architecture matter most. Halving the maximum output tokens cut energy by up to 69% (for GLM-4.7-Flash), and Mixture-of-Experts (MoE) models, which activate only part of their network per token, used substantially less inference energy than dense models of similar size without losing correctness [1].
The caveats matter, and the authors list them. EffiBench problems are short Python functions, so long-running or I/O-bound workloads may behave differently. The human baselines are top-rated solutions, a strong bar. Only open-source models running on-premise were tested, and only operational energy was counted, not the embodied energy of the hardware [1]. The finding is not "LLMs write wasteful code"; it is "do not assume an optimisation pass saves anything until you have measured it".
The break-even rule
The study frames the question with a simple formula. If generation cost Egen joules and the new code saves ΔE joules per execution, the change pays back after N* = Egen / ΔE executions, and only if ΔE is greater than zero [1]. If the new code is less efficient, there is no break-even point at all.
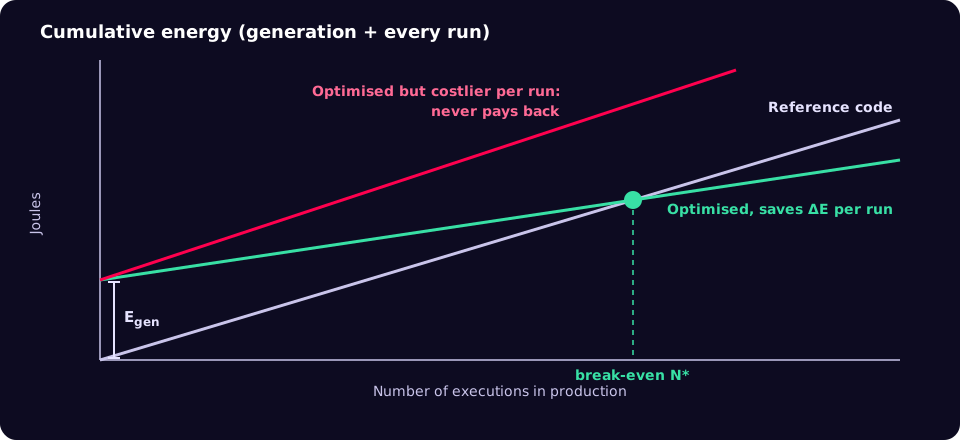
The rule turns a vague sustainability goal into an engineering decision. Here is a worked example with illustrative numbers. Suppose a long LLM optimisation session costs 1 kWh (3.6 MJ) of generation energy and the new function saves 0.5 J per call. Break-even is 7.2 million calls. A pricing endpoint serving 50 calls a second reaches that in under two days. A nightly batch job that runs once a day never will. The authors' recommendation follows directly: restrict LLM-based optimisation to hot-path code with reliably high execution frequency [1].
# break_even.py
import math


def break_even_runs(gen_joules: float, old_j_per_run: float,
                    new_j_per_run: float) -> int | None:
    """Executions needed before generation energy is repaid.
    Returns None if the new code saves nothing per run."""
    saving = old_j_per_run - new_j_per_run
    if saving <= 0:
        return None
    return math.ceil(gen_joules / saving)


runs = break_even_runs(gen_joules=3.6e6, old_j_per_run=2.0, new_j_per_run=1.5)
print(runs)                        # 7200000
print(runs / (50 * 86_400))        # days at 50 calls/s: about 1.67
You will often not know Egen exactly when you use a hosted model. Published per-request figures help with orders of magnitude only. Google, for example, estimated that the median Gemini Apps text prompt in May 2025 used 0.24 Wh, about 0.03 g CO2e and 0.26 ml of water, counting idle capacity, host CPU and RAM and data-centre overhead [2][3]. Google notes these figures were not independently verified [2], and a median chat prompt is far smaller than an agentic coding session that reads files and rewrites code over many turns, so do not multiply it by your request count and call that your footprint.
Where the energy goes, lever by lever
| Lever | Effect on generation energy | Effect on execution energy | Evidence |
|---|---|---|---|
| Cap maximum output tokens | Lower; up to 69% in one model | Neutral, but correctness fell sharply for some models | [1] |
| MoE model instead of a dense one | Substantially lower than a dense model of similar size | No loss of correctness reported | [1] |
| More refinement rounds | Higher with every round | Often worse: 24 of 44 configurations regressed | [1] |
| Repeated sampling (generate many, keep the best) | Rises with the number of samples | Depends entirely on how you pick the winner | [4] |
| Compiler and profiler first | None | Often the cheapest win | [5] |
Two of these rows deserve a note. On output caps, the study's halved limit hurt some models badly: two MoE models with a 1,024-token cap fell to 12.5% and 4.8% pass rates [1]. Saving energy on code that does not work is not a saving. On repeated sampling, OpenAI's original Codex paper showed why it is tempting: Codex solved 28.8% of HumanEval problems with one sample and 70.2% with 100 samples per problem [4]. That is a large correctness gain bought with up to a hundred times the generation.
The compiler row is a reminder of how strong the baseline is. Meta's work on LLMs for compiler optimisation trained a 7-billion-parameter model to choose LLVM optimisation passes for code size, and it improved instruction counts by 3.0% over the compiler's own optimisation [5]. Real, but modest. Before asking a model to rewrite a function, make sure you have turned on the optimisations your toolchain already offers and profiled where time actually goes.
A measured workflow for LLM optimisation
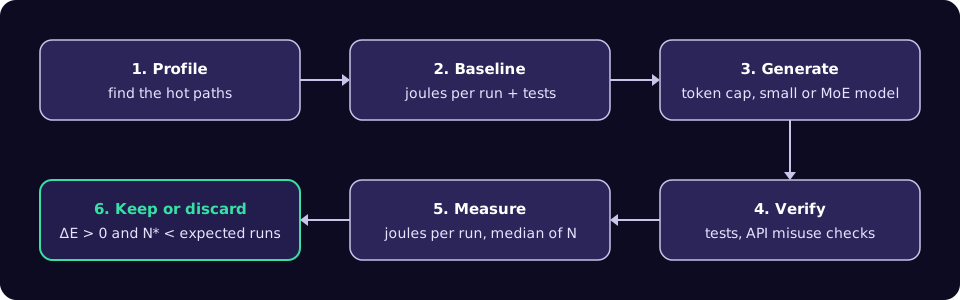
- Profile first. Use your normal profiler or APM traces to find functions with high call counts or high CPU time. Write down calls per day for each candidate; that number is your expected runs.
- Baseline. Measure joules per run for the current code with the harness below, and make sure its tests pass.
- Generate narrowly. Ask for one function, not a file with commentary. Set
max_tokensexplicitly, prefer a smaller or MoE model for routine rewrites, and limit refinement to one or two rounds rather than letting a loop run [1]. - Verify correctness and API use. Generated code can look right and still misuse libraries. In the RobustAPI study of 1,208 Stack Overflow questions covering 24 Java APIs, even GPT-4's answers contained API misuse in 62% of cases, which the authors note can lead to resource leaks and crashes [6]. A leaked connection costs more energy than any micro-optimisation saves.
- Measure the candidate on the same machine, same input, same number of runs, and compare medians.
- Decide with the formula. Keep the change only if ΔE is positive, outside run-to-run noise, and N* is well below the expected runs over the code's likely lifetime.
Measuring joules per run on Linux
On Intel and recent AMD CPUs, Linux exposes RAPL energy counters through perf. Check that the event exists, then run your benchmark several times:
perf list | grep -i energy
sudo perf stat -a -r 10 -e power/energy-pkg/ -- python3 bench_reconcile.py
If you prefer to script it, the same counter is readable from the powercap interface (root is required on most current kernels). This harness takes the median over several runs and handles counter wrap-around:
# joules.py: usage: sudo python3 joules.py python3 bench_reconcile.py
import subprocess
import sys
from pathlib import Path

ZONE = Path("/sys/class/powercap/intel-rapl:0")  # CPU package 0


def read_uj() -> int:
    return int((ZONE / "energy_uj").read_text())


def median_joules(cmd: list[str], runs: int = 10) -> float:
    max_uj = int((ZONE / "max_energy_range_uj").read_text())
    samples = []
    for _ in range(runs):
        start = read_uj()
        subprocess.run(cmd, check=True)
        end = read_uj()
        delta = end - start if end >= start else end + max_uj - start
        samples.append(delta / 1e6)
    samples.sort()
    return samples[len(samples) // 2]


if __name__ == "__main__":
    print(f"median {median_joules(sys.argv[1:]):.2f} J per run")
Package counters include everything else the machine is doing, so run on a quiet host, measure an idle baseline for the same duration, and compare old and new code on the same host in the same session. For GPU code, sample board power with nvidia-smi and integrate over time:
nvidia-smi --query-gpu=power.draw --format=csv,noheader,nounits -lms 200 > gpu_power.csv &
SAMPLER=$!
python3 bench_gpu.py
kill $SAMPLER
awk '{ j += $1 * 0.2 } END { printf "%.0f J\n", j }' gpu_power.csv
Checklist for an energy-aware optimisation
- The target function is on a measured hot path, with a known call rate.
- Toolchain optimisations and a profiler pass were tried first.
- Baseline joules per run and passing tests recorded before any generation.
max_tokensset explicitly; refinement rounds capped.- Smallest model that passes your tests used for routine rewrites.
- Generated code reviewed for API misuse: resources closed, errors handled, retries bounded.
- Old and new code measured on the same host, same inputs, median of several runs.
- Break-even calculated and written into the pull request description.
Common mistakes
- Assuming "optimised" means efficient. The study's main result is that it usually did not [1].
- Letting the model iterate unattended. More rounds cost more energy and, in over half the configurations, made the code worse [1].
- Measuring wall-clock time only. Faster code that spreads work across more cores can use more energy, not less. Measure joules.
- Single-run comparisons. Energy counters are noisy; compare medians over repeated runs.
- Optimising cold code. A monthly report job will not repay a long generation session.
- Treating per-prompt estimates as your footprint. Published averages describe someone else's workload [2].
What to do this week
- Pull call counts for your ten busiest functions from your profiler or tracing and mark the top three as the only candidates for LLM optimisation.
- Run
perf stat -e power/energy-pkg/on one of them and record the baseline joules per run. - Set an explicit
max_tokensand a round limit in whatever coding assistant or pipeline your team uses for refactors. - Add a "break-even" line to your pull request template for performance changes: joules saved per run, generation estimate and expected runs.
- Re-measure one recent LLM-suggested "optimisation" against the code it replaced.
Most of the energy in AI-assisted engineering is spent where nobody is measuring it. If you run models on your own hardware and want generation energy to be visible alongside everything else, our private AI work covers instrumenting on-premise inference as well as running it.
References
- Emami, Weigell, Mousavi, Jahangirova, Araujo and Bauer, "Green Code or Costly Code? Evaluating the Energy Costs of Iterative LLM-Based Code Optimizations", arXiv:2610.32891 (October 2026)
- Google Cloud, "Measuring the environmental impact of AI inference" (21 August 2025)
- Elsworth et al., "Measuring the environmental impact of delivering AI at Google Scale", arXiv:2508.15734 (August 2025)
- Chen et al., "Evaluating Large Language Models Trained on Code", arXiv:2107.03374 (July 2021)
- Cummins et al., "Large Language Models for Compiler Optimization", arXiv:2309.07062 (September 2023)
- Zhong and Wang, "Can ChatGPT replace StackOverflow? A Study on Robustness and Reliability of Large Language Model Code Generation", arXiv:2308.10335 (August 2023)