Technote · for platform, network and SRE engineers
NVIDIA Minerva AIOps in Practice: Architecture, Telemetry, Safe Agents, Ansible Remediation and a Phased Rollout
A practitioner's guide to deploying NVIDIA Minerva, NVIDIA's AIOps platform for AI factories, and fitting it into an existing operations estate. It covers the architecture and data flow, the telemetry sources layer by layer, how topology-aware correlation turns an event storm into one incident, safe use of the Sherlock assistant and the MCP server, closed-loop remediation with Ansible under change control, the three consumption models as reference architectures, integration with Prometheus, Grafana, the Elastic stack, ServiceNow and PagerDuty, on-premises versus SaaS and UK GDPR, HA and sizing for the collector tier, a phased rollout runbook and the fault drills we run at handover. The business case is in the companion blog post.
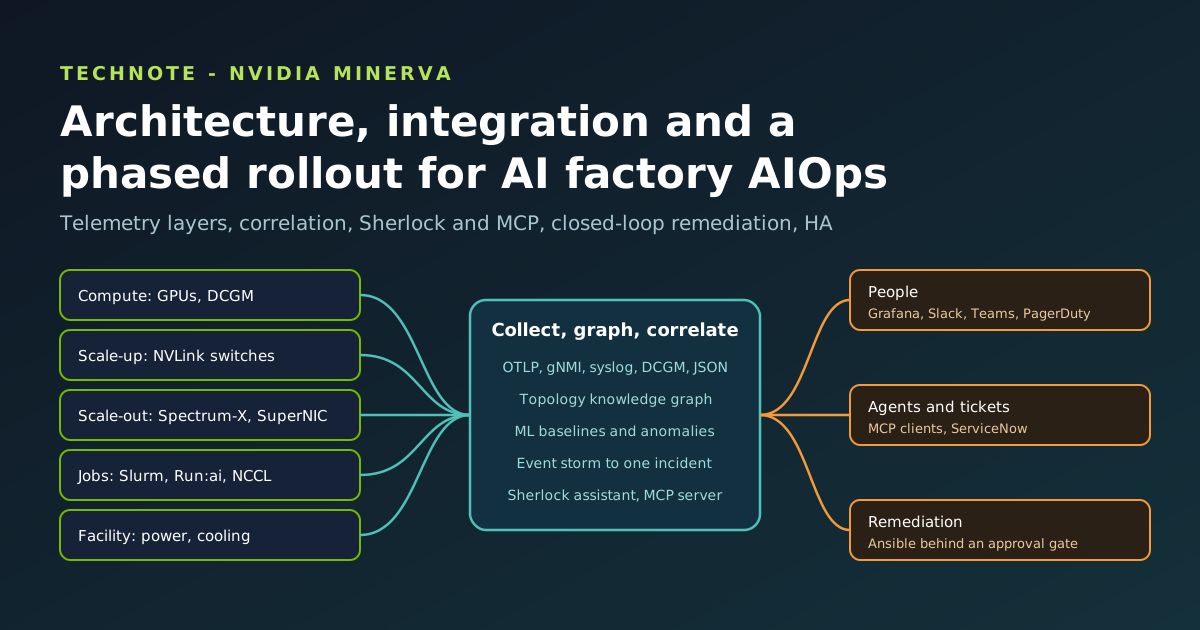
Summary. Minerva collects telemetry from all layers of an AI factory through open standards, keeps a live graph of how hardware, fabrics and jobs connect, learns baselines with machine learning, and uses the graph to group related alerts into one incident with a probable cause and a blast radius. Around it, we deploy only open, verifiable components: an OpenTelemetry Collector pair for sources and backends the customer already has, dcgm-exporter and Slurm metadata, Prometheus rules and Alertmanager for the monitoring of the monitoring, and Ansible playbooks that run only behind an approval gate. Minerva-side endpoints, schemas and settings are configured per NVIDIA's Minerva documentation; this article does not invent them.
Scope and honesty note. This article was written from NVIDIA's public product page and datasheet for Minerva, not from its technical documentation. We therefore describe Minerva's own internals, APIs and configuration only at the level NVIDIA has published, and we do not show Minerva configuration files, CLI commands, metric names or prices. Every configuration block below is for an open component around Minerva and was validated with that component's own tooling; see section 15, Sources and verification notes.
1. What Minerva is, from NVIDIA's own description
NVIDIA announced Minerva in October 2026. Its official NVIDIA Minerva page and the Minerva datasheet are the authoritative sources. Summarised in our own words, the published facts we design around are:
| Topic | What NVIDIA states (paraphrased) | What it means for the design |
|---|
| Positioning | An end-to-end AIOps platform designed around AI and the primary observability product for NVIDIA AI factories, including Vera Rubin and Blackwell systems. | Treat it as the incident brain for the GPU estate, not as one more dashboard. |
| Telemetry scope | GPUs, NVLink switches, Spectrum-X Ethernet, SuperNICs, DPUs, NCCL, schedulers such as Slurm and Run:ai, storage and AI workloads. | Plan collection per layer; see section 3. |
| Ingest standards | OpenTelemetry, gNMI, syslog, DCGM, Slurm and JSON. | Existing OpenTelemetry pipelines can forward to it; switches stream with gNMI. |
| Analytics | A dynamic, topology-aware knowledge graph; ML that learns normal behaviour over billions of data points an hour; automated root-cause analysis when jobs straggle or fail; noise reduction that merges event storms into one incident. | Give it accurate topology and job metadata, then a baselining period before paging. |
| Interaction | Sherlock, a multi-agent assistant for natural-language triage on live telemetry, and an MCP server so customer agents can integrate. | Govern agent access like any privileged API; see section 6. |
| Action | Remediation recommendations and closed-loop remediation; integrations with Slack, Microsoft Teams, ServiceNow, PagerDuty, Ansible, Grafana and infrastructure APIs. | Route through change control; see section 7. |
| Facility | The Minerva Collector is part of NVIDIA DSX OS, giving a GPU-to-grid view with facility signals correlated. | Bring power and cooling into the same incident timeline. |
| Deployment | On premises or as SaaS from NVIDIA's cloud; scales to hundreds of thousands of GPUs; data sovereignty preserved; open APIs, modular capabilities and Grafana integration. | Decide the hosting model early; see section 10. |
| Consumption | DIY Observability, AIOps with DIY Observability, and Turnkey. | Three reference architectures; see section 8. |
| Outcomes | Framed as GPU hours, goodput, uptime, MTBI, MTTR and token production. | Report on the same KPIs from day one. |
Minerva and UFM
Our UFM, DCGM and OpenTelemetry technote covers NVIDIA Unified Fabric Manager, which manages and monitors InfiniBand fabrics. NVIDIA's Minerva material names Spectrum-X Ethernet (scale-out, scale-across and scale-in) and NVLink (scale-up) as its network scope and does not, in what we read, describe InfiniBand ingestion. On a mixed site we keep UFM as the InfiniBand fabric manager and confirm with NVIDIA, for the release being deployed, how UFM events and telemetry should reach Minerva. Until that is confirmed, the OpenTelemetry tier in section 9 can carry UFM data to the customer's existing backends exactly as in the UFM technote.
2. Architecture and data flow
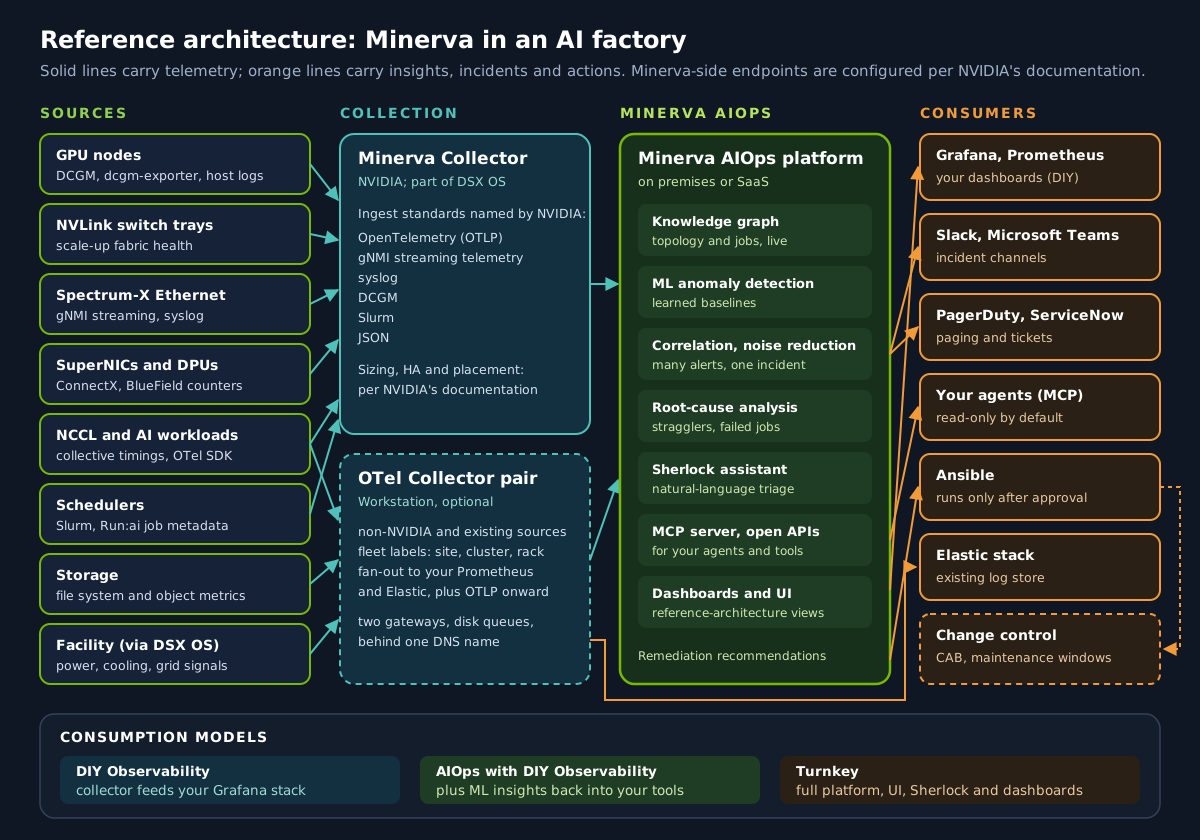
We think about a Minerva deployment as four planes. Keeping them separate makes ownership, security and failure modes easy to reason about.
- Collection plane. The Minerva Collector, plus our optional OpenTelemetry Collector pair for anything the customer already gathers or must also send elsewhere. Its job is to get every signal off the source once, add consistent identity (site, cluster, rack, node, rail, job), buffer through outages and forward.
- Analytics plane. Minerva itself: the knowledge graph, baselines, anomaly detection, correlation, root-cause analysis and the incident store. On premises it runs on infrastructure we size with NVIDIA; as SaaS it runs in NVIDIA's cloud.
- Interaction plane. Minerva's UI and dashboards, Sherlock, the MCP server for customer agents, and Grafana where the customer keeps its own views.
- Action plane. Notifications (Slack, Teams), paging and tickets (PagerDuty, ServiceNow), and automation (Ansible). Everything here is governed by the customer's change process.
A signal's path is: source, to collector (labelled and buffered), to the analytics plane (attached to a node in the graph, compared with its baseline), to an incident (grouped with related anomalies), to people and agents (notified once, with context), and possibly to an approved action, whose result flows back in as telemetry so the incident can be verified and closed.
3. Telemetry sources, layer by layer
The table lists each layer, what goes wrong there, the ingest standard NVIDIA names for it, and the open components we deploy or check around it. Where we write "Minerva Collector", how that source is enabled is configured per NVIDIA's Minerva documentation.
| Layer | Typical faults | Ingest route named by NVIDIA | Open components we deploy or check |
|---|
| GPU (compute) | XID errors, ECC and row-remap events, thermal or power throttling, idle GPUs in running jobs | DCGM | DCGM host engine; dcgm-exporter where the site also keeps Prometheus copies |
| NVLink scale-up | Link recovery events, degraded links inside an NVL72 domain, switch tray faults | Minerva Collector (NVLink switches) | DCGM per-GPU NVLink counters as a cross-check |
| Spectrum-X Ethernet | Drops, PFC pause storms, ECN marking, buffer pressure, flapping links, optics running hot | gNMI streaming, syslog | Switch gNMI subscriptions and syslog forwarding; our syslog receiver for existing stores |
| SuperNICs and DPUs | Congestion control events, retransmits, port errors, DPU health | Minerva Collector | BlueField DOCA Telemetry Service where already deployed |
| NCCL | Slow or hung collectives, one rank lagging the rest | Minerva Collector (NCCL telemetry) | Job logs with NCCL debug output captured to the log store |
| Schedulers | Jobs failing or stuck, nodes drained, GPUs allocated but idle | Slurm; Run:ai | Slurm prolog and epilog for dcgm-exporter job mapping; Kubernetes metadata |
| Storage | Checkpoint writes slowing, metadata latency, client errors | OpenTelemetry, JSON, syslog | The storage vendor's exporter forwarded through our gateways |
| Workloads | Step time rising, time to first token rising, token throughput dropping | OpenTelemetry | OpenTelemetry SDK in model servers and training harnesses |
| Facility | Power capping, coolant temperature or flow excursions, PDU faults | Minerva Collector in DSX OS | Building management integration, configured per NVIDIA's DSX OS documentation |
GPUs: DCGM and dcgm-exporter
DCGM is the GPU health and telemetry service NVIDIA names as a Minerva source. Where a customer also keeps GPU metrics in its own Prometheus, we run dcgm-exporter as well. Note that dcgm-exporter 4.9.0 renamed its default metrics and changed several units (utilisation became a 0 to 1 ratio, memory became bytes); the full table and a bridging recording-rule set are in our UFM and DCGM technote. All PromQL in this article uses the 4.9.0 names.
Spectrum-X switches: gNMI and syslog
gNMI is the OpenConfig gRPC protocol for streaming telemetry from network devices. In general terms we subscribe to interface counters in sample mode at a fixed interval and to operational state (link up or down, transceiver alarms) on change, which keeps load low while making state changes immediate. Which paths Minerva subscribes to, and whether it dials in to the switches or they dial out to it, is set per NVIDIA's documentation and the switch operating system's own guide; we only make sure the management network, certificates and access lists allow it. Syslog from every switch goes to the collector as well, because flaps and transceiver alarms often appear there first.
Schedulers: Slurm and Run:ai
Correlation is only as good as the job-to-hardware map. For Slurm we confirm that job, user, partition and node-list metadata reach Minerva as NVIDIA documents, and we use the Slurm prolog and epilog to maintain dcgm-exporter's HPC job mapping so that GPU series carry an hpc_job label in the customer's own Prometheus. For Run:ai and Kubernetes we check that workload and project names flow through. User names are personal data; see section 10 for how we pseudonymise them where they leave the site.
Workloads: OpenTelemetry SDK
Model servers and training harnesses instrumented with the OpenTelemetry SDK send traces and metrics over OTLP to the gateway pair, which forwards them to Minerva and, if the customer wants, to its own trace store. The signals that matter most are step time and data-loader wait for training, and queue time, time to first token and tokens per second for inference.
4. The knowledge graph and topology-aware correlation
NVIDIA has not published Minerva's internal algorithms in the material we read, so this section explains the idea in general terms, which is what operators need to feed it well.
A knowledge graph here is a live model of the estate: entities (GPUs, NVLink switch trays, nodes, NICs, switch ports, switches, racks, power feeds, storage targets, jobs, tenants) and relationships between them (this GPU is in this node; this NIC port is cabled to that leaf port; this job runs on these 72 GPUs; this rack draws from that power feed). Relationships change over time, especially job placement, so each one has a time range.
Correlation then works roughly like this:
- Anomalies are attached to entities. A rise in FEC corrections belongs to a switch port; a slow all-reduce belongs to a job; a utilisation dip belongs to a GPU.
- Anomalies close in time are tested for a shared path in the graph. If the slow job's GPUs all reach the fabric through NICs cabled to one leaf, and that leaf has a degrading port, the port is a candidate root cause and everything downstream is a symptom.
- Candidates are ranked. Upstream position, how early the anomaly began, how far it departs from baseline, and how many symptoms it explains all count.
- The blast radius is computed by walking the graph downstream: which jobs, tenants and GPUs depend on the suspected component right now.
Two practical consequences follow. First, topology accuracy is a precondition: an uncabled or mislabelled port in the inventory produces wrong root causes. We validate the cabling plan against LLDP and the switches' own view before baselining. Second, job metadata must be timely: if job placement arrives minutes late, symptoms cannot be tied to the job they hurt.
5. Noise reduction and the incident lifecycle
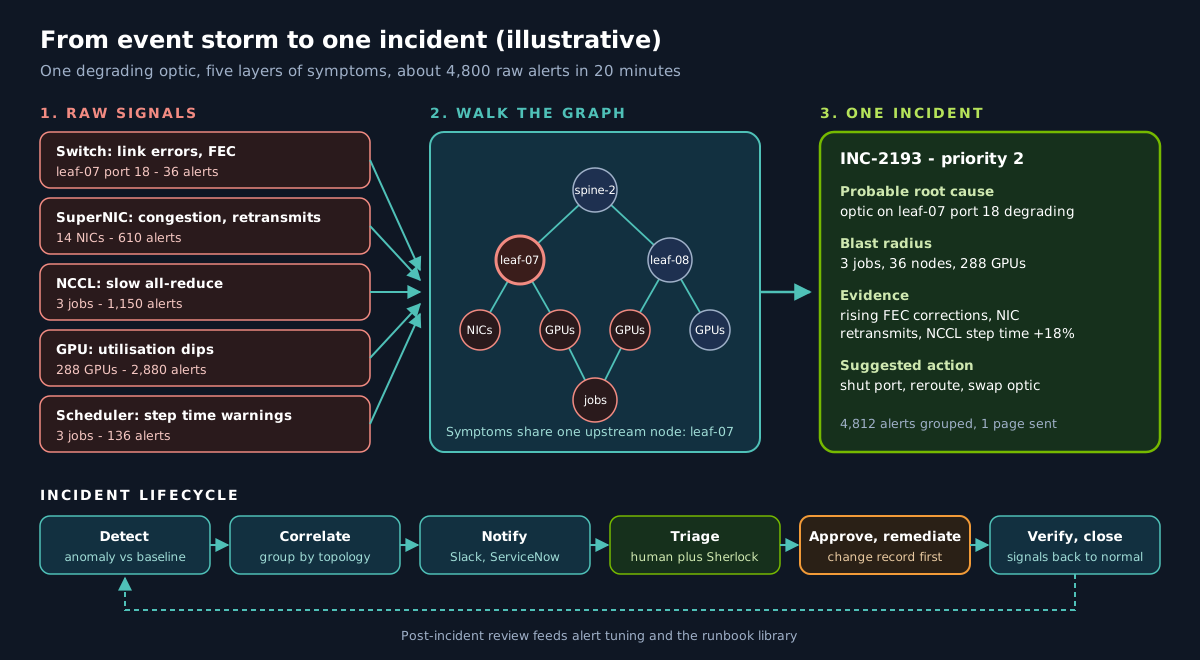
In a large AI fabric a single physical fault can raise thousands of alerts, because every GPU, NIC and job that touches it reports its own symptom. NVIDIA describes Minerva grouping these into one prioritised incident with context, delivered to tools such as Slack or ServiceNow. Our job is to make that incident flow fit the customer's operations model:
| Stage | What happens | What we configure around it |
|---|
| Detect | Anomaly against learned baseline, or a hard threshold breach | Baselining period with paging off (section 12) |
| Correlate | Related anomalies grouped by topology and time | Accurate topology and job metadata (section 4) |
| Notify | One message per incident, updated as it evolves | Routing per tenant and severity to Slack or Teams, PagerDuty and ServiceNow |
| Triage | Engineer reviews cause and blast radius, may ask Sherlock | Runbook links per incident type; read-only agent access |
| Approve and remediate | Suggested action approved and executed | Change record, approval gate, Ansible job (section 7) |
| Verify and close | Signals return to baseline; incident resolved | Automatic resolve in ServiceNow and PagerDuty; post-incident review |
Avoid paging twice
When Minerva handles correlation, the customer's existing per-symptom alerts for the same hardware must not page as well. Our rule of thumb: in the AIOps and Turnkey models, existing Prometheus alerts for GPU, NIC and switch symptoms drop to ticket severity (or are inhibited), and only alerts about the monitoring itself, such as collector and intake failures, keep page. For ServiceNow and PagerDuty, check that the incident identifier Minerva sends is used as the de-duplication key, so updates to one incident never open a second ticket; how Minerva populates that field is configured per NVIDIA's documentation.
6. Sherlock and MCP: using agents safely
Sherlock is Minerva's multi-agent assistant for natural-language triage, and the MCP server lets the customer's own agents ask Minerva questions. Both are powerful because they see the whole estate. We treat them as privileged interfaces and apply the same controls we would to any automation account:
- Read-only by default. Agents start with access to query telemetry, incidents and topology only. No agent identity holds rights to change infrastructure in the first phase of a rollout.
- Separate identities. Each agent or integration uses its own service identity with its own scope, never a shared administrator account, so actions are attributable and revocable.
- Approval gates for anything that changes state. An agent may propose a drain, a port shutdown or a restart; a named human approves it, and execution happens through the change-controlled automation in section 7, not through the agent's own credentials.
- Treat telemetry as untrusted input. Job names, log lines and hostnames can contain text written by users. An agent that reads them can be steered by instructions planted in them. Agents must not execute actions on the strength of text found in telemetry, and tool permissions must be enforced server-side, not by the prompt.
- Log every conversation and tool call to the audit store, with the identity, the question, the tools used and the answer. Review a sample weekly during the first months.
- Keep secrets out of context. Credentials never appear in prompts, answers or tool outputs; scope MCP tools so they cannot return them.
- Rate limits and budgets. Cap how many queries an agent can make per minute so a looping agent cannot load the platform.
| Action class | Examples | Who may trigger | Approval |
|---|
| Read | Ask about an incident, list stragglers, show a job's path through the fabric | Sherlock, MCP clients, engineers | None; logged |
| Annotate | Add a note to an incident, link a ticket | Sherlock, MCP clients with write-notes scope | None; logged |
| Reversible operational change | Drain a node in Slurm, move a job at its next checkpoint, shut a single flapping port | Engineer, or an agent proposing | Named approver; standard change record |
| Disruptive change | Reboot nodes, reflash firmware, change fabric configuration | Engineer only | Normal change with CAB approval and a maintenance window |
NVIDIA describes Minerva recommending fixes and closing the loop through integrations including Ansible. We introduce automation in three levels, and a customer moves up a level only when the previous one has a clean record:
- Suggest. The incident carries a recommended action and a link to the runbook; a person does the work.
- Approve to run. The recommended action maps to a pre-written Ansible playbook in the automation controller (AWX or Red Hat Ansible Automation Platform). An approval step in the workflow, tied to a ServiceNow standard change, lets a named approver run it with one click.
- Pre-approved standard changes. A short list of low-risk, reversible actions, such as draining a node with repeated XID errors, runs without a human click, still under a standard change template and still logged. Disruptive actions never reach this level.
How Minerva hands an action to the automation controller (webhook, API call or ServiceNow trigger) is configured per NVIDIA's Minerva documentation. The playbook itself is ours and is deliberately defensive: it refuses to run without a change and incident reference, drains rather than kills, waits for running jobs, runs a DCGM diagnostic, and leaves the node drained for an engineer to resume.
# playbooks/drain-gpu-node.yml
# Runs only from the automation controller, only with an approved change record.
# Usage: ansible-playbook drain-gpu-node.yml -l gpu-r09-02 \
#          -e change_id=CHG0041234 -e incident_id=INC-2193 -e approved_by=ops-lead
- name: Drain a GPU node and run DCGM diagnostics
  hosts: gpu_nodes
  serial: 1
  gather_facts: false
  vars:
    drain_wait_minutes: 60
  tasks:
    - name: Refuse to run without an approved change and incident reference
      ansible.builtin.assert:
        that:
          - change_id is defined and change_id is match('^CHG[0-9]+$')
          - incident_id is defined and incident_id | length > 0
          - approved_by is defined and approved_by | length > 0
        fail_msg: "change_id, incident_id and approved_by are required"

    - name: Drain the node in Slurm so no new jobs land on it
      ansible.builtin.command:
        argv:
          - scontrol
          - update
          - "nodename={{ inventory_hostname }}"
          - state=drain
          - "reason={{ incident_id }} {{ change_id }} via automation"
      delegate_to: "{{ groups['slurm_controllers'][0] }}"
      changed_when: true

    - name: Wait for running jobs on the node to finish
      ansible.builtin.command:
        argv: [squeue, --noheader, --nodelist, "{{ inventory_hostname }}", --format, "%i"]
      delegate_to: "{{ groups['slurm_controllers'][0] }}"
      register: jobs_left
      until: jobs_left.stdout | trim | length == 0
      retries: "{{ drain_wait_minutes }}"
      delay: 60
      changed_when: false

    - name: Run DCGM diagnostics (level 2, a few minutes)
      ansible.builtin.command:
        argv: [dcgmi, diag, -r, "2"]
      become: true
      register: diag
      changed_when: false
      failed_when: false

    - name: Record the result for the change and incident
      ansible.builtin.debug:
        msg: "{{ inventory_hostname }} diag rc={{ diag.rc }}; node stays drained until an engineer resumes it"
Every playbook in the library has a matching rollback (here, scontrol update nodename=... state=resume after the engineer's check), a dry-run mode tested in the lab, and an owner. The automation controller's job log is attached to the change record automatically.
8. The three consumption models as reference architectures
| DIY Observability | AIOps with DIY Observability | Turnkey |
|---|
| Collection | Minerva Collector | Minerva Collector | Minerva Collector |
| Storage and dashboards | Customer's Prometheus or Mimir and Grafana | Customer's Grafana; Minerva insights fed in | Minerva's own dashboards; Grafana optional |
| Anomaly detection and correlation | Customer's own rules | Minerva | Minerva |
| Assistant and agents | None from Minerva | Insights to customer's agentic tools | Sherlock plus MCP |
| Incidents | Alertmanager to Slack and PagerDuty | Minerva to ServiceNow and PagerDuty | Minerva to ServiceNow, PagerDuty, Slack or Teams |
| Our OpenTelemetry pair | Usually yes, for labelling and fan-out | Yes, for existing sources and backends | Only for non-NVIDIA sources |
| Typical customer | Mature SRE team, single cluster | Enterprise with an established toolchain | AI factory or neocloud |
DIY Observability. The collector feeds the customer's Prometheus-compatible store. We deploy the Prometheus rules and Alertmanager routes in section 9, the Grafana dashboards in the companion gallery, and the labelling scheme from the UFM technote. The customer owns correlation; Minerva gives them NVIDIA-aligned, consistent data.
AIOps with DIY Observability. As above, plus Minerva's analytics. The design work is in de-duplication (section 5), routing incidents into the right ServiceNow assignment groups, and showing Minerva's insights next to existing Grafana panels so engineers do not switch tools.
Turnkey. Minerva is the primary operations console. We still keep an independent, minimal Prometheus watching the collectors, the Minerva intake and the dead man's switch, because a monitoring platform must not be the only thing watching itself.
9. Integration with Prometheus, Grafana, Elastic, ServiceNow and PagerDuty
The OpenTelemetry gateway pair
Where the customer already has sources the Minerva Collector does not cover, or must keep a copy in its own backends, we run two OpenTelemetry Collector gateways per site behind one DNS name. This configuration forwards to a Minerva OTLP intake and to the customer's Mimir and Elasticsearch, labels everything with site and cluster, strips known high-cardinality and sensitive attributes, and pseudonymises Slurm user names before data leaves the site. The otlp/minerva endpoint, its authentication and which signals it accepts are placeholders to be configured per NVIDIA's Minerva documentation.
# /etc/otelcol-contrib/config.yaml  (Workstation gateway, two per site)
extensions:
  health_check:
    endpoint: 0.0.0.0:13133
  file_storage:
    directory: /var/lib/otelcol/queue
    create_directory: true

receivers:
  otlp:
    protocols:
      grpc:
        endpoint: 0.0.0.0:4317
        tls:
          cert_file: /etc/otelcol-contrib/tls/gateway.crt
          key_file: /etc/otelcol-contrib/tls/gateway.key

  # Only for nodes the Minerva Collector does not already cover, or when the
  # site keeps its own Prometheus copy of GPU metrics.
  prometheus/nodes:
    config:
      scrape_configs:
        - job_name: dcgm
          scrape_interval: 15s
          file_sd_configs:
            - files: ["/etc/otelcol-contrib/targets/dcgm-*.yaml"]
        - job_name: node
          scrape_interval: 30s
          file_sd_configs:
            - files: ["/etc/otelcol-contrib/targets/node-*.yaml"]
          metric_relabel_configs:
            - source_labels: [__name__]
              regex: "node_(load1|memory_MemAvailable_bytes|filesystem_(avail|size)_bytes|network_(receive|transmit)_(bytes|errs|drop)_total|hwmon_temp_celsius|textfile_.+)"
              action: keep

  syslog/switches:
    tcp:
      listen_address: 0.0.0.0:5514
    protocol: rfc5424

processors:
  memory_limiter:
    check_interval: 1s
    limit_percentage: 75
    spike_limit_percentage: 20
  resource/fleet:
    attributes:
      - key: site
        value: ${env:WS_SITE}
        action: upsert
      - key: cluster
        value: ${env:WS_CLUSTER}
        action: upsert
  transform/hygiene:
    error_mode: ignore
    metric_statements:
      - context: datapoint
        statements:
          - delete_key(attributes, "pod_uid")
          - delete_key(attributes, "container_id")
    log_statements:
      - context: log
        statements:
          - delete_key(attributes, "http.request.header.authorization")
          # pseudonymise scheduler user names before they leave the site
          - set(attributes["slurm.user"], SHA256(attributes["slurm.user"])) where attributes["slurm.user"] != nil
  batch:
    send_batch_size: 8192
    timeout: 5s

exporters:
  # Minerva-side OTLP intake: the endpoint, authentication and which signals
  # it accepts are configured per NVIDIA's Minerva documentation.
  otlp/minerva:
    endpoint: ${env:MINERVA_OTLP_ENDPOINT}
    tls:
      ca_file: /etc/otelcol-contrib/tls/minerva-ca.pem
    sending_queue:
      enabled: true
      storage: file_storage
      queue_size: 10000
    retry_on_failure:
      enabled: true
      max_elapsed_time: 30m

  # The customer's existing Prometheus-compatible store (Mimir here).
  prometheusremotewrite/existing:
    endpoint: https://mimir.obs.internal/api/v1/push
    external_labels:
      replica: ${env:WS_GATEWAY_NAME}
    resource_to_telemetry_conversion:
      enabled: true
    remote_write_queue:
      enabled: true
      queue_size: 20000
      num_consumers: 8

  # The customer's existing Elastic stack, with ECS field names.
  elasticsearch/logs:
    endpoints: ["https://es-hot-1.obs.internal:9200", "https://es-hot-2.obs.internal:9200"]
    logs_index: logs-ai.factory-prod
    mapping:
      allowed_modes: [ecs]
    tls:
      ca_file: /etc/otelcol-contrib/tls/es-ca.pem

service:
  extensions: [health_check, file_storage]
  pipelines:
    metrics:
      receivers: [otlp, prometheus/nodes]
      processors: [memory_limiter, resource/fleet, transform/hygiene, batch]
      exporters: [otlp/minerva, prometheusremotewrite/existing]
    logs:
      receivers: [otlp, syslog/switches]
      processors: [memory_limiter, resource/fleet, transform/hygiene, batch]
      exporters: [otlp/minerva, elasticsearch/logs]
    traces:
      receivers: [otlp]
      processors: [memory_limiter, resource/fleet, batch]
      exporters: [otlp/minerva]
  telemetry:
    metrics:
      level: detailed
      readers:
        - pull:
            exporter:
              prometheus:
                host: 0.0.0.0
                port: 8888
Validated with otelcol-contrib validate from the otel/opentelemetry-collector-contrib:0.165.0 image. Notes on choices:
- Disk-backed queue for the Minerva exporter, so a Minerva upgrade or network break does not lose data; size the volume for at least an hour of peak throughput.
- The
replica external label lets Mimir de-duplicate the two gateways' scrapes with its HA tracker, as in the UFM technote.
- Agents on nodes (if used) send to the gateway pair over OTLP; the agent configuration from the UFM technote applies unchanged.
Prometheus rules for yield and for the collector tier
These recording rules give the customer's own GPU-hour and busy-ratio figures, useful for checking Minerva's reports independently, and the alerts watch the collector tier and the Minerva intake. Validated with promtool check rules (Prometheus 3.12.0).
# rules/minerva-surround.yaml  (Prometheus or Mimir ruler)
groups:
  - name: ws-gpu-yield
    interval: 1m
    rules:
      # GPUs that report at all, and GPUs a Slurm job holds (dcgm-exporter's hpc_job label)
      - record: ws:gpus_present:count
        expr: count by (cluster) (DCGM_FI_DEV_GPU_UTIL_RATIO)
      - record: ws:gpus_allocated:count
        expr: count by (cluster) (DCGM_FI_DEV_GPU_UTIL_RATIO{hpc_job!=""})
      # How busy allocated GPUs really are (graphics engine activity, 0 to 1)
      - record: ws:gpu_busy_allocated:ratio
        expr: avg by (cluster) (DCGM_FI_PROF_GR_ENGINE_UTIL_RATIO{hpc_job!=""})
      # GPU hours delivered to jobs per hour; sum over a day for the yield report
      - record: ws:gpu_hours_allocated:rate1h
        expr: avg_over_time(ws:gpus_allocated:count[1h])

  - name: ws-gpu-health
    rules:
      - alert: GPUXidErrorReported
        expr: changes(DCGM_FI_DEV_XID_ERROR[10m]) > 0 and DCGM_FI_DEV_XID_ERROR != 0
        labels:
          severity: ticket
        annotations:
          summary: "XID {{ $value }} on {{ $labels.Hostname }} GPU {{ $labels.gpu }}"
      - alert: GPURowRemapFailed
        expr: DCGM_FI_DEV_ROW_REMAP_FAILED > 0
        labels:
          severity: page
        annotations:
          summary: "Row remap failed on {{ $labels.Hostname }} GPU {{ $labels.gpu }}: drain and replace"
      - alert: GPUAllocatedButIdle
        expr: avg by (cluster, hpc_job) (avg_over_time(DCGM_FI_DEV_GPU_UTIL_RATIO{hpc_job!=""}[30m])) < 0.05
        for: 15m
        labels:
          severity: ticket
        annotations:
          summary: "Job {{ $labels.hpc_job }} holds GPUs that have been idle for 30 minutes"
      - alert: DCGMExporterDown
        expr: up{job="dcgm"} == 0
        for: 5m
        labels:
          severity: ticket

  - name: ws-collector-tier
    rules:
      - alert: GatewayDown
        expr: up{job="otel-gateway"} == 0
        for: 2m
        labels:
          severity: ticket
      - alert: GatewayRedundancyLost
        expr: count by (site) (up{job="otel-gateway"} == 1) < 2
        for: 5m
        labels:
          severity: page
      - alert: MinervaExportFailing
        expr: sum by (instance) (rate(otelcol_exporter_send_failed_metric_points_total{exporter="otlp/minerva"}[5m])) > 0
        for: 10m
        labels:
          severity: page
        annotations:
          summary: "{{ $labels.instance }} cannot deliver metrics to the Minerva intake"
      - alert: CollectorQueueFilling
        expr: max by (instance, exporter) (otelcol_exporter_queue_size / otelcol_exporter_queue_capacity) > 0.8
        for: 10m
        labels:
          severity: ticket
      - alert: CollectorRefusingData
        expr: sum by (instance) (rate(otelcol_receiver_refused_metric_points_total[5m])) > 0
        for: 5m
        labels:
          severity: ticket
        annotations:
          summary: "{{ $labels.instance }} is refusing data, usually memory_limiter back-pressure"
      - alert: Watchdog
        expr: vector(1)
        labels:
          severity: none
        annotations:
          summary: "Dead man's switch: an external check pages if this stops arriving"
Alertmanager to Slack and PagerDuty
For the alerts the customer's Prometheus still raises (mainly the monitoring of the monitoring), Alertmanager pages through PagerDuty and posts to Slack, with the dead man's switch going to an external heartbeat service. Validated with amtool check-config (Alertmanager 0.34.2).
# alertmanager.yml  (for the alerts your own Prometheus still raises)
global:
  resolve_timeout: 5m

route:
  receiver: slack-ops
  group_by: [alertname, cluster, site]
  group_wait: 30s
  group_interval: 5m
  repeat_interval: 4h
  routes:
    - matchers: ['severity="none"']
      receiver: deadmans-switch
      repeat_interval: 1m
    - matchers: ['severity="page"']
      receiver: pagerduty-oncall
      continue: true
    - matchers: ['severity=~"page|ticket"']
      receiver: slack-ops

inhibit_rules:
  # one gateway down is noise while redundancy-lost is already paging
  - source_matchers: ['alertname="GatewayRedundancyLost"']
    target_matchers: ['alertname="GatewayDown"']
    equal: [site]

receivers:
  - name: slack-ops
    slack_configs:
      - api_url_file: /etc/alertmanager/secrets/slack-webhook
        channel: "#ai-factory-ops"
        send_resolved: true
        title: '{{ .CommonLabels.alertname }} ({{ .CommonLabels.cluster }})'
        text: '{{ range .Alerts }}{{ .Annotations.summary }}{{ "\n" }}{{ end }}'
  - name: pagerduty-oncall
    pagerduty_configs:
      - routing_key_file: /etc/alertmanager/secrets/pagerduty-routing-key
        severity: critical
  - name: deadmans-switch
    webhook_configs:
      - url_file: /etc/alertmanager/secrets/heartbeat-url
Grafana and the Elastic stack
- Grafana. NVIDIA lists Grafana integration. In the DIY and AIOps models the customer's Grafana keeps its dashboards; we add the views in the companion gallery and, where Minerva exposes them per NVIDIA's documentation, panels or links for Minerva incidents next to the raw signals.
- Elastic. Logs go to one primary store. If the customer's log store is Elasticsearch, the gateway writes ECS-shaped documents there and forwards the same logs to Minerva; we do not run a second log store just for AI hardware.
- ServiceNow and PagerDuty. NVIDIA lists both as integrations. We map Minerva priority to ServiceNow impact and urgency, set assignment groups per layer (compute, fabric, platform, facility), and confirm the de-duplication key behaviour in section 5.
10. On premises or SaaS, and UK GDPR
NVIDIA offers Minerva on premises or as SaaS from its cloud and highlights data sovereignty. Telemetry looks technical, but parts of it are personal data under UK GDPR: Slurm and Run:ai user names, job names that contain people's names, email addresses in scheduler accounting, and the questions engineers type into Sherlock. Our checklist:
- Decide the role split. On premises, the customer is controller and its staff and we process under its instructions. For SaaS, NVIDIA's role and terms for the hosted service must be reviewed by the customer's data protection officer.
- Do a DPIA where telemetry ties activity to identifiable researchers or staff, especially if it is used for performance management or chargeback.
- Minimise and pseudonymise at the edge. Hash user names at the gateway (as in the configuration above), drop free-text fields that are not needed, and keep the mapping table on site.
- International transfers. If a SaaS region is outside the UK, confirm the transfer mechanism (UK adequacy regulations, or the International Data Transfer Agreement or Addendum) before any data flows.
- Retention. Set retention per signal type: high-resolution telemetry for weeks, incidents and aggregates for longer, agent conversation logs per the customer's audit policy.
- Access. Single sign-on with role-based access; tenants in a neocloud see only their own jobs and incidents.
For UK public sector, defence-adjacent research and regulated financial services customers, we default to on premises; this is the configuration we describe in the rollout plan.
11. HA and sizing for the collector tier
Minerva's own HA and sizing are specified by NVIDIA. What we own is the collection tier around it, and it must not become the weak link.
- At least two gateways per site, in different racks on different power feeds, behind one DNS name or load balancer. Agents and switches retry to whichever is alive.
- Disk-backed queues on every exporter, on local NVMe, sized for at least an hour of peak throughput.
memory_limiter first in every pipeline, so overload causes back-pressure and a CollectorRefusingData alert instead of an out-of-memory crash.- Separate failure domains for monitoring and monitored. Gateways run on management nodes, not on GPU nodes they monitor.
- Independent watcher. A small Prometheus outside the main stack scrapes gateway health and the Minerva intake, and the Watchdog alert proves the alert path end to end.
A sizing estimate for the roughly 1,000-GPU example in the blog (fourteen NVL72 racks, illustrative):
| Source | Assumption | Active series (approx.) |
|---|
| GPU metrics via dcgm-exporter | 1,008 GPUs × ~40 fields | 40,000 |
| NVLink recovery counters (per GPU, all links; Blackwell and newer) | 1,008 GPUs × 3 counters | 3,000 |
| Ethernet switch ports | ~2,000 ports × ~25 counters | 50,000 |
| Hosts | 252 compute trays × ~60 series after filtering | 15,000 |
| Workloads and scheduler | job, service and queue metrics | 10,000 to 30,000 |
| Total for the customer's own store | | ~120,000 to 140,000 |
At a 15 to 30 second interval that is roughly 4,000 to 9,500 samples a second, comfortably within a single pair of modest gateways (we start at 8 vCPU and 16 GB each and load-test before go-live). The figures exclude what Minerva collects directly, which NVIDIA sizes. Switch-port series dominate as fabrics grow, so keep-lists on switch counters are the most effective cost control, exactly as for UFM.
12. Deployment runbook: a phased rollout
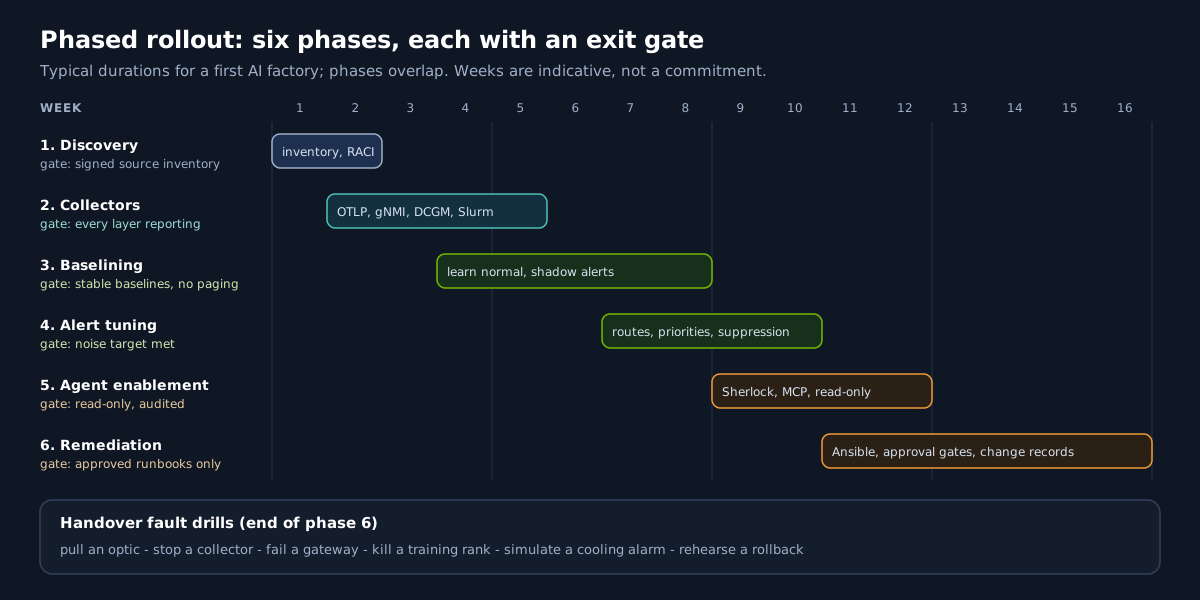
Phase 1: Discovery (weeks 1 to 2)
- Inventory every source by layer (section 3), with owners, versions and management addresses.
- Agree the consumption model, hosting model and data protection position.
- Collect the cabling plan and validate it against LLDP and switch state.
- Agree a RACI: who owns Minerva, the collectors, each integration and each playbook.
- Exit gate: signed source inventory and design.
Phase 2: Collectors and integrations (weeks 2 to 5)
- Install the Minerva Collector per NVIDIA's documentation; enable sources layer by layer.
- Deploy the OpenTelemetry gateway pair if needed; validate configuration in CI with
otelcol-contrib validate.
- Connect Slurm or Run:ai metadata; confirm job-to-GPU mapping on a test job.
- Connect Slack or Teams, ServiceNow and PagerDuty in a test mode that does not page.
- Exit gate: every layer reporting, and topology in Minerva matches the validated cabling plan.
Phase 3: Baselining (weeks 4 to 8)
- Run representative workloads: large training jobs, inference at peak, checkpoint storms.
- Minerva learns baselines; its incidents go to a review channel only.
- Existing alerting stays as it is, so nothing is lost.
- Exit gate: baselines stable for two weeks, and reviewed incidents mostly judged correct.
Phase 4: Alert tuning and noise reduction (weeks 7 to 10)
- Set priorities, routing and assignment groups; turn on paging for priority 1 and 2.
- Downgrade or inhibit overlapping legacy alerts (section 5).
- Track raw alerts per incident and pages per week as KPIs.
- Exit gate: the agreed noise target, for example fewer than 20 pages a week with no missed priority 1 incident in drills.
Phase 5: Agent enablement (weeks 9 to 12)
- Enable Sherlock for the operations team, read-only.
- Register customer agents with the MCP server under their own identities and read-only scopes.
- Turn on audit logging and review samples weekly.
- Exit gate: security review signed off; no agent holds change rights.
Phase 6: Remediation automation (weeks 11 to 16)
- Build the playbook library with rollback, owners and dry-run tests.
- Wire approval steps to ServiceNow standard changes; start at level 2 ("approve to run").
- Promote individual playbooks to pre-approved standard changes only after a clean record.
- Exit gate: only approved runbooks are callable, and every run is attached to a change record.
13. Handover fault drills
We do not hand over an incident flow we have not seen work. With the customer watching, we run and record:
- Pull an optic on a leaf-to-spine link during a test job: one incident, correct root cause, correct blast radius, one page, ServiceNow ticket opened and later resolved automatically.
- Kill one training rank or throttle one GPU so a job straggles: the straggler is named, and the job's owner is identified.
- Stop one gateway: no data loss, a
GatewayRedundancyLost page, recovery when it returns.
- Block the Minerva intake from the gateways for 15 minutes:
MinervaExportFailing pages, queues fill and drain afterwards with no gap.
- Simulate a cooling alarm through the facility integration in a test window: the incident shows affected racks and jobs.
- Approve and run a drain playbook against a lab node, then run its rollback; both appear on the change record.
- Ask Sherlock to make a change: it can describe the action but cannot perform it.
14. How Workstation delivers and runs this
Workstation is an NVIDIA partner, so alongside the hardware we provide engineering, software and staff to set up and run AI data centres end to end: design, installation, fabric bring-up, Minerva and observability set-up, and the engineers who operate it with you afterwards.
- Supply: Minerva licences, Vera Rubin NVL72 and other GPU systems, Spectrum-X Ethernet, SuperNICs and DPUs, specified together.
- Build: collectors, the OpenTelemetry tier, integrations with your tools, scheduler metadata, the playbook library and the approval workflow, all from versioned configuration.
- Run: support for Minerva and the surrounding software services, noise tuning, upgrades, capacity planning for the collector tier, and a monthly report on GPU hours, goodput, MTBI, MTTR and pages per week.
See NVIDIA Minerva in our shop, or ask our AI Sales Engineer for a sizing conversation.
15. Sources and verification notes
- Minerva facts (scope, ingest standards, knowledge graph, ML, Sherlock, MCP, integrations, DSX OS, deployment and consumption models, KPIs): the official NVIDIA Minerva page, read in November 2026, and the Minerva datasheet landing page. All wording here is our own summary.
- Not verified: Minerva's technical documentation, APIs, configuration formats, metric names, internal algorithms, HA design, sizing, pricing and licensing. Wherever we write "configured per NVIDIA's Minerva documentation", consult that documentation for the release you deploy. How Minerva and UFM interoperate on InfiniBand sites is to be confirmed with NVIDIA per release.
- OpenTelemetry Collector gateway configuration: validated with
otelcol-contrib validate in otel/opentelemetry-collector-contrib:0.165.0. The Minerva endpoint is a placeholder.
- Prometheus rules: validated with
promtool check rules, Prometheus 3.12.0. Metric names follow dcgm-exporter 4.9.0 and the Collector's own internal telemetry; names beginning ws: are Workstation recording rules.
- Alertmanager configuration: validated with
amtool check-config, Alertmanager 0.34.2.
- Ansible playbook: validated with
ansible-playbook --syntax-check, ansible-core 2.21. The scontrol, squeue and dcgmi diag invocations are standard Slurm and DCGM commands; test in a lab before production.
- Illustrative figures (alert counts, GPU-hour costs, series estimates, rollout weeks) are worked examples, not measurements from a customer system.
Acknowledgement of rights: NVIDIA, the NVIDIA logo, Minerva, Sherlock (as the name of NVIDIA's assistant), DSX, DSX OS, DGX, HGX, Vera Rubin, Blackwell, Spectrum, Spectrum-X, NVLink, ConnectX, SuperNIC, BlueField, DOCA, DCGM, NCCL, Run:ai and Unified Fabric Manager (UFM) are trademarks and/or registered trademarks of NVIDIA Corporation in the United States and other countries. NVIDIA products and technologies may be covered by patents and other intellectual property rights owned by NVIDIA Corporation, and all such rights are acknowledged and reserved to their owners. Product information is summarised in our own words from NVIDIA's public material; NVIDIA's website and documentation are the authoritative source. Other company and product names, including Grafana, Prometheus, Grafana Mimir, Elasticsearch, Slack, Microsoft Teams, PagerDuty, ServiceNow, Ansible, Red Hat, OpenTelemetry, OpenConfig, Slurm and Kubernetes, may be trademarks of their respective owners. Workstation's own dashboards, configurations and text are © Workstation.