Le blog Workstation
LLM
Articles étiquetés LLM.
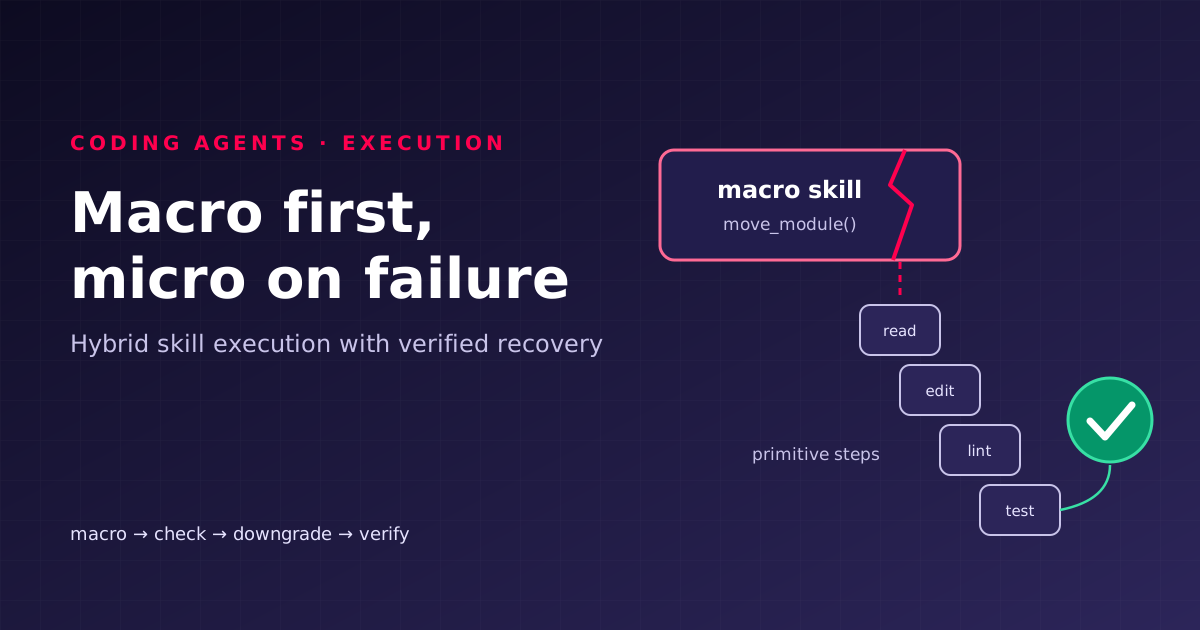
Hybrid Execution for Coding Agents: Macro Skills, Micro Recovery
Bundled macro skills make coding agents cheap but brittle; primitive tool calls make them robust but costly. Here is how to run macros first, verify every result, and fall back to small steps only when the workspace shows it is needed.
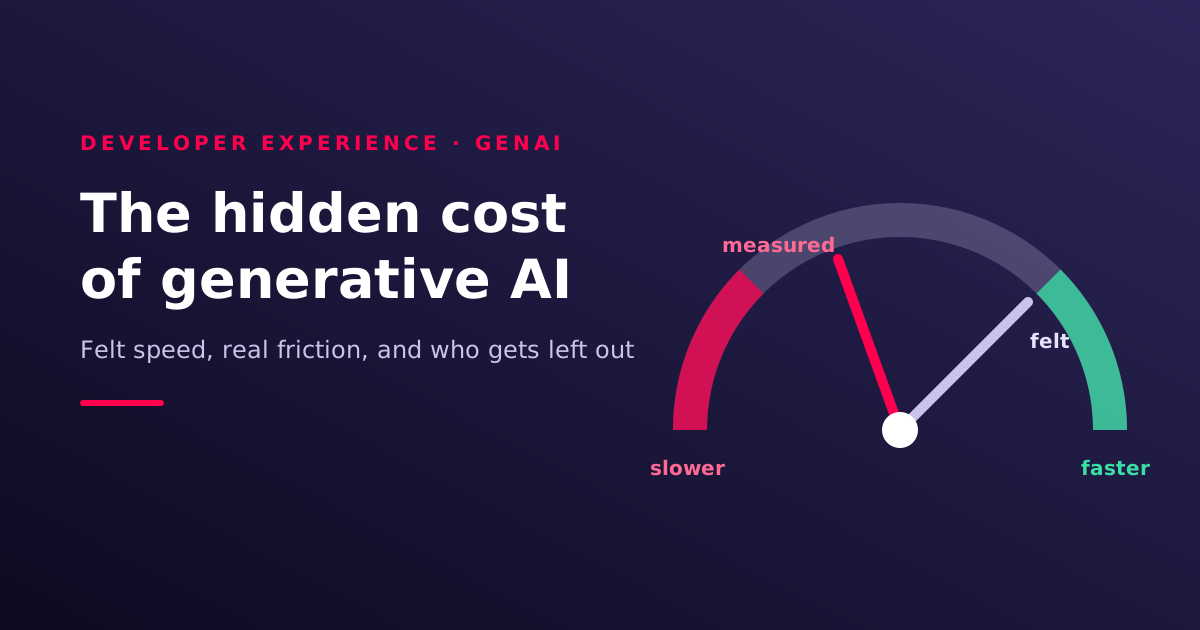
Generative AI's Hidden Impact on Developers: What Surveys Miss
Developers say AI makes them faster, but the evidence shows hidden costs: almost-right answers, a gap between felt and measured speed, tool admin work and accessibility barriers. Here is what the research says and how to measure it in your team.
Cutting LLM Inference Costs: Lessons from Cloudflare's 68% Cut
Cloudflare cut its AI code reviewer's average cost per review by 68%. Here is what that number does and does not mean, and a measured playbook for your own workload: prompt cache breakpoints, fewer agent calls, right-sized models and batch.
Agentic AI in Production: Permissions, Approval Gates, Traces and Evals
A practical playbook for running AI agents in production: classify every tool by side effect, gate mutations behind a human, set hard stop conditions, trace each step with OpenTelemetry and evaluate continuously.
MCP for DevOps: Give Agents Pipeline Context Without the Keys
How platform teams can use the Model Context Protocol safely: start with read-only servers and scoped identities behind a gateway, trace every tool call, and add write tools only behind human approval. Includes RBAC, tool and task examples.
Gemini 4 Argon: What It Means for Your Team, and Where to Use It First
Gemini 4 Argon is built to work for hours on one measurable problem. Here is what shipped, the real costs, and how to pilot it safely on your own backlog.
 Balinder WaliaLire
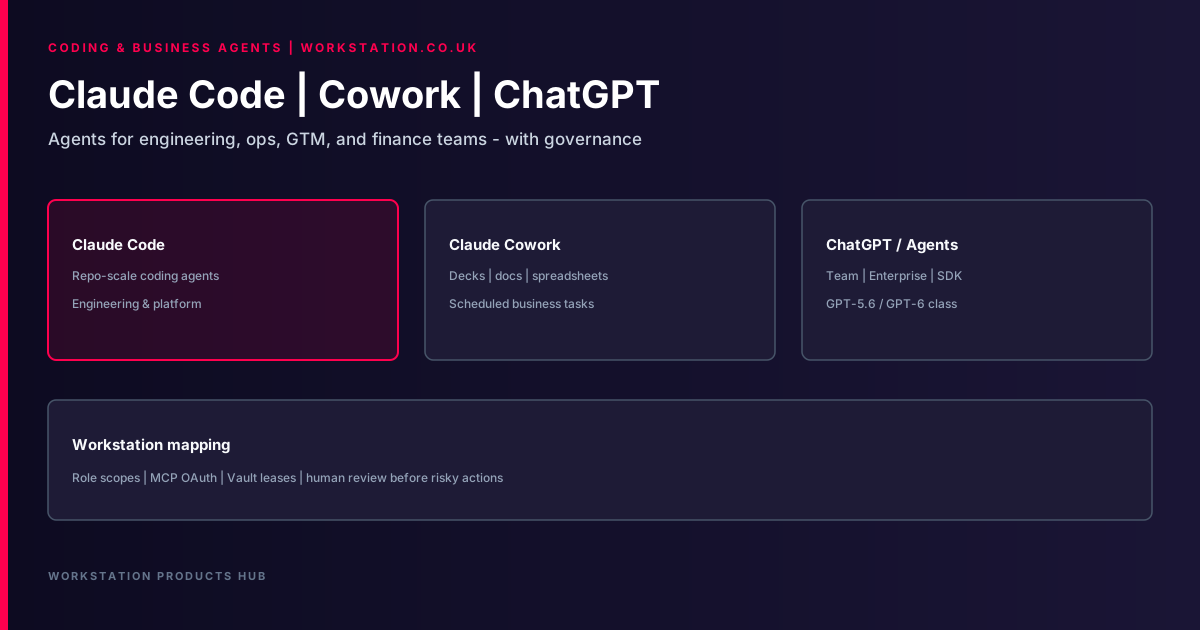
Claude Code, Claude Cowork & ChatGPT for Business Teams
Which teams should use Claude Code, Claude Cowork, or ChatGPT/OpenAI Agents — and the controls Workstation recommends before production.
Balinder WaliaLire 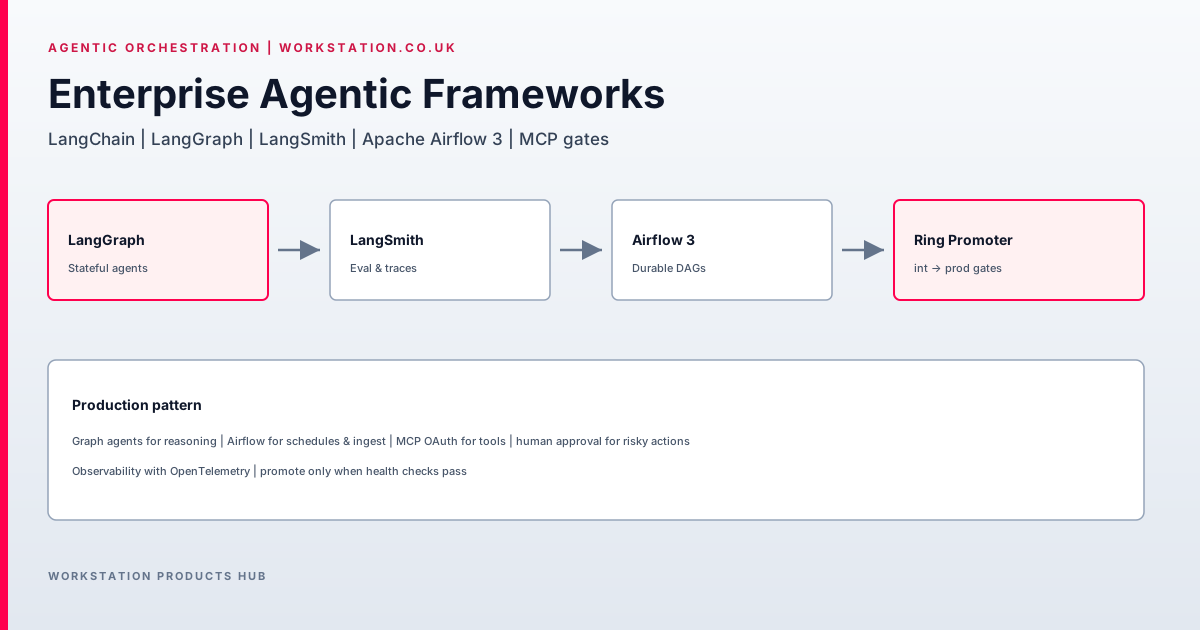
Enterprise Agentic Frameworks: LangChain, LangGraph & Airflow 3
Operational guide to LangGraph agents, LangSmith evals, and Apache Airflow 3 schedules — with Workstation promotion and edge patterns.
Balinder WaliaLire