NVIDIA RTX PRO 6000 Blackwell Server Edition: One GPU for AI, Graphics and Simulation in a UK Server Room
What the RTX PRO 6000 Server Edition is, who it suits, the 2U, 4U and 32-GPU rack builds, how it compares with the L40S, and how Workstation delivers it
 Balinder WaliaNovember 10, 20266 min read
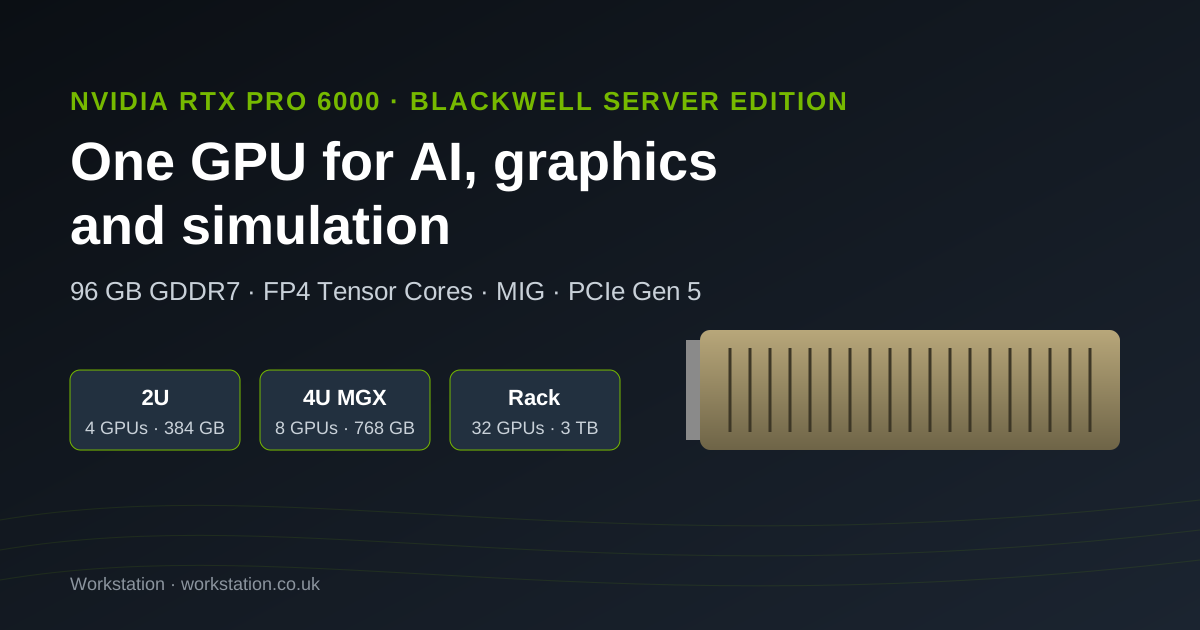
Most companies that want private AI don't need a supercomputer. They need a few servers that run their models, their designers' 3D work and their simulations, in a rack they already have, at a power draw their building can supply. NVIDIA's RTX PRO 6000 Blackwell Server Edition is built for that job. This post explains what it is, who it suits, the three sizes of system people buy, and what to check before you order.

What it is, in plain terms
NVIDIA sells two kinds of data-centre GPU. The first is the HGX family (B200, B300 and their successors), eight GPUs joined by NVLink on one board, built for training the largest models. The second is a PCIe card that slots into an ordinary server. The RTX PRO 6000 Blackwell Server Edition is the newest and most capable of the second kind, and it takes over from the L40S.
- 96 GB of GDDR7 memory per GPU, with error correction. Memory decides how large a model you can run and how many people can use it at once. 96 GB is double the L40S.
- Fifth-generation Tensor Cores with FP4. FP4 is a 4-bit number format that roughly halves the memory and doubles the speed of a model compared with FP8, for models that keep their accuracy at that precision. NVIDIA quotes up to 4 PFLOPS of FP4 per card.
- Graphics hardware too. 188 RT Cores for ray tracing, four video encoders, four decoders and four DisplayPort 2.1 outputs. The same card that serves a chatbot can render a product visualisation or run an Omniverse digital twin.
- One GPU or four. Multi-Instance GPU (MIG) splits a card into up to four isolated GPUs, each with its own memory and compute, so small jobs and separate teams don't waste a whole card.
- Air or liquid cooled. The air-cooled card is a passive, dual-slot, full-length card that relies on the server's fans. A single-slot liquid-cooled version suits denser builds.
Why it matters for a UK business
Three things make it a practical choice for companies outside the hyperscalers.
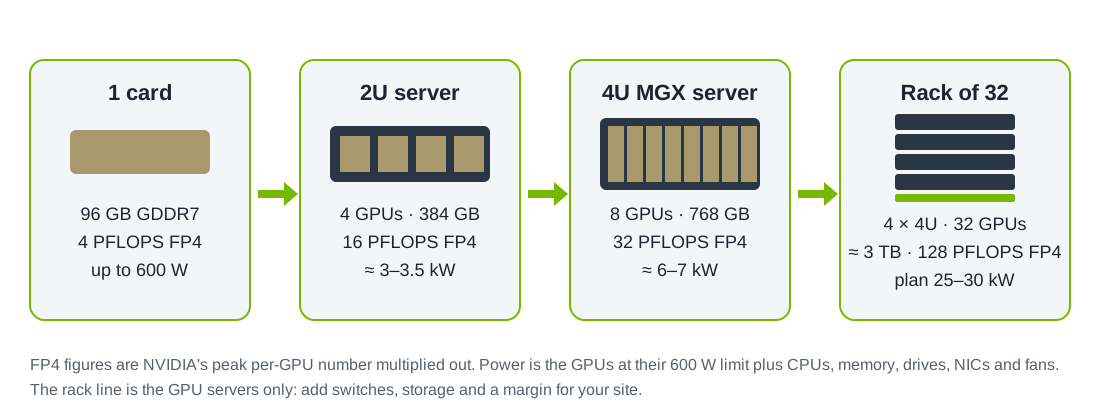
It fits the room you have. A four-GPU server is 2U and draws roughly 3 to 3.5 kW at full GPU power. That's within reach of many existing server rooms and colocation racks, unlike an eight-GPU HGX system that often needs 10 kW or more for a single server and sometimes liquid cooling.
It serves more than one team. Many companies buy AI hardware for one project and watch it sit idle. Because the RTX PRO 6000 is as good at graphics as at AI, the same servers can run inference for customer service by day and rendering, simulation or fine-tuning overnight.
Your data stays on your premises. Running models on your own hardware keeps prompts, documents and outputs inside your building, which makes UK GDPR, client confidentiality and sector rules simpler to meet. Once the hardware is paid for, heavy daily use costs only power, with no per-token bill.
Three sizes, from a department to a data hall
| System | GPU memory | Typical use | Power to plan for |
|---|---|---|---|
| 2U, four GPUs | 384 GB | A department's private assistant, document search with RAG, a first production inference service | About 3 to 3.5 kW |
| 4U, eight GPUs (NVIDIA MGX) | 768 GB | Several models at once, larger models, many concurrent users, a shared render node | About 6 to 7 kW |
| A rack of 32 GPUs | About 3 TB | Company-wide inference, multi-agent systems, rendering farms, synthetic data generation | 25 to 30 kW per rack |
The rack-scale option is worth a closer look. AMAX, a US system builder, sells a design called the RackScale 32: 32 RTX PRO 6000 Server Edition GPUs on dual AMD EPYC 9005 processors in NVIDIA MGX servers, with NVIDIA Spectrum-X Ethernet or Quantum InfiniBand between them. That gives about 3 TB of GPU memory and, by NVIDIA's peak figures, 128 PFLOPS of FP4 in one rack. AMAX positions it as a building block for an "AI factory" that grows a rack at a time. The building block inside is an eight-GPU 4U MGX server, such as AMAX's AceleMax AXG-428AG, with room for five 400 Gb/s network cards and eight E1.S drives.
You don't have to start at a rack. Most of our customers begin with one 2U or 4U server, prove the workload, then add servers with the same configuration. A consistent build makes that growth simple.
RTX PRO 6000 or L40S?
If you already run L40S servers, the RTX PRO 6000 Server Edition is the natural upgrade. It has twice the memory, nearly twice the bandwidth (1,597 GB/s against 864 GB/s), FP4, MIG and PCIe Gen 5. A model that needed two L40S cards often fits on one RTX PRO 6000, which saves slots, power and licences. The L40S still makes sense where power is tight (350 W against up to 600 W) or where your models comfortably fit in 48 GB.
What it doesn't do
- No NVLink. The cards talk over PCIe. That's fine for running many copies of a model, or one model split over a few GPUs. Large training runs that need GPUs to share data constantly belong on HGX systems.
- Peak figures are peaks. NVIDIA's FP4 and FP8 numbers are maximums. Your throughput depends on the model, the precision, the context length and the software, so we benchmark your workload before we size the order.
- 600 W is a lot of heat. Eight cards at full power are nearly 5 kW of GPU alone. The power limit can be lowered, which trades a little speed for more GPUs per rack.
How Workstation delivers it
- Size it. We work out GPU memory, users and storage from your models, context lengths and expected traffic, and pick the smallest system that does the job.
- Check the site. Power per rack, cooling, floor loading, network uplinks and access routes, before we quote anything.
- Quote it. A written quote with the exact configuration, the lead time and the power and cooling it needs. Prices for these systems change with GPU supply, so we confirm them in writing rather than guess.
- Build and test it. Operating system, NVIDIA data-centre drivers, CUDA, the container toolkit and your inference or rendering stack, then a burn-in at full load.
- Install and support it. We rack, cable and hand over the system and support it from the UK, with the manufacturer's warranty behind the hardware.
For the full detail, from memory sizing formulas and MIG to PCIe topology, networking and a deployment checklist, read our technical guide to the RTX PRO 6000 Blackwell Server Edition. The RTX PRO 6000 page has the full specification and the systems we supply.
Sources
- NVIDIA: RTX PRO 6000 Blackwell Server Edition
- AMAX: RackScale 32 with NVIDIA RTX PRO 6000 Blackwell Server Edition
- AMAX: RTX PRO 6000 Blackwell Server Edition vs L40S
Trademarks. NVIDIA, the NVIDIA logo, RTX, RTX PRO, Blackwell, CUDA, NVLink, MGX, Omniverse, Spectrum-X and Quantum are trademarks and/or registered trademarks of NVIDIA Corporation in the US and other countries. AMAX and AceleMax are trademarks of AMAX Engineering Corporation. AMD and EPYC are trademarks of Advanced Micro Devices, Inc. All other trademarks belong to their respective owners. Workstation is an independent supplier; no endorsement by these companies is implied. The video is NVIDIA's.