Shop is live

We build Workstation AI machines for websites, AI agents, and LLM training — configure and buy online.

Enter the shop
AI Products
AI LabsOpenAI AgentsClaude AgentsGrok BotWorkstation AI native CRMMarketingAll Products
AI Solutions
Applied AIAI AgentsGenerative AIAI AutomationAI UpskillingAI SME PackagesEnterprise AI LabAI WorkstationsNVIDIA Hardware & SoftwareNVIDIA Accelerated ComputingPrivate AIGPU ClustersEdge AIAI by Industry
AI Services
Platform ModernisationDigital EngineeringData Foundations & AIAutonomous OperationsAI ConsultancyDevOps AutomationCyber SecuritySoftware DevelopmentAgent BuildingMLOps Setup
About Us
CompanyOur StoryPartnersCustomer Stories
AI Data Centres
AI InsightsJev seriesBenchmark LabModel selection
Articles
Documentation
Linux OSUbuntuRed Hat Enterprise LinuxSUSE LinuxAlpine LinuxDebian, Rocky & AlmaLinux
AI Cloud PlatformsAWS & Amazon BedrockGoogle Cloud & Vertex AIMicrosoft Azure & AI FoundryGPU clouds & marketplaces
Private AI Data CentresFor law firmsFor accounting firmsOn-premises platformsFully secured cloud
ToolsRing PromoterJobshout
News
Blog
Contact UsSign in

AI workstations, AI Multi Agentic Software, GPU infrastructure, and intelligent agent solutions for modern businesses.

Contact Us

AI Solutions

Applied AIAI AgentsGenerative AIAI AutomationAI UpskillingAI SME PackagesEnterprise AI LabAI by Industry

Products

All ProductsWorkstation AI native CRM & ERPMarketingOpenAI AgentsRing PromoterJobshout

Company

About UsCompanyAI Data CentresWhy WorkstationPartnersCustomer StoriesPricingContactTenthMatrix

Resources

AI InsightsArticlesDocumentationLinux OSAI Cloud PlatformsPrivate AI Data CentresBlogSearchSitemap
UK Office
77-79 Marlowes, Hemel Hempstead HP1 1LFDirections - Take Junction 20 off M25 Outer LondonCompany No: 11641870Mon - Fri: 9:00 AM - 6:00 PM GMT
+44 7515 356 146
Belgium Office
Workstation SRL, Rue Vanderkindere 34, 1180 Uccle, BrusselsBE 0751.518.683Mon - Fri: 9:00 AM - 6:00 PM CET
+32 492 45 67 46
India Office
#159 Sector 9, Pocket 1, DDA Flats, 110077 Dwarka, New Delhi
+91 98881 98841

© 2026 Workstation AI. All rights reserved.

PrivacyData DeletionCookiesTerms of ServiceWebsite Sitemap

NVIDIA Partner · UK

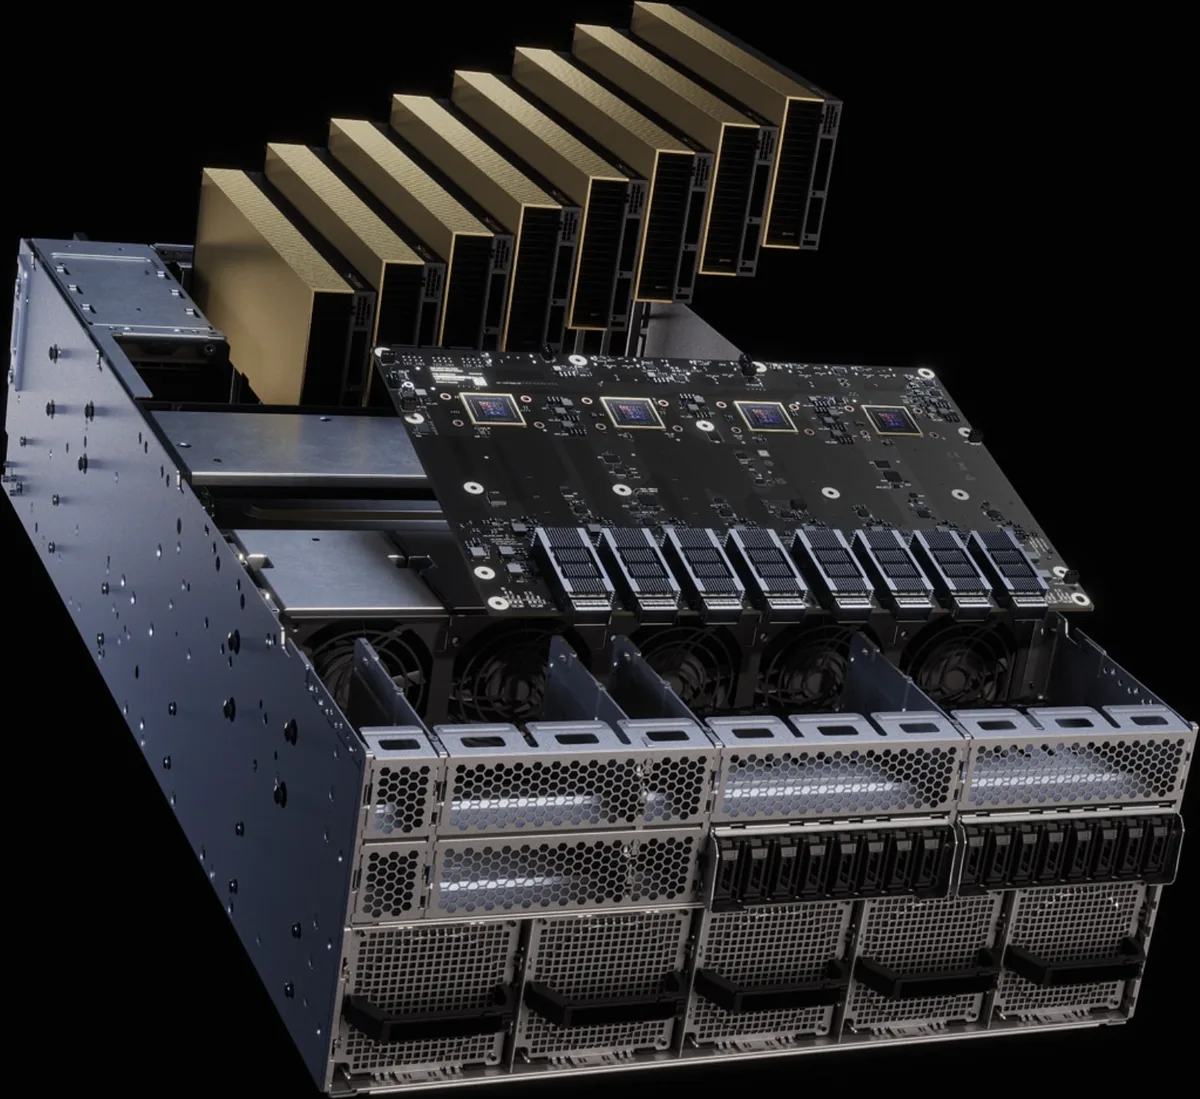
NVIDIA Accelerated Computing solutions

From a single data-centre GPU to a liquid-cooled rack-scale AI factory, Workstation sizes, supplies, builds, installs and supports the full NVIDIA accelerated computing range for UK organisations.

Browse the rangeTalk to an engineer
  • 34NVIDIA systems, GPUs, networking and software products
  • 5steps, from sizing to long-term support
  • UKengineering, build and burn-in testing

Accelerated computing, without the integration risk

Accelerated computing moves the heaviest parts of a workload, such as AI training, inference, simulation, analytics and rendering, from general-purpose CPUs onto GPUs and specialised processors. The result is more work done per rack and per watt, and results in hours rather than days.

Getting there takes more than a GPU. Each accelerator needs a server that can power and cool it, a network that keeps it fed, and software that is licensed and supported. As an NVIDIA Partner with our own engineers, we bring those pieces together into one tested system and stay with you after it goes live.

  • Independent advice on which NVIDIA platform fits your workloads
  • Complete, NVIDIA-Certified configurations rather than loose parts
  • Built, imaged and burn-in tested in our UK workshop
  • Installed, cabled and commissioned on your site
  • One UK contact for support, upgrades and warranty

What goes into an accelerated system

Four layers work together. We specify all four so none of them becomes the bottleneck.

GPUs

Do the parallel maths behind AI, simulation and graphics. Memory size and bandwidth usually decide which GPU you need.

CPUs and systems

Feed the GPUs, run the operating system and hold data in memory. The chassis decides power, cooling and how many GPUs fit.

Networking and DPUs

Move data between GPUs, servers and storage. DPUs take networking, storage and security work off the CPU.

Software

Drivers, CUDA, AI frameworks and cluster tools turn hardware into a platform your teams can use.

Why organisations move to accelerated computing

Workloads outgrow CPUs

AI models and data sets grow faster than CPU performance. Jobs overrun, service levels slip and power bills rise.

Workflows get complicated

Data preparation, training, inference and visualisation often run on separate kit. One accelerated platform simplifies the pipeline.

New apps create new silos

Adding AI beside existing applications can create islands of hardware. A shared, certified platform keeps everything manageable.

The range

NVIDIA accelerated computing products

Every system, GPU, network product and software licence below can be supplied on its own or as part of a complete build. Filter by type, compare the key specifications and request a quote.

Systems and platforms

NVIDIA Vera Rubin NVL72

Rack-scale system for agentic AI and the largest models

NVIDIA's newest rack-scale generation joins 72 Rubin GPUs and 36 Vera CPUs in one NVLink domain, so a single rack behaves like one very large accelerator.

Who it suits: AI factories, model builders and service providers planning their next large deployment

Benefits

  • Far more tokens per megawatt than the Grace Blackwell generation, by NVIDIA's figures
  • HBM4 memory sized for trillion-parameter and long-context models
  • Modular, cable-free trays that make servicing in the rack simpler

Key specifications

Configuration72× Rubin GPU, 36× Vera CPU
GPU memory20.7 TB HBM4 | 1,400 TB/s
NVFP4 inference3,600 PFLOPS (sparse)
NVLink bandwidth216 TB/s (sixth generation)
CPU memoryUp to 54 TB LPDDR5X
Form factorRack, third-generation MGX NVL72

What Workstation does: We check site power, cooling and floor loading early, secure allocation, and plan delivery, installation and commissioning around your data hall.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
Systems and platforms

NVIDIA GB300 NVL72 (DGX GB300)

Liquid-cooled Blackwell Ultra rack for AI reasoning

Thirty-six Grace CPUs and 72 Blackwell Ultra GPUs share one NVLink fabric in a single liquid-cooled rack. NVIDIA also supplies it as the DGX GB300.

Who it suits: Organisations serving reasoning models to many users, and teams training at frontier scale

Benefits

  • A large step up in tokens per second per user over Hopper-based systems
  • 37 TB of fast memory keeps long contexts and large models in one domain
  • ConnectX-8 SuperNICs give every GPU an 800 Gb/s path to the network

Key specifications

GPUs72× Blackwell Ultra
CPUs36× Grace (2,592 Arm Neoverse V2 cores)
GPU memory20 TB | up to 576 TB/s
Fast memory37 TB
FP4 Tensor Core1,440 PFLOPS (sparse)
NVLink bandwidth130 TB/s

What Workstation does: We plan liquid cooling and power with your facilities team, coordinate delivery of the integrated rack and commission it to a validated baseline.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
Systems and platforms

NVIDIA GB200 NVL72 (DGX GB200)

Grace Blackwell rack-scale system in one NVLink domain

The first Grace Blackwell rack: 72 Blackwell GPUs and 36 Grace CPUs linked by NVLink and cooled by liquid, for very large training runs and real-time inference.

Who it suits: Teams training or serving trillion-parameter models who need one large, shared GPU memory pool

Benefits

  • Real-time inference on very large language models, many times faster than H100 by NVIDIA's figures
  • Liquid cooling raises density and energy efficiency
  • Fifth-generation NVLink gives 1.8 TB/s between any two GPUs

Key specifications

Configuration72× Blackwell GPU, 36× Grace CPU
GPU memory13.4 TB HBM3E | 576 TB/s
NVFP4 Tensor Core1,440 PFLOPS sparse | 720 PFLOPS dense
NVLink bandwidth130 TB/s
CPU memory17 TB LPDDR5X | 14 TB/s
CoolingLiquid cooled

What Workstation does: We assess your site for liquid cooling, manage delivery and integration with your network and storage, and support the rack after go-live.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
Systems and platforms

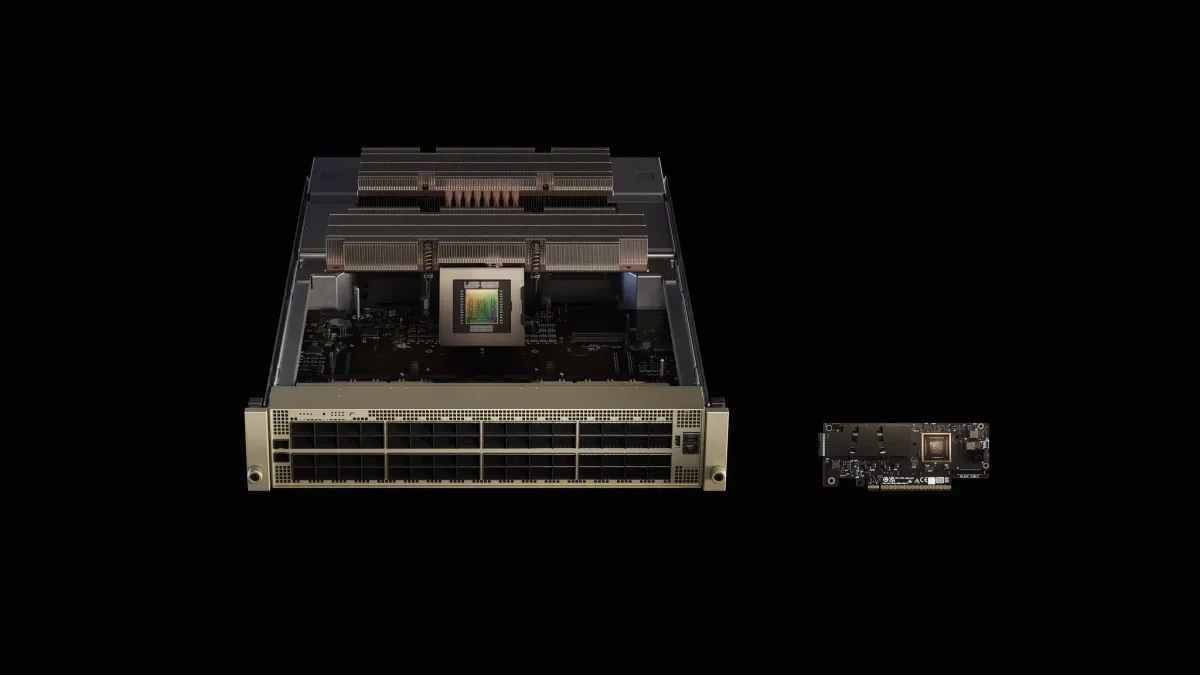
NVIDIA DGX B300

Eight Blackwell Ultra GPUs in one DGX system

A self-contained DGX server with eight Blackwell Ultra GPUs, NVIDIA networking and the full DGX software stack, ready to stand alone or join a BasePOD or SuperPOD.

Who it suits: Enterprises building their first serious AI factory, and teams that want NVIDIA's reference design rather than a custom build

Benefits

  • 2.3 TB of GPU memory in a single node for large models
  • Built-in ConnectX-8 and BlueField-3 networking for scaling out
  • DGX software keeps every node in a cluster consistent from day one

Key specifications

GPUs8× Blackwell Ultra
GPU memory2.3 TB total
AI performance72 PFLOPS FP8 training, 144 PFLOPS FP4 inference
Networking8× ConnectX-8, 2× BlueField-3 DPU

What Workstation does: We check rack power and airflow, deliver and rack the system, connect it to your fabric and hand over with DGX OS and drivers validated.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
Systems and platforms

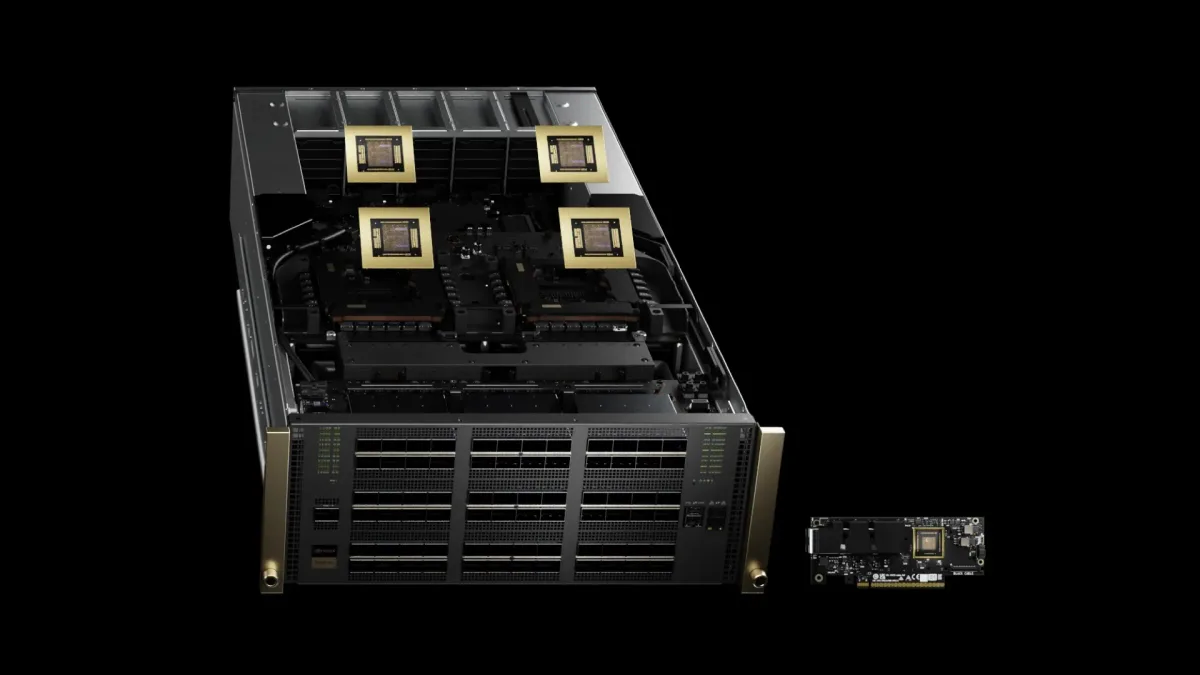
NVIDIA DGX B200

Proven Blackwell DGX for training and inference

Eight NVLink-connected Blackwell GPUs in a single DGX chassis, a widely deployed building block for on-premises AI.

Who it suits: Teams moving from Hopper or from cloud GPUs to an owned Blackwell platform

Benefits

  • One platform for training, fine-tuning and inference
  • 1,440 GB of GPU memory across eight NVLink-connected GPUs
  • Fits BasePOD and SuperPOD reference designs as you grow

Key specifications

GPUs8× Blackwell
GPU memory1,440 GB total
AI performance72 PFLOPS training, 144 PFLOPS inference
Networking8× ConnectX-7, 2× BlueField-3 DPU

What Workstation does: We size it against your models, deliver and install it, and set up drivers, CUDA and NVIDIA AI Enterprise before handover.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
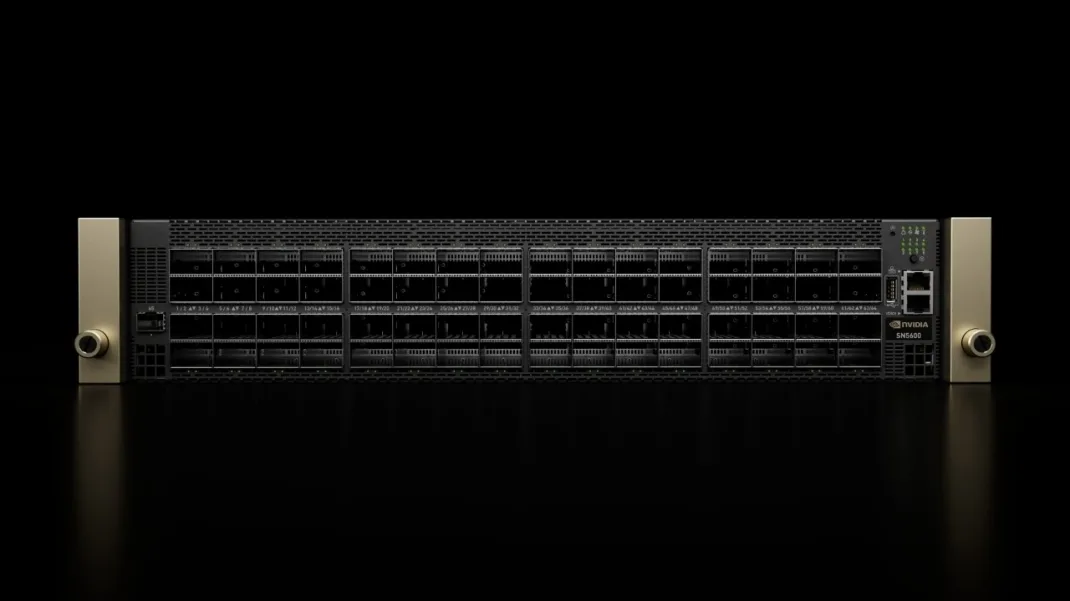
Systems and platforms

NVIDIA HGX

Eight-GPU baseboard inside partner servers

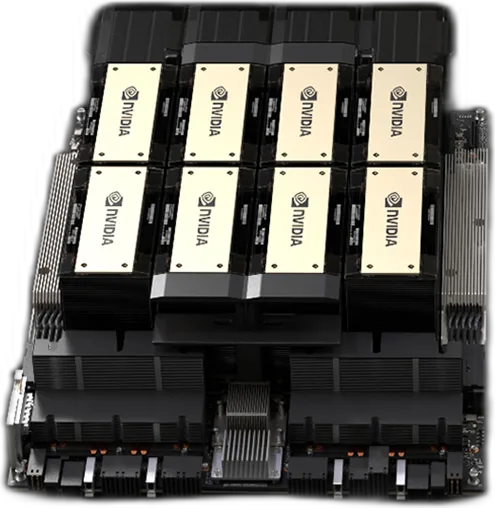
HGX is NVIDIA's NVLink-connected GPU baseboard that server makers build into their own systems, giving you top-end GPUs with your choice of chassis, CPU and support brand.

Who it suits: Organisations that want flagship GPUs from their preferred server vendor

Benefits

  • Choose the server brand, CPU and storage that suit your estate
  • NVLink and NVSwitch connect all eight GPUs at full speed
  • Covers the Blackwell, Blackwell Ultra and Rubin generations

Key specifications

HGX B3008× Blackwell Ultra SXM, 2.1 TB, 144 PFLOPS FP4 (sparse)
HGX B2008× Blackwell SXM, 1.4 TB, 144 PFLOPS FP4 (sparse)
HGX Rubin NVL88× Rubin SXM, 2 TB HBM4, 400 PFLOPS NVFP4 inference
NVLink bandwidth14.4 TB/s total (HGX B300 and B200)

What Workstation does: We source the HGX server from the brand you prefer, burn it in at full load in our workshop and install it with your networking.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
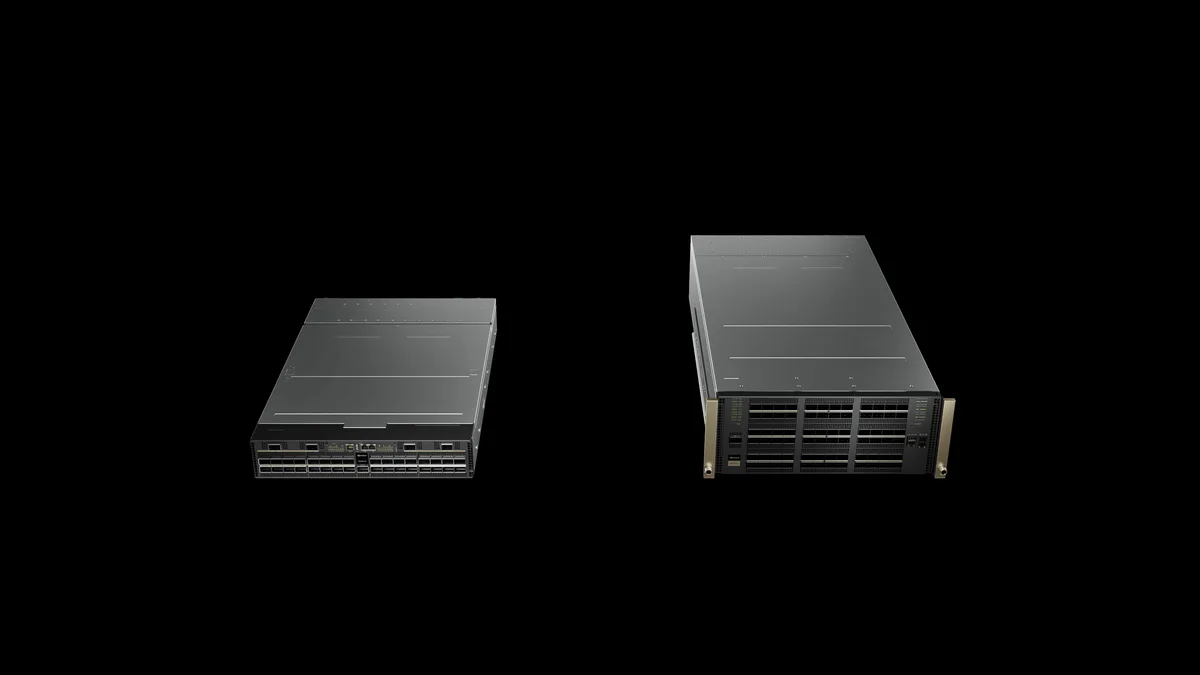
Systems and platforms

NVIDIA RTX PRO Server

Universal Blackwell server for enterprise AI and graphics

A data-centre server with up to eight RTX PRO 6000 Blackwell Server Edition GPUs that runs AI, simulation, rendering and virtual workstations on one platform. It is NVIDIA's mainstream accelerated server, and its EGX page now points here.

Who it suits: Enterprises moving existing data-centre workloads onto GPUs alongside new AI services

Benefits

  • One server type for AI inference, visual computing and data science
  • Air-cooled options suit most existing server rooms
  • Validated with NVIDIA AI Enterprise and Omniverse

Key specifications

GPUsUp to 8× RTX PRO 6000 Blackwell Server Edition
GPU memory800 GB (8-GPU configuration)
Memory bandwidth13 TB/s (8-GPU configuration)
RTX graphics3 PFLOPS
ConfigurationsMGX 2U, 4U and 6U (6U liquid cooled)

What Workstation does: We specify the chassis and GPU count against your workloads, check it is NVIDIA-Certified, then build, burn in and install it.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
Systems and platforms

NVIDIA DGX SuperPOD

Turnkey blueprint for AI factories at scale

A full-stack reference architecture that combines DGX systems, NVIDIA networking, certified storage and management software in repeatable scalable units.

Who it suits: Research labs, large enterprises and AI service providers building clusters of hundreds or thousands of GPUs

Benefits

  • A tested design removes much of the integration risk
  • Scales to tens of thousands of GPUs in repeatable units
  • Includes Mission Control and Base Command Manager for operations

Key specifications

TypeReference architecture
Building blockScalable units of DGX systems
ScaleUp to tens of thousands of GPUs
StorageNVIDIA-certified partner storage
SoftwareNVIDIA AI Enterprise, Base Command Manager, Mission Control

What Workstation does: We lead the design with NVIDIA and storage partners, run the project plan, install the scalable units and stay on as your support contact.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
Systems and platforms

NVIDIA DGX BasePOD

Reference design for your first DGX cluster

A proven design for two or more DGX systems with matching networking, storage and cluster software: smaller than a SuperPOD, but built the same way.

Who it suits: Teams growing from one DGX system to a small shared cluster

Benefits

  • Start with two systems and add more without redesigning
  • Networking and storage matched to the GPUs
  • Cluster software included for scheduling and monitoring

Key specifications

TypeReference architecture
Scale2 or more DGX systems
NetworkingPer reference architecture
StoragePartner storage
SoftwareNVIDIA AI Enterprise, Base Command

What Workstation does: We size the cluster, supply every part, rack and cable it, and set up scheduling so your teams can share it from day one.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
Systems and platforms

NVIDIA Grace and Vera CPUs

Arm data-centre CPUs built for AI factories

NVIDIA's own CPUs connect to its GPUs over NVLink-C2C. The Grace CPU Superchip ships in partner servers today, and its successor, Vera, is aimed at agentic AI.

Who it suits: HPC centres, cloud builders and anyone running CPU-heavy pipelines alongside GPUs

Benefits

  • High memory bandwidth from LPDDR5X
  • Twice the performance at the same power as leading traditional CPUs, by NVIDIA's figures
  • A coherent, high-speed link to NVIDIA GPUs

Key specifications

Grace CPU Superchip144 Arm Neoverse V2 cores, 2 CPUs over 900 GB/s NVLink-C2C
Grace memory bandwidthUp to 1 TB/s LPDDR5X
Vera CPU88 Olympus cores, up to 1.5 TB memory at up to 1.2 TB/s
Vera NVLink-C2CUp to 1.8 TB/s

What Workstation does: We find the partner server that suits your software stack, test your applications on Arm with you, then build and support the result.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
Systems and platforms

NVIDIA OVX

L40S servers for Omniverse and digital twins

OVX is NVIDIA's validated server design for Omniverse, combining L40S GPUs with ConnectX-7 or BlueField-3 networking for simulation, rendering and AI.

Who it suits: Manufacturers, architects and engineering teams building industrial digital twins

Benefits

  • One server for graphics, simulation and AI inference
  • Validated for Omniverse and NVIDIA AI Enterprise
  • Scales across hundreds of servers on a high-speed fabric

Key specifications

GPUs4× or 8× NVIDIA L40S
CPUs2× Intel Xeon Gold or 2× AMD EPYC
Host memory384 GB (4-GPU) or 768 GB (8-GPU) DDR5 ECC minimum
Storage1 TB NVMe boot, 2× 4 TB NVMe
NetworkingConnectX-7 or BlueField-3

What Workstation does: We build OVX-pattern servers from certified partners, set up Omniverse and drivers, and connect them to your design tools.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
Systems and platforms

NVIDIA AGX (Jetson AGX Thor)

AI computers for robots and autonomous machines

AGX is NVIDIA's platform for autonomous machines. Its current flagship, Jetson AGX Thor, brings a Blackwell GPU to robots, vehicles and smart machines.

Who it suits: Robotics, automotive and industrial teams putting AI into machines

Benefits

  • Runs perception and generative AI models on the machine itself
  • Low power suits mobile and embedded designs
  • Uses the same CUDA software as NVIDIA's data-centre platforms

Key specifications

GPUBlackwell, 2560 CUDA cores, 96 fifth-generation Tensor Cores
AI performance2070 TFLOPS (FP4)
OptionsDeveloper kit, or T5000 and T4000 production modules

What Workstation does: We supply developer kits and production modules, help choose carrier boards and enclosures, and support you from prototype to roll-out.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
Systems and platforms

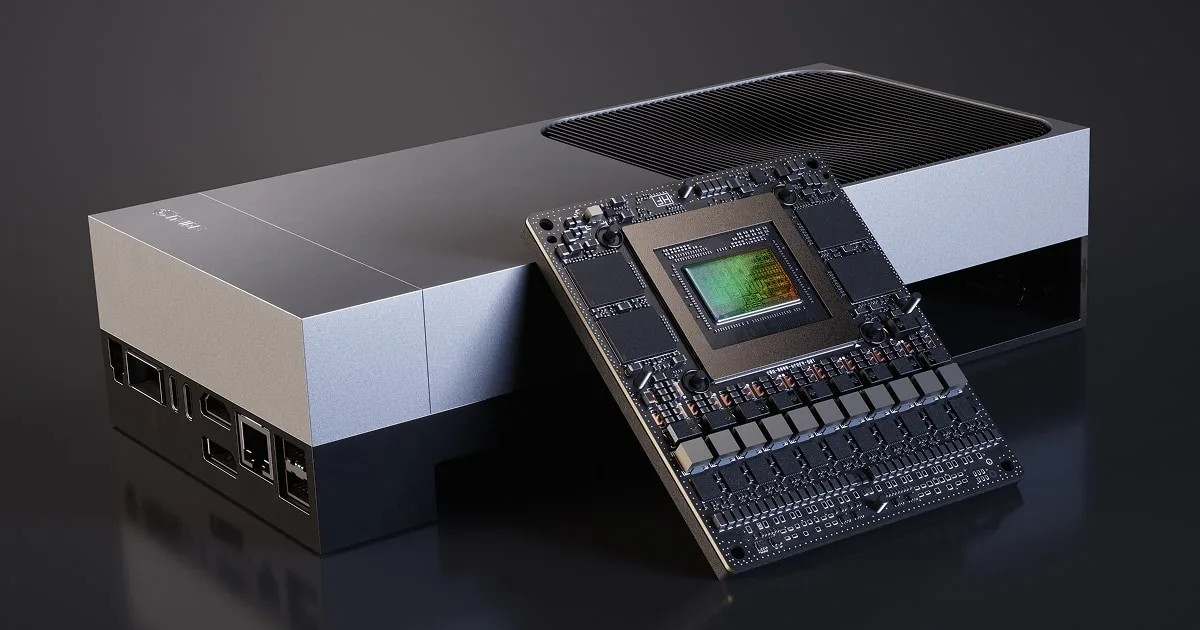
NVIDIA IGX Thor

Industrial edge AI with functional safety

IGX is NVIDIA's enterprise platform for physical AI at the industrial and medical edge, with a dedicated safety island and long-term software support.

Who it suits: Medical device makers, factories and infrastructure operators who need safety certification and a long support life

Benefits

  • Functional safety design aimed at ISO 26262 and IEC 61508
  • Ten years of NVIDIA enterprise software support
  • Optional RTX PRO Blackwell GPU for heavier models

Key specifications

AI performanceUp to 5,581 TFLOPS FP4 (sparse) with discrete GPU
Integrated GPU2,560-core Blackwell
CPU14-core Arm Neoverse-V3AE, 2.6 GHz
Memory128 GB LPDDR5X, 273 GB/s
Power40–130 W, up to 300 W for the discrete GPU

What Workstation does: We supply developer kits and production systems, help you plan certification evidence and support deployment on your site.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
Systems and platforms

NVIDIA Groq 3 LPX

Low-latency inference rack for Vera Rubin

LPX is a rack of 256 LPU inference accelerators that works alongside Vera Rubin NVL72 to generate tokens quickly and predictably for interactive and agentic AI.

Who it suits: AI service providers whose users need fast, consistent response times

Benefits

  • Deterministic, low-latency token generation
  • Much higher throughput per megawatt for trillion-parameter models, by NVIDIA's projections
  • A direct, low-latency link to NVL72 racks

Key specifications

Accelerators256 LPUs per rack
On-chip memory128 GB SRAM per rack (500 MB per LPU)
SRAM bandwidth40 PB/s per rack
Scale-up bandwidth640 TB/s per rack
Form factorNVIDIA MGX ETL rack

What Workstation does: We assess how it fits your Vera Rubin plans, confirm availability with NVIDIA and plan the installation alongside your other racks.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗
Data-centre GPUs

NVIDIA H200 (SXM)

Hopper GPU with 141 GB of HBM3e

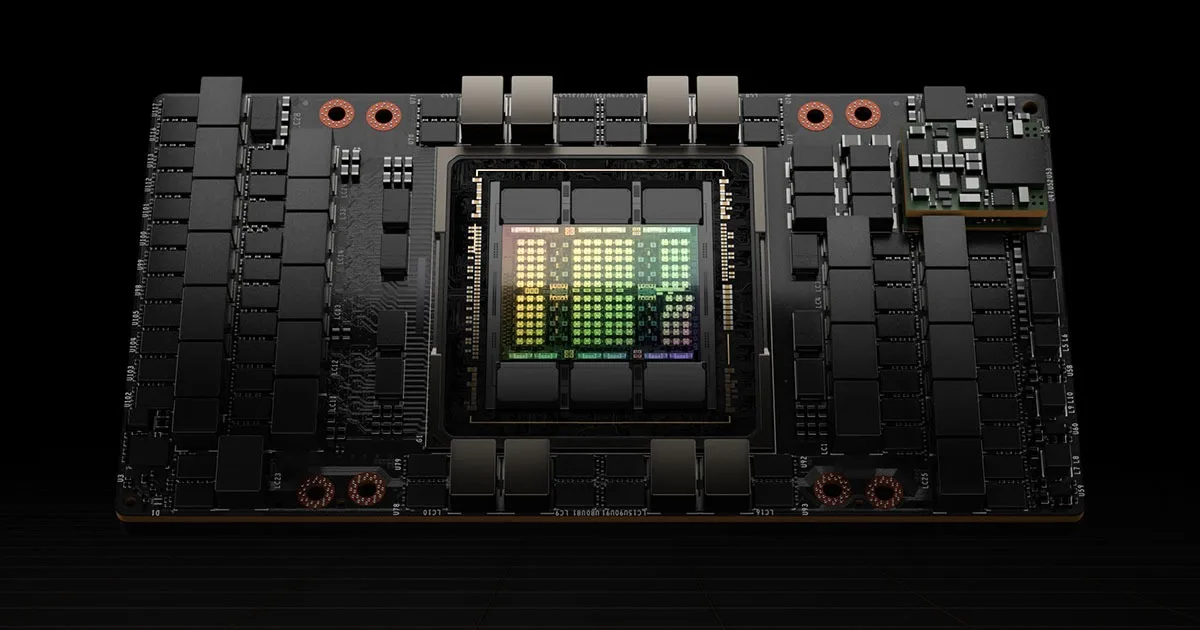
The H200 keeps the Hopper architecture but adds much more, and faster, memory, which helps large-model inference and memory-bound HPC. The SXM version goes into HGX servers.

Who it suits: Teams running large language models and HPC codes on HGX servers

Benefits

  • 141 GB per GPU fits bigger models without splitting them
  • Higher memory bandwidth speeds up memory-bound work
  • Runs the same CUDA software as H100

Key specifications

ArchitectureNVIDIA Hopper
GPU memory141 GB HBM3e
Form factorSXM (HGX)
CoolingPassive (server airflow)

What Workstation does: We supply H200 inside a certified HGX server, burn it in and install it with your drivers and software stack.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Data-centre GPUs

NVIDIA H200 NVL

141 GB Hopper GPU for air-cooled PCIe servers

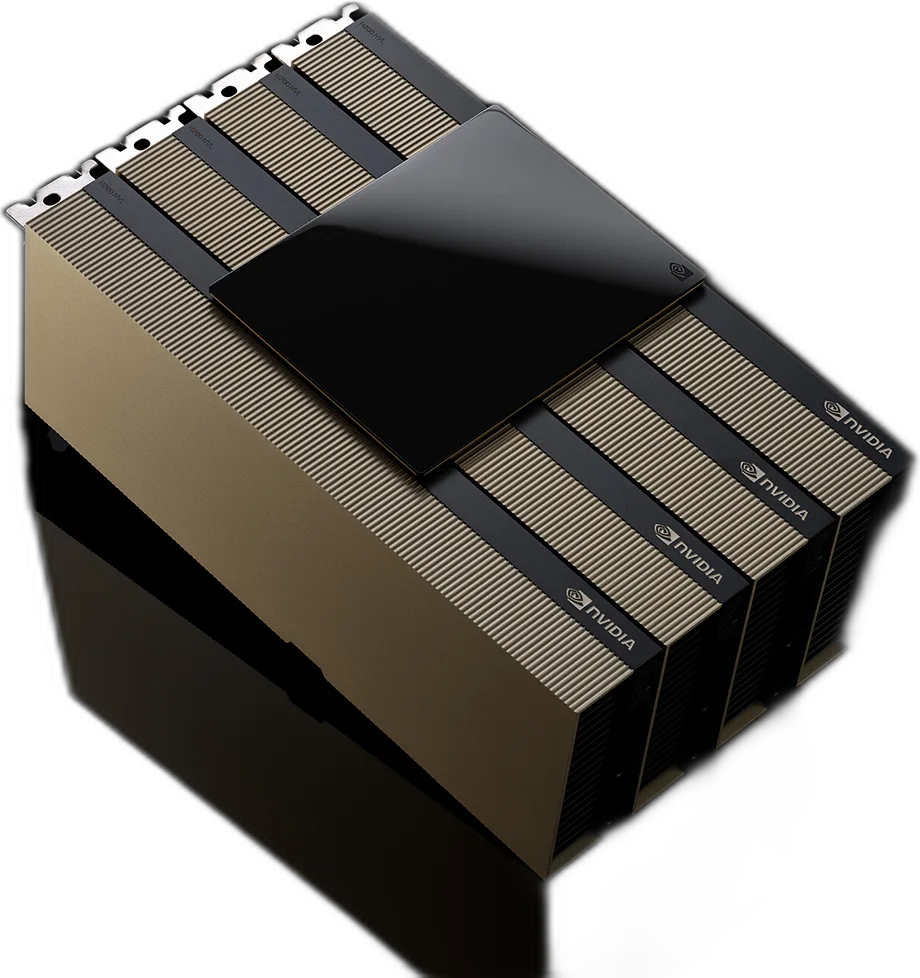
The PCIe version of the H200 for standard enterprise racks. NVLink bridges can pair cards for models that need more memory.

Who it suits: Enterprises adding large-model inference to existing air-cooled server rooms

Benefits

  • Large GPU memory without moving to liquid cooling
  • NVLink bridges join GPUs for larger models
  • Fits mainstream NVIDIA-Certified servers

Key specifications

ArchitectureNVIDIA Hopper
GPU memory141 GB HBM3e
Form factorPCIe, dual slot
CoolingPassive (server airflow)

What Workstation does: We check your chassis for power, airflow and slot layout, then fit, test and deliver the cards or a complete server.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Data-centre GPUs

NVIDIA H100 PCIe 80 GB

Hopper GPU for training and inference in PCIe servers

The PCIe H100 brings Hopper's Transformer Engine and confidential computing to standard servers.

Who it suits: Teams with existing PCIe GPU servers that need proven Hopper performance

Benefits

  • The Transformer Engine speeds up training and inference of language models
  • Multi-Instance GPU splits one card into isolated instances
  • Hardware support for confidential computing

Key specifications

ArchitectureNVIDIA Hopper
GPU memory80 GB HBM2e
Form factorDual-slot, full height, full length
CoolingPassive (server airflow)
InterfacePCIe

What Workstation does: We fit H100 to servers it is certified for, burn it in and set up CUDA, drivers and any vGPU or AI Enterprise licences.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Data-centre GPUs

NVIDIA RTX PRO 6000 Blackwell Server Edition

96 GB Blackwell GPU for rack servers

A passively cooled Blackwell card with 96 GB of memory for AI inference, rendering, simulation and virtual workstations in the data centre.

Who it suits: Enterprises consolidating AI and graphics workloads onto one GPU type

Benefits

  • 96 GB per GPU handles large models and big scenes
  • Runs both AI and professional graphics
  • Configurable power to suit the server

Key specifications

ArchitectureNVIDIA Blackwell
GPU memory96 GB GDDR7 with ECC
Max powerUp to 600 W (configurable)
InterfacePCIe 5.0 x16
Form factorDual-slot, passive (server airflow)

What Workstation does: We supply the cards on their own or in an RTX PRO Server, and test them at full load before delivery.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Data-centre GPUs

NVIDIA RTX PRO 4500 Blackwell Server Edition

Single-slot Blackwell GPU for dense servers

A compact, passively cooled 32 GB Blackwell GPU that lets you fit many cards in a server for inference, video and virtual desktops.

Who it suits: Teams scaling inference or virtual desktops across many users at a lower cost per GPU

Benefits

  • Single-slot design fits more GPUs per server
  • 32 GB of GDDR7 for mid-sized models
  • Lower power suits existing racks

Key specifications

ArchitectureNVIDIA Blackwell
GPU memory32 GB GDDR7
Form factorSingle slot, 4.4" H × 10.5" L
CoolingPassive (server airflow)

What Workstation does: We work out how many cards your servers can power and cool, then build and test the configuration.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Data-centre GPUs

NVIDIA L40S

48 GB all-rounder for AI and graphics

An Ada Lovelace data-centre GPU balanced for inference, fine-tuning and 3D graphics, and the GPU inside NVIDIA's OVX design.

Who it suits: Teams that need one GPU for both AI and visual workloads

Benefits

  • Strong inference and fine-tuning performance for its cost
  • Hardware ray tracing for rendering and Omniverse
  • A standard PCIe card for mainstream servers

Key specifications

ArchitectureNVIDIA Ada Lovelace
GPU memory48 GB GDDR6 with ECC
Form factorDual-slot, 4.4" H × 10.5" L
CoolingPassive (server airflow)
InterfacePCIe

What Workstation does: We match the L40S to certified servers, burn the build in and install it with drivers and licensing set up.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Data-centre GPUs

NVIDIA L40

48 GB GPU for rendering and virtual workstations

The L40 concentrates on graphics: rendering, Omniverse and virtual workstations in the data centre.

Who it suits: Design and media teams moving workstations into the data centre

Benefits

  • 48 GB for large scenes and assets
  • Supports NVIDIA virtual GPU software
  • Passive cooling for standard servers

Key specifications

ArchitectureNVIDIA Ada Lovelace
GPU memory48 GB GDDR6 with ECC
Form factorDual-slot, 4.4" H × 10.5" L
CoolingPassive (server airflow)
InterfacePCIe

What Workstation does: We set up vGPU profiles and licences so your users get remote workstations that feel local.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Data-centre GPUs

NVIDIA L4

Low-profile GPU for efficient inference and video

A small, low-power Ada Lovelace card for video AI, inference and virtual desktops, from the edge to the data centre.

Who it suits: Organisations adding AI to many servers, or to edge sites with tight power budgets

Benefits

  • Low power and a low-profile card fit almost any server
  • Well suited to video analytics and inference
  • Scales out economically across many nodes

Key specifications

ArchitectureNVIDIA Ada Lovelace
GPU memory24 GB GDDR6
Form factorSingle-slot, low profile
CoolingPassive (server airflow)
InterfacePCIe

What Workstation does: We check compatibility with your existing servers, supply the cards and set up drivers and inference software.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Networking

NVIDIA Spectrum-X Ethernet platform

Ethernet tuned for AI factories

Spectrum-X pairs Spectrum Ethernet switches with Spectrum-X SuperNICs to give AI clusters predictable, high-throughput Ethernet.

Who it suits: Organisations that want an AI fabric their network team already knows how to run

Benefits

  • Higher effective bandwidth for GPU-to-GPU traffic than standard Ethernet
  • Uses familiar Ethernet tools and skills
  • Part of NVIDIA's validated AI factory designs

Key specifications

TypeEthernet networking platform
ComponentsNVIDIA Spectrum Ethernet switches + Spectrum-X SuperNICs
Use caseAI clusters and AI factories

What Workstation does: We design the fabric, supply switches, SuperNICs and cables, install and test it, and document it for your team.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Networking

NVIDIA Quantum-X800 InfiniBand platform

Next-generation InfiniBand for large-scale training

Quantum-X800 switches and ConnectX-8 SuperNICs form NVIDIA's highest-performance InfiniBand fabric for AI training and HPC.

Who it suits: HPC centres and AI teams training at large scale

Benefits

  • Very low latency for tightly coupled jobs
  • Designed for the largest training and HPC clusters
  • Managed and monitored with UFM

Key specifications

TypeInfiniBand networking platform
ComponentsNVIDIA Quantum-X800 InfiniBand switches + ConnectX-8 SuperNICs
Use caseLarge-scale AI training and HPC

What Workstation does: We design the topology, supply and cable every link, and bring the fabric up with UFM monitoring in place.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Networking

NVIDIA Spectrum Ethernet switches

Data-centre Ethernet switches at up to 800 Gb/s

Spectrum switches carry AI, storage and cloud traffic, on their own or as part of Spectrum-X.

Who it suits: Data-centre and network teams refreshing leaf and spine switching

Benefits

  • Port speeds up to 800 Gb/s
  • Works in AI fabrics and general data-centre networks
  • Pairs with NetQ for network operations and telemetry

Key specifications

TypeEthernet switch family
Port speedUp to 800 Gb/s
UseAI and cloud data-centre fabrics

What Workstation does: We size ports and optics, configure the switches and integrate them with your existing network.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Networking

NVIDIA Quantum InfiniBand switches

Low-latency switching for HPC and AI

Quantum InfiniBand switches build the low-latency fabrics that HPC and AI clusters rely on.

Who it suits: Research computing and AI teams with tightly coupled workloads

Benefits

  • Very low latency between nodes
  • Proven in HPC and AI clusters
  • Central management with UFM

Key specifications

TypeInfiniBand switch family
UseHPC and AI data centres

What Workstation does: We plan the topology, supply cables and optics, and install and verify the fabric.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Networking

NVIDIA ConnectX NICs and SuperNICs

Network adapters for Ethernet and InfiniBand

ConnectX adapters connect servers to the fabric. SuperNICs such as ConnectX-8 are tuned for GPU-to-GPU traffic in AI clusters.

Who it suits: Anyone connecting GPU servers or storage to a high-speed network

Benefits

  • One family covers Ethernet and InfiniBand
  • SuperNICs give each GPU its own high-speed path
  • Hardware offloads reduce CPU load

Key specifications

TypeNetwork adapter and SuperNIC family
FabricsEthernet and InfiniBand
Top speed800 Gb/s per GPU (ConnectX-8 SuperNIC)

What Workstation does: We match adapters, cables and transceivers to your switches and servers, and install firmware and drivers.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Networking

NVIDIA BlueField DPUs

Data processing units for networking, storage and security

BlueField DPUs take networking, storage and security work off the server CPU and isolate it in dedicated hardware.

Who it suits: Cloud builders, AI factories and security-conscious organisations

Benefits

  • Frees CPU cores for applications
  • Isolates infrastructure services from tenant workloads
  • Programmable with NVIDIA DOCA

Key specifications

TypeData processing unit (DPU) family
GenerationsBlueField-3, BlueField-4
SoftwareNVIDIA DOCA

What Workstation does: We supply and fit BlueField cards, and help you deploy the DOCA services you need.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Software

NVIDIA AI Enterprise

Supported software for production AI

NVIDIA's suite of AI frameworks, NIM microservices and tools, with enterprise support and long-life release branches.

Who it suits: Any organisation running AI in production on NVIDIA GPUs

Benefits

  • Enterprise support and stable release branches
  • NIM microservices make models quicker to deploy
  • Runs on NVIDIA-Certified systems on premises or in the cloud

Key specifications

LicensingPer GPU subscription
IncludesAI frameworks, NIM microservices, pretrained models
SupportNVIDIA Enterprise Business Standard Support
Trial90-day evaluation

What Workstation does: We quote and activate licences, install the software with your hardware and remind you before renewal.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Software

NVIDIA Mission Control

Operations software for AI factories

Mission Control automates the day-to-day running of large GPU clusters, from workload orchestration to health checks and recovery.

Who it suits: Operators of DGX SuperPOD and other large AI clusters

Benefits

  • Automates routine cluster operations
  • Improves resilience by detecting and recovering from faults
  • One view of workloads and infrastructure

Key specifications

TypeAI-factory operations and cluster management software
FunctionsWorkload orchestration, infrastructure resiliency, cluster automation
Licence basisConfirmed on quote

What Workstation does: We deploy Mission Control with your cluster and train your operators to use it.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Software

NVIDIA Run:ai

GPU orchestration and scheduling

Run:ai pools GPUs across teams and allocates them on demand, so expensive hardware stays busy rather than idle.

Who it suits: Organisations sharing GPUs between many data scientists or projects

Benefits

  • Higher GPU utilisation through dynamic pooling
  • Quotas, priorities and access control for fair sharing
  • Works across on-premises, hybrid and cloud environments

Key specifications

TypeGPU orchestration and scheduling platform
Runs onKubernetes
DeploymentOn premises, hybrid or cloud
Licence basisConfirmed on quote

What Workstation does: We install Run:ai on your Kubernetes cluster, set up quotas with your teams and support it.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Software

NVIDIA Base Command Manager

Cluster provisioning and monitoring

Base Command Manager provisions, monitors and manages GPU clusters, from a handful of nodes upwards.

Who it suits: IT teams running GPU clusters of any size

Benefits

  • Automates provisioning on Arm and x86
  • Health dashboards and real-time monitoring
  • Web interface, command line and API

Key specifications

TypeCluster management software
Free licenceUp to 8 accelerators per system
Current releaseBase Command Manager 11
InterfacesBaseView web UI, CLI, API

What Workstation does: We install and configure Base Command Manager as part of the clusters we build.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Software

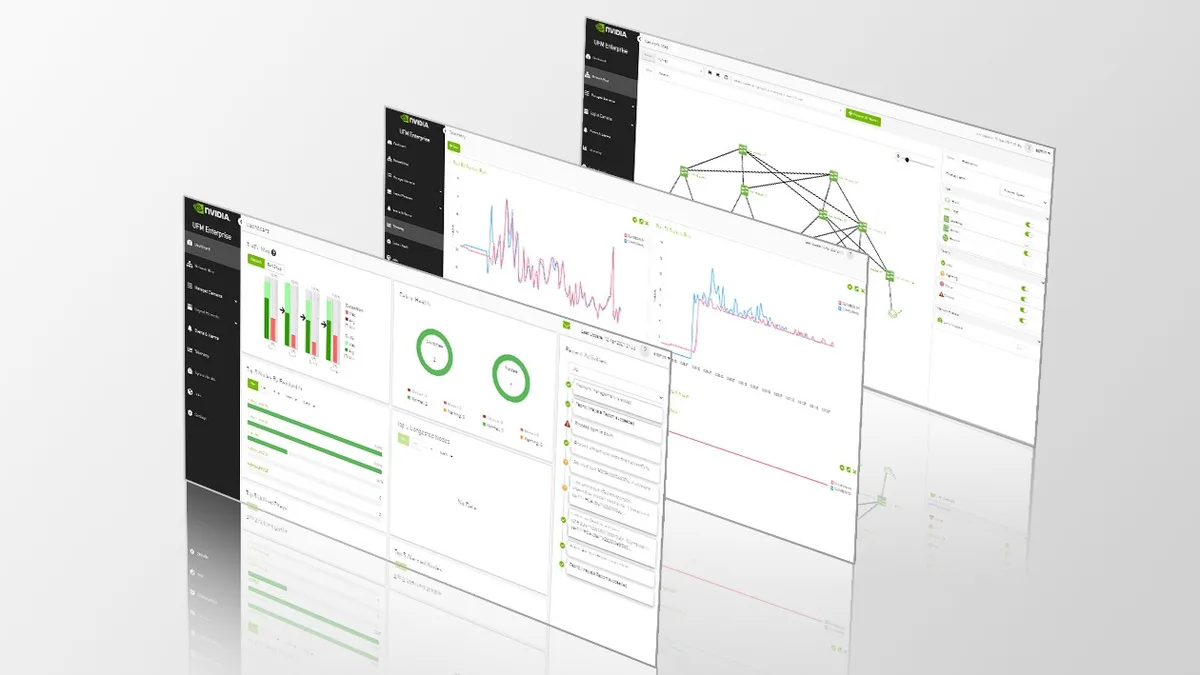
NVIDIA UFM

Unified Fabric Manager for InfiniBand

UFM monitors, manages and helps troubleshoot InfiniBand fabrics.

Who it suits: Teams running InfiniBand clusters

Benefits

  • Real-time fabric telemetry
  • Faster fault finding
  • Central management of switches and links

Key specifications

TypeInfiniBand fabric management and telemetry software
Works withNVIDIA Quantum InfiniBand switches

What Workstation does: We deploy UFM with your fabric and set up alerts that match your operating procedures.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Software

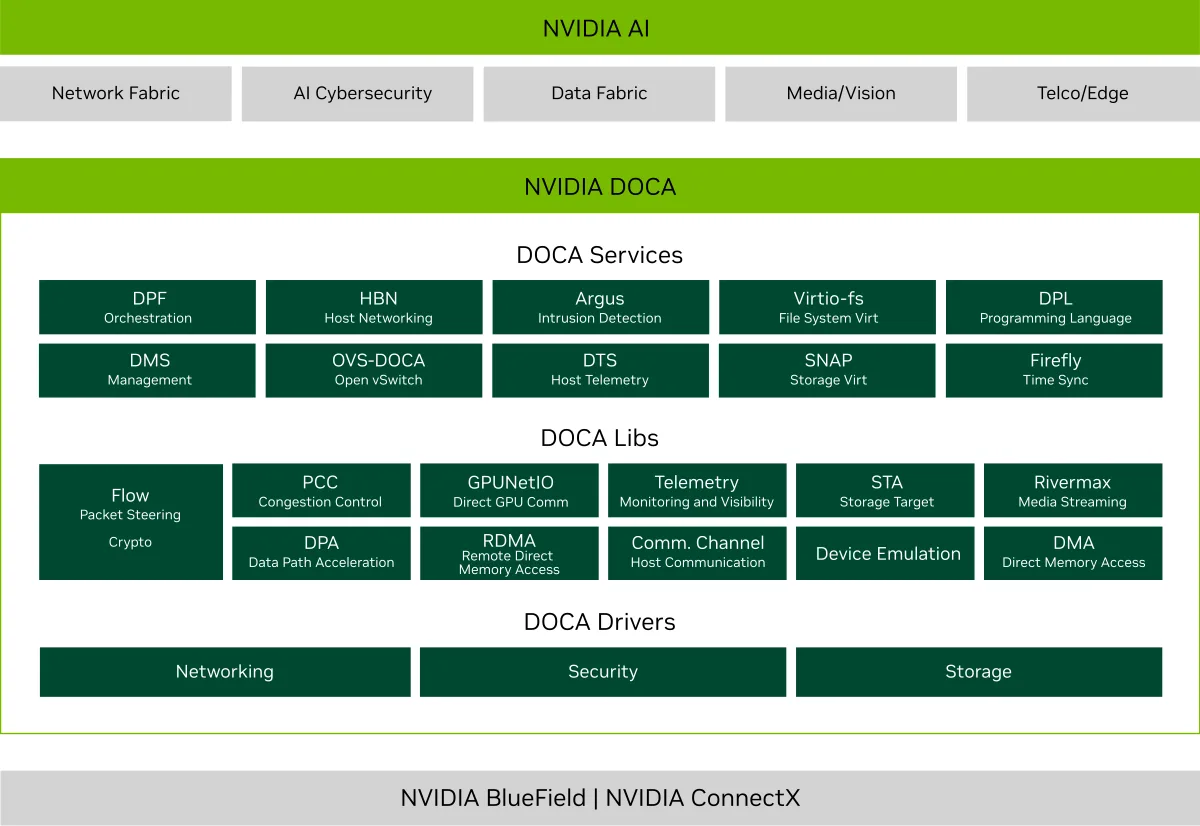
NVIDIA DOCA

Software framework for BlueField and SuperNICs

DOCA is the SDK and runtime for building services that run on BlueField DPUs and SuperNICs.

Who it suits: Developers and platform teams building on BlueField

Benefits

  • One framework across DPU and SuperNIC generations
  • Speeds up development of offloaded services
  • A runtime for deploying those services in production

Key specifications

TypeSDK and runtime framework
Runs onNVIDIA BlueField DPUs and SuperNICs

What Workstation does: We help set up DOCA environments and deploy services on the BlueField cards we supply.

Priced on quoteRequest a quote ↗
View on NVIDIA.com ↗

Specifications are summarised from NVIDIA's published information and can change between revisions. Figures marked sparse assume sparsity. We confirm the exact configuration, price and lead time on every quote.

What Workstation does on every order

The same five steps whether you buy one GPU or a row of racks

Sizing

We start from your models, data, users and site, then size compute, memory, network, power and cooling.

Supply

We source through NVIDIA and its server partners, confirm lead times and keep you updated until delivery.

Build and burn-in

Systems are assembled, imaged and stress tested at full load in our UK workshop before they ship.

Install

Our engineers deliver, rack, cable and commission on site, then hand over with documentation.

Support

The same team handles software issues, upgrades, licence renewals and warranty claims.

All NVIDIA categories

Trade membership

Trade members get free technical support on every order and unlimited engineer time — help with configuration, drivers, software and troubleshooting, for as long as you own the kit.

Explore Trade membership

Frequently asked questions

Why is everything priced on quote?

Accelerated computing prices and allocations change quickly, and most orders depend on the exact configuration, site and software. A quote lets us confirm current price, availability and lead time for what you actually need.

Can you supply a single GPU rather than a full system?

Yes. We supply individual data-centre GPUs, but we always check that your server is certified to power and cool them, and we can fit and test them for you.

Do you install rack-scale and liquid-cooled systems?

Yes. For systems such as GB300 NVL72 we work with your facilities team on power, cooling and floor loading well before delivery, then install and commission on site.

Which NVIDIA platform should we start with?

It depends on your models, users and site. Many teams start with RTX PRO Server or L40S for mixed AI and graphics, and move to HGX or DGX for large-scale training. Talk to an engineer and we will recommend a starting point.

Plan your NVIDIA accelerated computing project

Tell us what you need to run and where it has to live. An engineer will come back with a recommended configuration and a quote.

Talk to an engineer