The Workstation Blog
GPU
Posts tagged GPU.
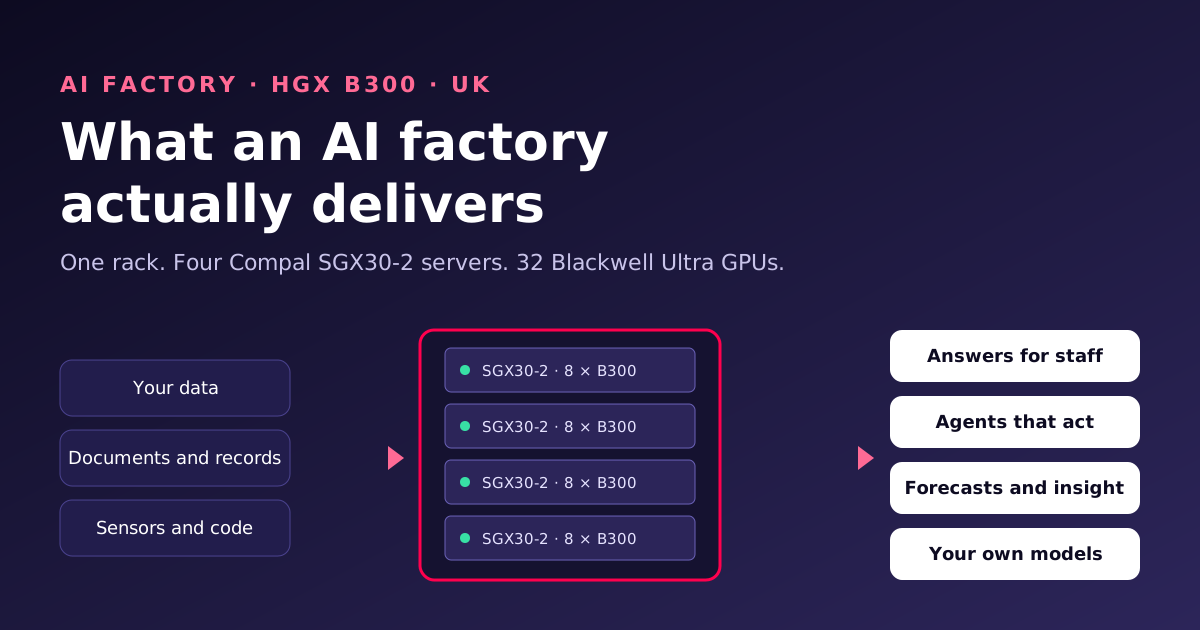
What an AI Factory Actually Delivers: One Rack, 32 Blackwell Ultra GPUs and the Work It Does for You
An AI factory turns your own data into answers, agents, forecasts and trained models on hardware you control. Here is what goes in, what comes out, how the work flows every day, and what a rack of four Compal SGX30-2 servers with 32 NVIDIA Blackwell Ultra GPUs needs to run.
 Balinder WaliaRead

Turbocharging LLMs
Workstation on turbocharging LLMs: PagedAttention paging for KV cache, vLLM serving, Self-Debugging for agents, PowerInfer token rates, and EG-MLA memory cuts — with production trade-offs.
Balinder WaliaRead 
Large Language Models Explained: How LLMs Work and How to Run Your Own on Kubernetes
What are Large Language Models and how do they work? A clear, non-technical explainer for managers and engineers — tokens, embeddings, transformers, training and inference — plus production Kubernetes YAML to deploy your own LLM with Ollama and vLLM.
Balinder WaliaRead