Wikipedia banned AI-written articles: what teams that reuse it should change

Wikipedia sits upstream of a lot of software: search features, chatbots, retrieval pipelines and internal knowledge bases all quote it. In 2026 English Wikipedia formally banned AI-written article text, while its volunteers report a steady flow of machine-written drafts to clean up. If your product reuses Wikipedia, this post shows how to pin, watch, review and attribute what you take so that AI-written errors upstream do not become your errors downstream.
What changed in 2025 and 2026
The rule: no LLM-written article text
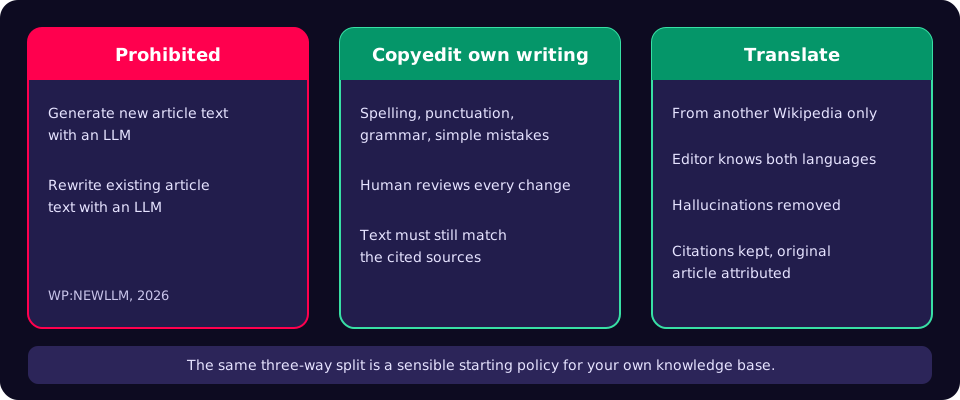
English Wikipedia's content guideline Writing articles with large language models (shortcut WP:NEWLLM) now states that using large language models (LLMs) to generate or rewrite article content is strictly prohibited [1]. It has two exceptions. Editors may use an LLM to suggest corrections to their own writing, limited to spelling, punctuation, grammar and similar simple mistakes, and must check that the copyedited text is still supported by its sources [1]. And editors may use LLMs to translate articles from another language's Wikipedia, under a separate guideline [1].
That translation guideline is stricter than "AI translation is allowed" suggests. The editor must be skilled enough in both languages to confirm accuracy, be reasonably sure the original article is not itself LLM-generated, remove hallucinations, make sure contestable claims carry inline citations, and attribute the original article [2]. According to MediaNama's report, the request for comment that led to the ban closed on 20 March 2026 with 44 votes in favour and two against [3]. The rule applies to English Wikipedia; other language editions set their own policies.
The reality: AI text still arrives
A rule does not stop people trying. IEEE Spectrum reports that WikiProject AI Cleanup, a volunteer effort launched in 2023 to find and remove AI-generated material, saw the detection tool Pangram flag perhaps 20% of new articles and drafts as AI-generated in late 2025, falling to about 15 to 16% in early 2026 [4]. Editors quoted there say AI citations that do not support the text they are attached to are extremely common, and list tell-tale patterns such as stock phrases, tidy "rule of three" lists and implausible output volume [4].
Wiki Education, which supports students editing Wikipedia as coursework, published similar findings in January 2026. Pangram classified all of its student edits from 2015 up to ChatGPT's launch as human-written, which gives a useful baseline [5]. Since 2022, 178 of 3,078 new articles created through its programmes were flagged as AI-generated, and more than two-thirds of the flagged articles failed verification: the text looked plausible but the cited sources did not support it [5]. Its participants mostly used AI for research and feedback, such as finding sources and spotting gaps, and none reported using it to draft assignment text [5].
The traffic: fewer human readers, more bots
The Wikimedia Foundation reported in October 2025 that human pageviews were down roughly 8% on the same months of 2024, after it reclassified traffic that turned out to be bots, and linked the decline partly to search engines answering directly with generative AI [6]. Separately, it said bandwidth used for downloading multimedia had grown 50% since January 2024, and that at least 65% of its most resource-intensive traffic came from bots [7]. Fewer human visitors plausibly means fewer people noticing and fixing errors, and the scraping load is why the Foundation wants reusers on well-behaved, identifiable access patterns.
For engineering teams, the consequence is simple. Wikipedia remains an excellent starting point, with over seven million English articles [8], but any single page at any single moment may contain recent, unverified text. Your pipeline should assume that.
How AI-written errors reach your product
| Path | Typical failure | Control |
|---|---|---|
| Retrieval-augmented chatbot pulls live article text | Answers quote a sentence added yesterday that its citation does not support | Index pinned revisions; re-index only after review |
| Product copy or help docs paraphrase Wikipedia | Definition drifts from the source law or standard | Follow the citation to the primary source and cite that instead |
| Training or fine-tuning corpus scraped from dumps | Mix of human and machine text with no provenance | Record dump date and revision ids; keep a pre-2022 baseline for comparison [5] |
| Internal wiki seeded from Wikipedia with LLM help | Your own staff repeat the pattern Wikipedia banned | Adopt the prohibited/allowed split as internal policy [1] |
A playbook for reusing Wikipedia safely
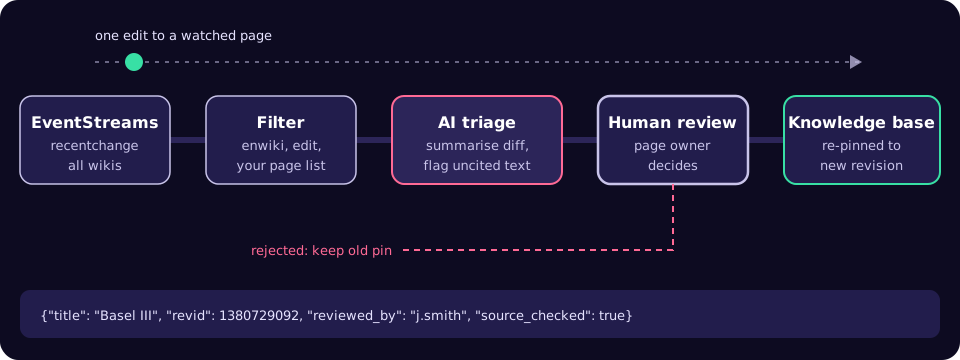
- List the pages that matter. Usually a few dozen to a few hundred: regulatory concepts, clinical terms, product categories. Give each an owner.
- Pin revisions. Store the revision id and timestamp of every page you ingest, and link to the permanent
oldidURL rather than the live title. - Watch for changes. Subscribe to Wikimedia's public EventStreams feed and filter for your pages, or poll the revisions API on a schedule.
- Triage changes, do not auto-accept them. A model can usefully summarise a diff and check whether new sentences have citations. A person decides whether your copy or index changes.
- Follow claims to the cited source. For anything regulated (tax rates, capital rules, drug interactions), the Wikipedia article is a pointer. Cite the statute, regulator or paper directly.
- Attribute properly. Wikipedia text is licensed CC BY-SA 4.0; reusers must credit the authors (a link to the page is enough), link the licence and say if they changed the text [9].
- Be a polite client. Wikimedia requires a descriptive User-Agent with contact details on every request [10], and asks API clients to make requests in series, batch titles, and use the
maxlagparameter for non-interactive jobs [11].
The code
Watching live edits needs nothing more than curl and jq (1.6 or later). EventStreams sends newline-delimited JSON when you ask for application/json, filtering happens on the client, and Wikimedia's documentation says to drop its test "canary" events [12]:
curl -s -A "AcmeKB-Watch/1.0 (https://example.org/kb; kb-team@example.org)" \
  -H 'Accept: application/json' \
  https://stream.wikimedia.org/v2/stream/recentchange |
jq -c --unbuffered 'select(.meta.domain != "canary" and .wiki == "enwiki"
    and .type == "edit" and .namespace == 0
    and (.title | IN("Basel III", "Capital gains tax in the United Kingdom")))
  | {title, user, bot,
     diff: "https://en.wikipedia.org/w/index.php?diff=\(.revision.new)&oldid=\(.revision.old)"}'
To pin pages at ingestion time, ask the MediaWiki Action API for the current revision of up to 50 titles per request. This uses only the Python standard library:
import json
import urllib.parse
import urllib.request

API = "https://en.wikipedia.org/w/api.php"
UA = "AcmeKB-Sync/1.0 (https://example.org/kb; kb-team@example.org)"

def latest_revisions(titles):
    """Return the current revision id and timestamp for up to 50 titles."""
    params = {
        "action": "query",
        "prop": "revisions",
        "rvprop": "ids|timestamp",
        "titles": "|".join(titles),
        "format": "json",
        "formatversion": "2",
        "maxlag": "5",
    }
    req = urllib.request.Request(
        API + "?" + urllib.parse.urlencode(params), headers={"User-Agent": UA}
    )
    with urllib.request.urlopen(req, timeout=30) as resp:
        data = json.load(resp)
    out = {}
    for page in data["query"]["pages"]:
        if page.get("missing"):
            continue
        rev = page["revisions"][0]
        out[page["title"]] = {
            "revid": rev["revid"],
            "timestamp": rev["timestamp"],
            "permalink": f"https://en.wikipedia.org/w/index.php?oldid={rev['revid']}",
        }
    return out

print(json.dumps(latest_revisions(["Basel III", "Capital gains tax in the United Kingdom"]), indent=2))
Store the result next to each chunk you index, along with who reviewed it and whether the underlying citation was checked. If the API returns a maxlag error, wait and retry with backoff rather than hammering it [11].
Checklist
- Every Wikipedia-derived chunk in your index carries a title, revision id, timestamp and permalink.
- A named owner watches each high-stakes page.
- Diffs are summarised by a model but accepted by a person.
- Regulated facts cite a primary source, with Wikipedia as background only.
- Your User-Agent names your app and gives a contact address.
- Attribution and the CC BY-SA 4.0 licence link appear wherever text is shown to users [9].
- Your internal policy on LLM-written documentation is written down, ideally mirroring Wikipedia's split [1].
Common mistakes
- Indexing the live title. You cannot reproduce or audit an answer if the page has changed since.
- Trusting a citation because it exists. Wiki Education found most flagged AI text failed verification despite carrying citations [5].
- Treating AI detectors as proof. Pangram scores are a triage signal; the volunteers using it still verify by reading sources [4].
- Scraping HTML in parallel with a browser User-Agent. This breaks Wikimedia's etiquette and risks being blocked [10][11].
- Dropping attribution after paraphrasing. Modified text is still a derivative work under the licence [9].
What to do this week
- Search your codebase and content pipeline for
wikipedia.organd list every place Wikipedia text enters a product or index. - For the ten most important pages, record the current revision id with the script above.
- Run the EventStreams command for a day against those titles and see how often they change.
- Pick one regulated fact your product states and replace its Wikipedia citation with the primary source.
- Draft a one-paragraph internal rule for LLM use in documentation, modelled on WP:NEWLLM.
None of this needs new infrastructure; it needs provenance and a review step in the place where outside knowledge enters your systems. If you are building retrieval or knowledge pipelines over sensitive data and want them reviewable from day one, our private AI team can help.
References
- Wikipedia: Writing articles with large language models (content guideline, WP:NEWLLM), English Wikipedia.
- Wikipedia: LLM-assisted translation, English Wikipedia.
- English Wikipedia bans AI-generated text, allows limited use for copyediting and translation, MediaNama, 26 March 2026.
- How Wikipedia's editors keep the online encyclopedia human-written, Eliza Strickland, IEEE Spectrum, 21 October 2026.
- Generative AI and Wikipedia editing: what we learned in 2025, LiAnna Davis, Wiki Education, 29 January 2026.
- New user trends on Wikipedia, Marshall Miller, Diff (Wikimedia Foundation), 17 October 2025.
- How crawlers impact the operations of the Wikimedia projects, Diff (Wikimedia Foundation), 1 April 2025.
- Special:Statistics, English Wikipedia (7,259,335 articles on 4 November 2026).
- Wikipedia: Copyrights, English Wikipedia.
- Wikimedia Foundation User-Agent Policy, Wikimedia Foundation.
- API: Etiquette, MediaWiki.
- EventStreams HTTP Service, Wikitech.