Secure AI Systems: A SRE Imperative

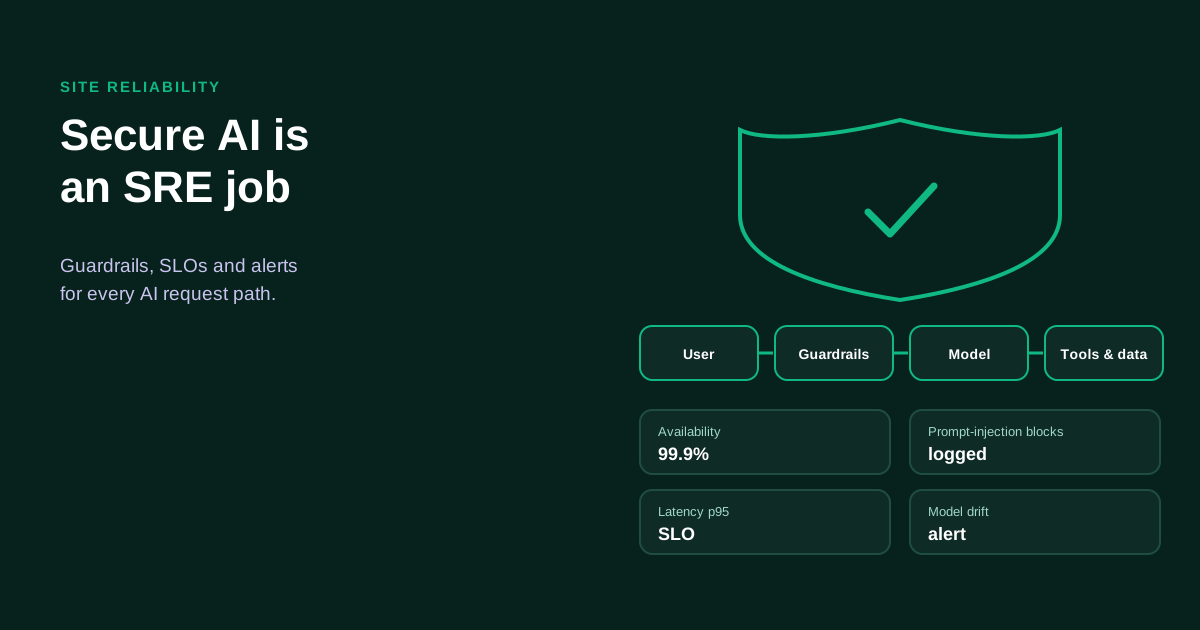
Integrating AI into SRE: Challenges and Opportunities
Site Reliability Engineering is about making systems scalable, reliable, and efficient. Google engineers use SRE principles and practices to make some of the world's largest systems scalable, reliable, and efficient--lessons directly applicable to your organization [1].
For readers in Manufacturing, Supermarkets, Banking, Education, HealthTech, FinTech and Tax Returns, that redefinition shows up in the same place it shows up everywhere: in production systems that must stay up, stay correct, and stay secure. The subject means the same thing in these sectors — uptime, data integrity, and controlled change — even if the data and consequences differ.
Secure AI Systems in an SRE context means treating models as production services whose security is a continuous property of training, serving, and feedback, not a one-time gate. It combines SRE reliability practices — SLOs, error budgets, incident response — with end-to-end data security, provenance, and access control for model inputs, outputs, and artifacts.
The opportunity is to bring SRE discipline to AI workloads. The challenge is that AI introduces non-determinism, large data pipelines, and model-specific failure modes that traditional monitoring does not capture well. The SRE response is not to treat models as black boxes, but to treat them as production services with SLIs, error budgets, and incident response.
Security is crucial to the design and operation of scalable systems in production, as it plays an important part in product quality, performance, and availability [1]. When AI is added to SRE scope, security moves from a gate at deploy time to a continuous property of training, serving, and feedback.
SRE differs from traditional IT operations in AI systems by focusing on measurable reliability targets and automation rather than manual upkeep. While IT operations often centers on keeping servers running, SRE in AI systems owns SLOs for both system and model quality, error budgets for model rollouts, and automated incident response for drift and adversarial inputs.
Designing Secure AI Systems: Principles and Practices
Designing secure AI systems follows a lifecycle rather than a one-off checklist.
Principles that transfer across Manufacturing, Supermarkets, Banking, Education, HealthTech, FinTech and Tax Returns:
- Treat models as services. Version them, canary them, and roll them back.
- Define SLIs for both system and model quality. System latency and availability are necessary but not sufficient.
- Secure the data path end to end. Training data, feature stores, and inference inputs all need provenance and access control.
- Build observability for model behavior, not just host metrics. Drift, data skew, and adversarial inputs are reliability signals.
- Keep security in the loop during design and operation. Security is crucial to the design and operation of scalable systems in production [1].
Practical practices include isolation of model serving, policy enforcement at the API gateway, and automated security auditing in CI/CD. The Site Reliability Workbook contains practical examples from Google’s experiences and case studies from Google’s Cloud Platform customers [1].
Actionable steps for teams:
- Version model artifacts and serve behind a gateway with canary releases and automated rollback on SLO breach.
- Define model SLIs such as prediction latency p95, availability, and accuracy drift, and allocate error budgets for model changes.
- Enforce input validation and output filtering at the gateway, and log requests with immutable audit trails.
- Instrument telemetry for data drift, feature skew, and adversarial patterns, and alert on deviation from baseline.
For local experimentation and evaluation, teams often standardize on reproducible runtimes. A common starting point for Ollama is:
curl -fsSL https://ollama.com/install.sh | sh
The Ollama model can be installed using the command curl -fsSL https://ollama.com/install.sh | sh [2].
OpenAI's Codex and Ollama work seamlessly together [2].
When evaluating hardware for private inference, the NVIDIA DGX Spark is referenced in recent operator write-ups. The DGX Spark is an ARM64 device with 128GB of memory that’s available to both the GPU and the 20 CPU cores at the same time [3]. It has 128 GB of coherent unified system memory [4]. The NVIDIA GB10 Grace Blackwell Superchip delivers up to 1 PFLOP of sparse FP4 tensor performance [4]. PFLOP means peta floating point operations per second, i.e., ~10^15 operations per second. FP4 refers to 4-bit floating point precision, a reduced precision format used to increase throughput for AI workloads at the cost of numerical accuracy. Sparse means the hardware skips zero-valued computations to improve efficiency.
The DGX Spark has a 10 GbE RJ-45 Ethernet port [4] and two QSFP ports driven by NVIDIA ConnectX-7 NIC capable of up to 200 Gbps [4]. The DGX Spark also supports the larger gpt-oss-120b model, fitting the entire model into the 120GB of VRAM provided by the GB10 Grace Blackwell Superchip [2].
Operational notes from practitioners mention that the official Docker container for the NVIDIA DGX Spark is available [3] and that NVIDIA now have extensive guides for getting things working on the Spark [3].
For lightweight JavaScript experiments, Brain.js is a library for building GPU-accelerated neural networks in JavaScript [5]. Brain.js performs computations using GPU and gracefully falls back to pure JavaScript when GPU is not available [5]. Brain.js provides multiple neural network implementations as different neural nets can be trained to do different things well [5]. Brain.js is modular, allowing for easy extendability [5].
Case Studies: AI in Manufacturing, Banking, and Healthcare
The Site Reliability Workbook contains practical examples from Google’s experiences and case studies from Google’s Cloud Platform customers [1]. The pattern across sectors is consistent: AI is introduced into a reliability-critical workflow, and SRE practices are extended to cover model inputs, outputs, and feedback.
In Manufacturing, the concern is continuity of production lines and safety of equipment. SRE framing focuses on availability of inference services and correctness of alerts.
In Banking, FinTech and Tax Returns, the concern is data confidentiality, auditability, and regulatory compliance. SRE framing focuses on access controls, immutable logs, and error budgets for decision systems.
In HealthTech and Education, the concern is privacy and impact on human outcomes. SRE framing focuses on data minimization, consent tracking, and reliability of assistive tools.
In Supermarkets, the concern is real-time demand forecasting and checkout reliability. SRE framing focuses on latency SLOs and graceful degradation when models are uncertain.
The constraints differ, but the SRE imperative is the same: define what good looks like, measure it, and automate responses.
Best Practices for Deploying AI in Production Environments
Deploying AI in production benefits from the same discipline used for any critical service.
- Start with a service model. Model artifacts are versioned, deployed behind a gateway, and monitored like any microservice.
- Establish guardrails before scale. Input validation, output filtering, rate limiting, and circuit breakers are reliability controls.
- Instrument for both system and model health. Logs, traces, and metrics should capture request latency, error rate, and model-specific signals.
- Use error budgets to balance innovation and stability. This is a core SRE practice that applies directly to AI rollouts.
- Automate security checks in the pipeline. Scanning, policy checks, and audit trails should run on every change.
Reliability in AI systems matters because non-deterministic outputs and data drift can cause silent failures. SRE ties reliability to measurable SLOs for latency, availability, and model quality, and uses error budgets to manage risk during experimentation.
Security in AI systems is important because models process sensitive data, learn from it, and make decisions. Within SRE, security becomes a continuous operational property enforced via provenance, access control, auditability, and automated policy checks across training, serving, and feedback loops.
When comparing deployment approaches, teams weigh trade-offs between latency, cost, and control.
| Approach | Control Level | Latency Profile | Operational Overhead | | Cloud managed model service | Low | Low | Low | | On-prem GPU appliance | High | Medium | High | | Hybrid with local fallback | Medium | Medium | Medium |
Cloud managed model service offers low operational overhead and low latency via managed scale, but provides low control over data residency and model customization. On-prem GPU appliance such as DGX Spark provides high control and data locality, with higher operational overhead for hardware, networking and maintenance. Hybrid with local fallback balances control and cost, allowing critical inference locally with cloud burst, at medium overhead.
The benefits of AI in production include automation of decision making, improved forecasting, and personalization. Trade-offs include increased complexity, non-deterministic behavior, higher observability requirements, and security risks from data exposure and model misuse. Informed decisions require matching deployment approach to threat model, data residency requirements, and reliability targets.
Conclusion: The Future of Secure and Reliable AI Systems
The SRE imperative remains unchanged: build systems that are scalable, reliable, and efficient, with security built in from design through operation [1].
For organizations in Manufacturing, Supermarkets, Banking, Education, HealthTech, FinTech and Tax Returns, the specifics of data and risk vary, but the core SRE contract does not. Define SLOs, measure them continuously, and respond automatically. Treat models as services, secure the entire data lifecycle, and learn from real-world examples.
The Site Reliability Workbook contains practical examples from Google’s experiences and case studies from Google’s Cloud Platform customers [1]. Those examples remain a useful reference as AI becomes a first-class citizen in production reliability.
Call to action: Start by defining SLOs for your first AI service, instrument model-specific signals alongside system metrics, and run a canary rollout with automated rollback. Audit your data path for provenance and access control, and add security checks to CI/CD for model artifacts. Review the Site Reliability Workbook for concrete SRE practices [1] and evaluate your deployment trade-offs against control, latency, and operational overhead needs.
References
- Google SRE book- Comprehensive guide to site reliability — landing.google.com
- NVIDIA DGX Spark performance · Ollama Blog — ollama.com (23 October 2025)
- NVIDIA DGX Spark: great hardware, early days for the ecosystem — simonwillison.net (15 October 2025)
- NVIDIA DGX Spark In-Depth Review: A New Standard for Local AI Inference - LMSYS Org — lmsys.org (14 October 2025)
- GPU accelerated Neural Networks in JavaScript — brain.js.org (7 July 2022)