NVIDIA NVKE and NVKR: Why GPU Kubernetes Is Becoming the AI Factory's Operating System
What NVIDIA open-sourced at KubeCon 2026, why it matters, and what it means for developers and DevOps engineers
 Balinder Walia14 de noviembre de 202610 min read
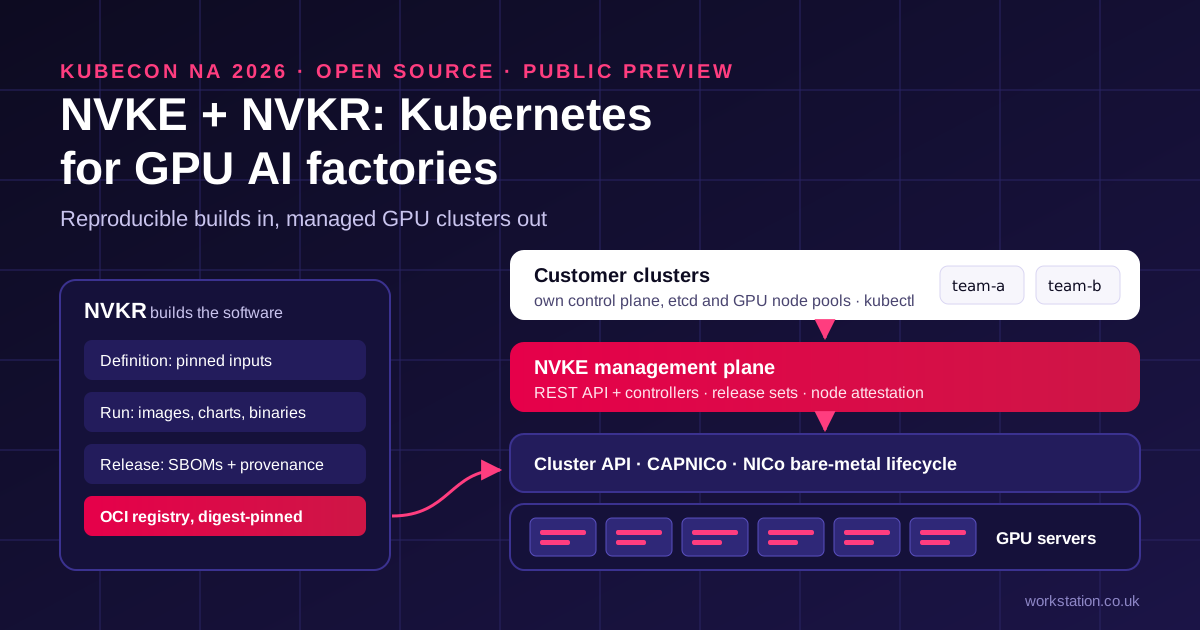
At KubeCon North America on 10 November 2026, NVIDIA open-sourced two projects: NVIDIA Kubernetes Engine (NVKE) and NVIDIA Kubernetes Recipes (NVKR). On the surface they are just more Kubernetes tooling. The bigger story is the direction they point in: GPU capacity is increasingly consumed through Kubernetes, and someone has to build, run and upgrade those clusters. This post explains what the two projects do in plain terms, why they matter, what they mean for developers and DevOps engineers, and who should look at them now.

What NVIDIA announced
NVIDIA published both projects on GitHub under its DSX AI Factory organisation, alongside a detailed walkthrough on the NVIDIA Technical Blog. They are components of the NVIDIA DSX AI Factory Platform, NVIDIA's reference design for building and operating GPU data centres.
- NVKE (NVIDIA Kubernetes Engine) is a management plane. You install it once, on a small cluster of your own servers, and it creates and operates separate Kubernetes clusters for your customers. Each customer cluster gets its own control plane, its own etcd database and its own GPU node pools. You manage them through an API and a command-line tool called
nvkectl; your customers use their clusters with ordinarykubectl. - NVKR (NVIDIA Kubernetes Recipes) is a build and release system. It takes a declared set of software versions, builds the node operating system images, container images, Helm charts and binaries, and records exactly what went into each one, with software bills of materials (SBOMs), provenance and signatures that you can verify against your own policy.
The two can be used together or separately. NVKE does not depend on NVKR at runtime, and NVKR can build artifacts for other Kubernetes management systems. NVIDIA reports that NVKE is a Certified Kubernetes AI Platform and Certified Kubernetes Installer, conformance tested on Kubernetes 1.36.
NVIDIA also named early adopters. NVIDIA Cloud Partners Firmus and SK Telecom are integrating NVKE and NVKR into their AI factories, and Mirantis, Rafay, Spectro Cloud, OpenNebula Systems and vCluster are integrating components into their managed Kubernetes products, with Netris enabling NVKE in its network automation.
Why this matters more than another Kubernetes tool
Five years ago, "GPU infrastructure" meant a few servers under a desk and a shared login. Today the people buying GPU capacity, whether a research group, a product team or an external customer, increasingly want it the way they get everything else: as a Kubernetes cluster they can point their existing tools at. That is a reasonable request. It is also a hard service to deliver. Behind "give me a cluster with four GPU nodes" sits a long list of jobs:
- finding free servers and booting them with the right operating system, drivers and agents;
- making sure a server is genuinely one of yours before it joins anyone's cluster;
- keeping one customer's cluster isolated from the next;
- upgrading Kubernetes and the node images without breaking running training jobs;
- knowing exactly which software versions are on every node when something goes wrong, and rebuilding them identically later;
- and qualifying all of that against several generations of GPU and several versions of Kubernetes.
Large public clouds solved this privately, with large internal teams. NVKE and NVKR are NVIDIA's attempt to give the same building blocks to everyone else who runs GPUs: specialist GPU clouds, telcos, sovereign AI factories, universities and enterprises with their own racks. The interesting signal is not that NVIDIA wrote a Kubernetes installer. It is that the company that makes the GPUs now treats operating them through Kubernetes as part of the product.
How it works, in four steps

- Build. NVKR builds the node image (a disk image with Kubernetes, the networking stack and the node agents installed), the NVKE controller image, its Helm chart and the
nvkectltool, all from version-pinned sources. - Bootstrap.
nvkectlstarts a small temporary cluster on a bootstrap machine. That temporary cluster asks NVIDIA Infra Controller (NICo), NVIDIA's bare-metal provisioning service, for three servers, boots them from the node image, and hands over to them. The three servers become the permanent management cluster and the temporary one is deleted. - Publish what customers may run. The operator publishes "release sets": a named, tested combination of machine image, Kubernetes version and node configuration. Customers choose a release by name; they never handle operating system images or boot scripts.
- Create clusters. A customer cluster is one short YAML request: Kubernetes version, three control-plane servers, a GPU node pool of a given size. NVKE provisions it, and the operator hands the customer a kubeconfig.
Two design choices stand out. First, every node must prove its identity, using its hardware security chip (TPM) and the SPIFFE/SPIRE identity framework, before it is given credentials to join a cluster. Second, NVKE uses the standard Kubernetes Cluster API to talk to the infrastructure, so the provisioning layer is a well-understood open interface rather than a black box. Our technote walks through every step with the commands, the configuration and the pinned versions.
What "public preview" really means here
NVIDIA is unusually direct about the current limits, and they matter for anyone planning a service:
- After installation the NVKE API runs over plain HTTP with authentication switched off. You must restrict the network, enable authentication and put TLS in front of it yourself.
- NVKE does no authorisation: any authenticated caller can create or delete any customer's cluster.
- The management cluster does not upgrade, scale or repair itself, and there is no documented upgrade or backup and restore procedure for it yet.
- Customers receive an administrator kubeconfig that cannot be revoked until its certificate expires.
- NICo is the default (and in practice the main) way to get machines.
- No NVKR release is "qualified" yet, and the full-disk-encryption node images are for evaluation only.
None of this is surprising for a first public release, and the public roadmaps show where it is heading. But it does mean that today NVKE is something to evaluate, not something to sell a service level on.
The takeaway for developers and DevOps engineers
There is a popular idea that AI engineering is replacing cloud and DevOps work. Announcements like this suggest the opposite. AI is creating new, harder demands on exactly those skills.
Knowing how to call a large language model through an API is useful. It is also the part that is easiest to learn and easiest to automate. The engineering depth is in understanding how AI systems run, scale and fail in production:
- GPU-aware scheduling. How Kubernetes places GPU workloads, what node pools per GPU generation look like, and why an idle GPU in a "running" job is the most expensive bug you will ever ship.
- Immutable, reproducible infrastructure. NVKR's whole premise is that you should be able to say exactly what is on a node and rebuild it byte for byte. That is DevOps and supply-chain security, applied to GPU fleets.
- Identity and isolation. Hardware attestation, per-cluster etcd encryption, network isolation between tenants and careful credential handling are platform-security skills, not data-science skills.
- Lifecycle and upgrades. Rolling a new Kubernetes version or driver across GPU nodes without killing a week-long training run is a planning and automation problem.
- Observability. NVKE ships an OpenTelemetry-based telemetry pipeline. Someone still has to decide what to measure, where it goes and what wakes a human up.
If you are a developer moving into AI, learning how these clusters are built and operated will make you far more useful than another prompt-engineering course. If you are already a platform or DevOps engineer, your skills are not being made redundant; they are about to be in demand on a new and much more expensive class of hardware.
Will GPU-focused Kubernetes platforms become a major part of enterprise AI?
Our view: yes, but not in the way the headlines might suggest. Most enterprises will not install NVKE themselves. What is likely is that the providers they buy GPU capacity from, specialist GPU clouds, telcos, sovereign AI programmes and managed service providers, will standardise on something like it, because it lowers the cost of offering "Kubernetes with GPUs" as a service. Enterprises will feel the effect as more consistent, more portable GPU clusters, wherever they rent or run them.
For organisations that do run their own GPU racks, the case is strongest when you are serving several teams or customers from one pool of hardware. A single team on a single cluster is usually better served by a mature, supported Kubernetes distribution today, while borrowing NVKR's discipline of pinned, signed, reproducible node images.

Who should look at NVKE and NVKR now
| You are | What to do now |
|---|---|
| A GPU cloud, hosting provider or telco offering Kubernetes to customers | Evaluate NVKE seriously. Run the local quickstart, then a lab on spare hardware with NICo, and map each preview limitation to your service commitments. |
| An enterprise or university sharing a GPU pool between departments | Run the local quickstart and follow the roadmap. Start using pinned, signed node images now, whatever installer you use. |
| A single team with one GPU cluster | Keep your current distribution. Borrow NVKR's ideas on reproducible builds and SBOMs. |
| Not running GPUs yet | Learn the operating model on a leased or managed GPU cluster first; the skills transfer directly. |
The local quickstart needs only a Linux host or virtual machine with at least 6 CPUs, 12 GiB of free memory and 100 GiB of free disk, plus Docker and virtual TPM support. No GPU and no NVIDIA account are required, so there is little reason for a platform team not to try it.
What Workstation does
We design, supply and run GPU infrastructure for UK organisations, and Kubernetes is how most of our customers consume it.
- Private GPU clouds. We plan and build GPU private clouds from scratch: servers, networking, storage and the Kubernetes layer on top, sized with our VRAM and readiness tools.
- Kubernetes platforms for AI. We set up GPU-ready Kubernetes, GitOps delivery and MLOps pipelines (see our posts on running your own LLMs on Kubernetes and Kubeflow and Argo CD), and we can help you plan an NVKE and NVKR evaluation on your own hardware.
- Leasing instead of buying. If capital is the blocker, gpuleasing.co.uk compares leasing and buying GPU servers for your workload.
Next steps
- Read the NVKE and NVKR technote for the full workflow, configuration, pinned versions and a hardening checklist for the preview.
- Try the NVKE repository local quickstart and browse the NVKR repository.
- Ask our AI Sales Engineer to size a GPU cluster for your workloads, or talk to us about a Kubernetes platform for your GPUs.
Facts about NVKE and NVKR are taken from NVIDIA's announcement and the projects' public documentation as of 14 November 2026. Both are in public preview, and their APIs and behaviour may change between releases.
Acknowledgement of rights: NVIDIA, the NVIDIA logo and DSX are trademarks and/or registered trademarks of NVIDIA Corporation in the United States and other countries. Kubernetes is a registered trademark of The Linux Foundation. Other product and company names mentioned are the property of their respective owners. All such rights are acknowledged and reserved to their owners.