On 21 October 2026, at GTC Berlin, Jensen Huang told the room that the infrastructure argument was no longer the interesting one. The factories, the CUDA stack and the GPUs were the foundation. The question he put next was what to do with them. Workstation engineers were in the hall at STATION-Berlin. This is what he said, checked against NVIDIA's published keynote transcript, and what it means if you are buying machines rather than a gigawatt campus.
AI became productive this year
Huang's line was plain. This last year, AI became productive. He pointed at the start of the year, when NVIDIA talked about OpenClaw, an open-source agent. That, he said, is what started the pattern now visible everywhere: agents that think, reason, iterate and use tools.
Useful agents are expensive in a specific way. They do not answer once. They loop. Each loop spends tokens. More agents, used by more people, each spending many tokens to think, is why he said token use and GPU demand have both gone through the roof. He did not publish a token chart in that passage. The claim is directional: agent workloads are the demand, not a single chat box.
Five elements, not one model
He then defined an agent as five things. The model is the language model running on GPUs, producing tokens the agent consumes. He called that the exoskeleton. The harness is the program that plans and calls tools. The harness sits in a sandbox, which isolates it from the rest of the system. The other two elements are knowledge and tools.
His own list, in the order he settled on: models, sandbox, harness, knowledge and tools.
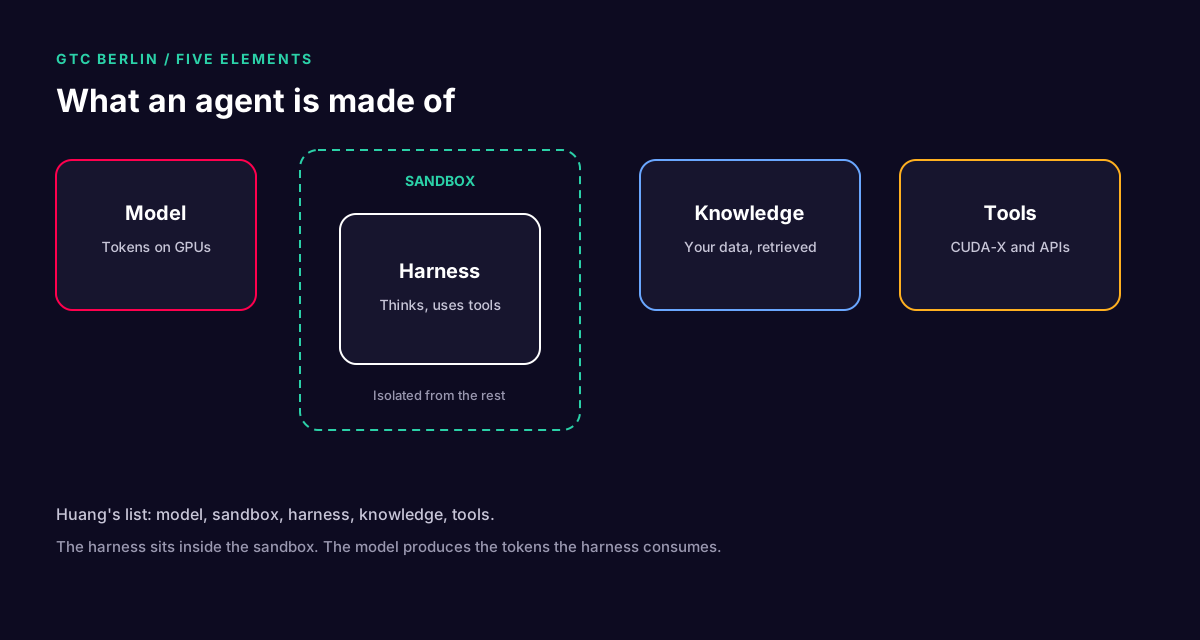
That split is the useful part for a buyer. A bigger GPU only feeds the model. It does not decide what the harness may touch, what knowledge it can see, or which tools it may call. Those are separate systems. Huang's next sentence was that the agent has to be secure before it is useful, because it is autonomous and it can reach files, networks and tools. Privileges should be minimal, and someone has to watch it. That is the OpenShell announcement, covered in the companion article.
What the rest of the keynote hung on this
Three further ideas sat on the same frame.
- Open models you can retrain. Nemotron for language, Cosmos for world models, GR00T for robotics, Alpamayo for autonomous driving, and Earth-2 for physics. Huang said NVIDIA ships weights, the data and the scripts, so a lab can see where the model came from. He was explicit that the language models are not automatically the frontier until a partner post-trains them on private data.
- A knowledge foundation. Unstructured documents go through Nemotron Parse, Nemotron Embed, cuVS and Nemotron Rerank. Structured data goes through Auto-Ontology, then cuDF for analysis and Kumo for prediction. His worked example was a supplier delay in a document, orders in SQL, and a search for a replacement part.
- The factory underneath. NVIDIA DSX is the full-stack AI factory reference design: compute, network, storage, software, power and cooling, starting from a digital twin. The Europe slide stacked applications, models, AI factories, NVIDIA compute and energy.
What this means on a workstation
Most companies in the room will not build a Vera Rubin NVL72 hall this year. They will run a harness, a sandbox and a model that fits on a desk or a single rack. The five-element picture still applies.
- The model can be Nemotron, a closed API, or both. Huang said every company will use closed models and open models, and will customise where the work is proprietary.
- The harness can be OpenClaw, Hermes, OpenHands, a LangChain or Deep Agents stack, or Python you write. He listed those as ways to build the harness that now sits inside OpenShell.
- Knowledge is your documents and your database, not a generic crawl of the web.
- Tools are where CUDA-X still matters: the libraries an agent calls when the job is science, engineering or a design file, not another paragraph of chat.
A Workstation build for that shape is a Linux or Mac Studio machine with enough memory for the model, a sandbox runtime, and a place to keep the documents and the SQL. The factory story is for when the token rate no longer fits one box. Huang's own close on the reference architecture was that agents think on Rubin, act on Vera, and are governed on BlueField. That is a data-centre sentence. The five elements are the part you can start on one machine.
Figures we are not treating as ours
NVIDIA's newsroom, the same day, said Vera Rubin NVL72 delivers 30 times the throughput per megawatt of the previous generation on agent workloads, that Vera CPUs deliver twice the performance of x86 at higher efficiency, and that Sentry on BlueField-4 can raise agent capacity by up to 20 percent. Those are NVIDIA's numbers, from their press note, not a Workstation benchmark. The keynote also said Vera Rubin is another 30 times Blackwell in two years. Same rule: cite it as theirs.
The long technical pieces that follow this one cover OpenShell and Sentry, the knowledge foundation, and DSX and the Europe stack.
A loop, not a reply
A chat reply is one call. An agent is a chain. The model reads a long prompt, writes a tool call, the harness runs the tool, and the result goes back into the next prompt. Huang's "enormous amount of tokens" is that chain, multiplied by how many agents are in flight. He did not say a team becomes ten times faster. He said the machines get busier because the software finally does work.
If you want a planning number, label it as a sketch. Suppose one agent run is eight model calls, and a person starts twenty runs in a day. That is 160 calls where a chatbot would have been 20. The GPUs did not get slower. The job shape changed. Change the 8 or the 20 and the sketch changes. Do not quote it as a benchmark.
What to write down before you buy
Map the five elements onto a sheet before you pick a GPU.
- Model. Which weights, at what precision, and how long a context you will actually send. VRAM follows from that. A 70-billion-parameter model in 4-bit is a different machine from the same model in 16-bit.
- Harness. OpenClaw, Hermes, OpenHands, a framework, or your own Python. The harness is software you can change. It is not a GPU SKU.
- Sandbox. OpenShell, or another runtime that can say no. If you skip this, the other four elements share one set of privileges.
- Knowledge. Which documents, which database, and who is allowed to retrieve them.
- Tools. The few APIs and CUDA-X libraries the job needs. Huang said the useful agent is the one that can call a real tool, and that those tools are why a GPU is faster than running the same library on a CPU. He spoke of 10, 50 or 100 times. That was a range from the stage, not a paper.
When that sheet fits on one workstation, buy the workstation. When the token rate needs a hall, you are in the DSX conversation. Both can be true in one company.
Sources
- NVIDIA on-demand transcript, GTC Berlin 2026 keynote SB61112: nvidia.com
- NVIDIA newsroom, 21 October 2026, OpenShell Reference Architecture: nvidianews.nvidia.com
- NVIDIA blog, live notes from the keynote: blogs.nvidia.com


