LLM Drift Detection in Regulated Environments

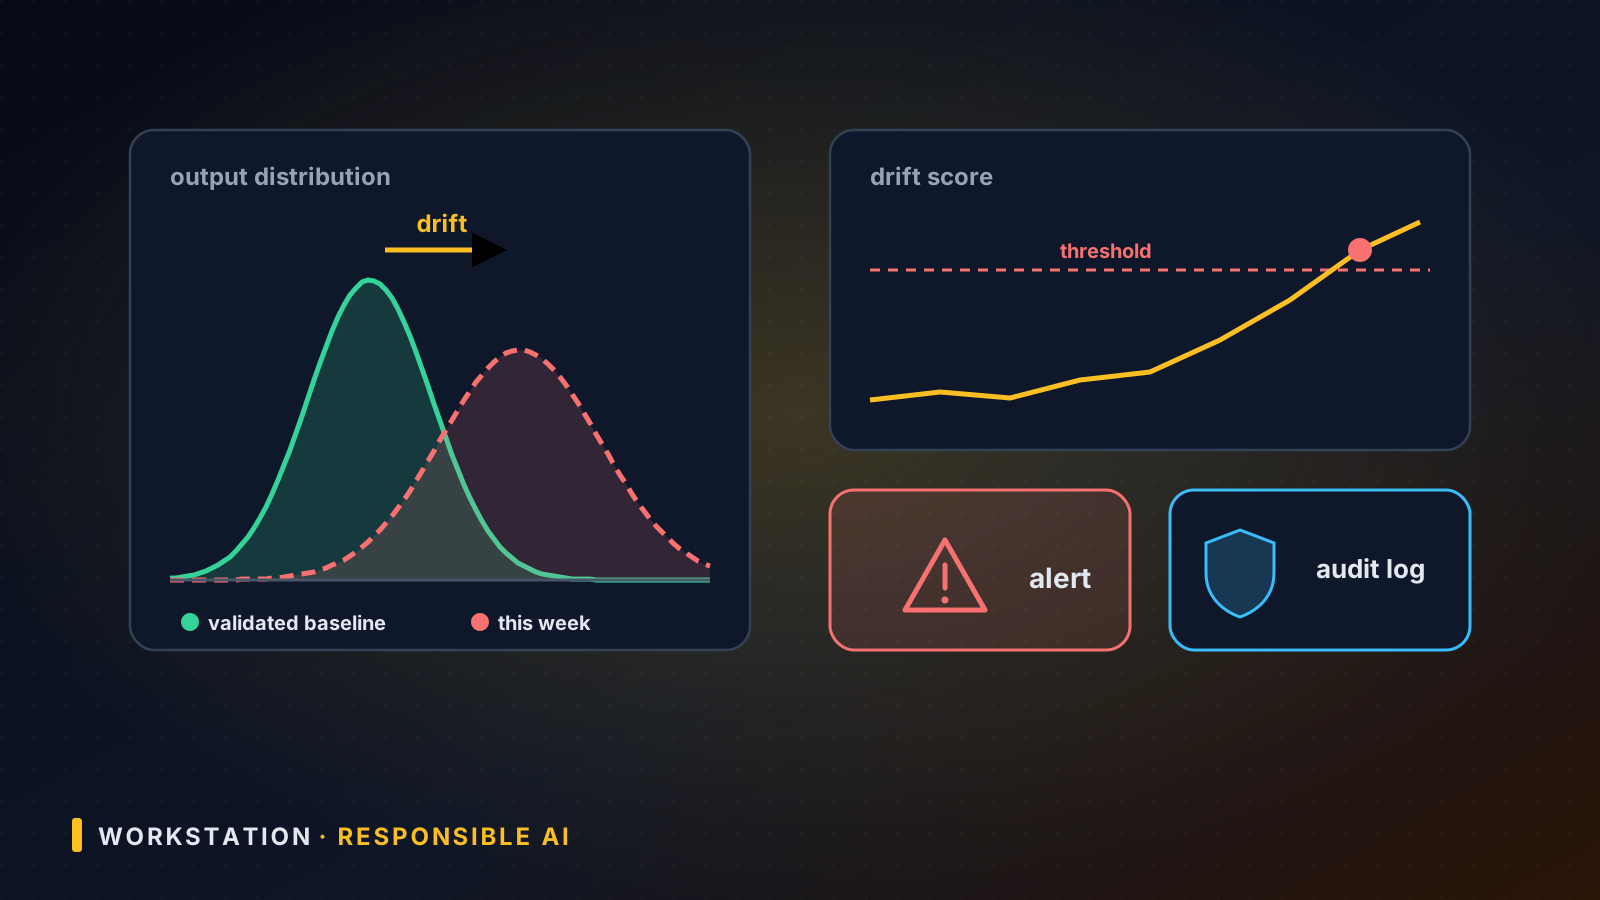
Regulated industries do not have the luxury of treating a Large Language Model deployment as an experiment. In banking, health tech, fintech and tax returns, a model that silently degrades can create compliance exposure, financial loss and direct harm to customers. Drift is drift everywhere in one sense. The constraints are what change.
The Importance of Responsible AI in Regulated Settings
For banking, education, health tech, fintech and tax returns, responsible AI is not a brand exercise. It is a control requirement. The EU AI Act organizes technical evidence of responsible AI practices under six principle groups and eighteen technical requirements [1].
In those sectors the consequences are concrete. A credit decision model that drifts can systematically disadvantage a protected group. A tax advice assistant that degrades can produce incorrect filings. A clinical summarization model that drifts can introduce unsafe recommendations. In education, drift can change the level of support offered to vulnerable students.
Machine learning models can stop working as expected, often for non-obvious reasons [2]. To catch issues with the model, it is not enough to just look at service metrics like latency [2]. Service metrics tell you the system is up. They do not tell you the output is still correct, fair and compliant.
This is why responsible AI moves from policy to engineering in regulated settings. The risk is not hypothetical; it is operational and auditable.
Technical Requirements for LLM Deployments
Regulated deployments need evidence, not vibes. COMPL-AI provides a technical interpretation of the EU AI Act that organises this evidence under six principle groups and eighteen technical requirements [1].
That framing is useful because it moves assessment from narrative to measurable artefacts. For a dashboard, the requirements translate into data you must continuously capture:
- Metrics: distribution of inputs, outputs, token usage, latency, refusal rates
- Metadata: schema, timing, prompt version, model version, data source
- Lineage: which training data, fine-tune data and prompt templates feed a given inference
- Logs: external system interactions, ELT/ETL impacts, user impact signals
Without metrics, we do not have knowledge about the internal properties of the data itself, making alerting based on real-time anomaly detection on metrics impossible [3]. Without metadata, we do not know the structure, structure, or timing of data, making use cases like schema change detection or satisfying Service Level Agreements by tracking outages impossible [3]. Without lineage, we do not know how different pieces of data depend on each other, making it difficult to conduct triage workflows like upstream root cause analysis and downstream impact analysis [3]. Without logs, we do not know how external systems like ELT / ETL and transformation tools impact our data and how external users are impacted by our data [3].
These four pillars are the minimum observability surface for regulated LLM drift detection. Implementing them means instrumenting the LLM gateway to emit structured events for every request and response, storing prompt and model versions as metadata, recording data provenance for each inference, and centralizing logs from supporting systems.
Building a Dashboard for LLM Drift Detection
A practical dashboard is a control plane for the four pillars above, plus a scoring layer for responsible AI requirements.
A common architecture is:
UpTrain monitors the difference between the dataset the model was trained on and the real-world data it encounters during production [4]. UpTrain can be installed on top of deployment infrastructure such as AWS, GCP, or Azure, and can be self-hosted [4].
For cost and durability at scale, storage choices matter. Object storage like S3 is significantly cheaper than SSD-based storage and can reduce costs by 10x compared to SSD-based storage [5]. S3 offers 99.999999999% durability, protecting against data corruption and loss [5]. Serverless functions, like AWS Lambda, provide on-demand compute that scale instantly [5].
This combination makes it feasible to run evaluators on every trace. Running three analyses on every trace is only realistic when storage and compute cost this little [6]. The cost-efficient evaluators can afford to run on every trace for the same reason: there is no always-on compute to pay for between questions [6].
An open-source pattern for reporting is an open-source Python library that generates interactive reports on ML model performance [2]. That library can be integrated behind the dashboard API to render drift, fairness and safety views without bespoke front-end work.
In practice, teams use the dashboard during change control. When a prompt or model version is updated, operators can view the four pillars for the new cohort versus the reference cohort, see drift signals, and confirm lineage before promoting to production.
What to compare when choosing the stack
| Option | Durability | Cost at scale | Compute model |
|---|---|---|---|
| SSD-based hot store | Low | 10x higher vs object | Always-on |
| Object store S3 | 99.999999999% | 10x cheaper | Serverless on demand |
| Self-hosted UpTrain | Depends on infra | Operational overhead | On-prem |
Reducing Assessment Time with VERA
Manual responsible AI assessments are slow and inconsistent. VERA is a dashboard that can score the twelve requirements that current benchmarks can measure [1].
The VERA dashboard reduced the time needed to perform a responsible AI assessment from 56 seconds to 30 seconds on average [1]. The dashboard reduced the time needed to perform the responsible AI assessment, reducing the time required from 56 seconds using raw files to 30 seconds using our dashboard, on average [1].
In regulated settings, that speed matters for change control. When a prompt is updated for a tax return assistant, the compliance team can re-run the twelve scorable requirements in seconds and see a delta rather than waiting for a manual review cycle. The remaining six requirements typically require human review, documentation or external audits, which the dashboard can track as evidence gaps.
VERA scores the twelve requirements that current benchmarks can measure [1]. Teams use this in real workflows by running the VERA scoring as part of CI/CD for model changes, attaching the resulting evidence package to the change request, and using the delta view to decide whether additional human review is needed.
The dashboard then surfaces the evidence, not just the score. Issues they raise are checked by an AI agent, which verifies the evidence and removes the noise. Actual issues impacting your customers are surfaced to you [6].
Detecting Performance Degradation with Statistical Measures
ML models tend to perform poorly when presented with new and previously unseen cases as well as their performance deteriorates over time due to evolving real-world environments [4]. That last point regarding customization is important because, in most cases, there’s no “ground truth” to check if a model’s output is correct or not [4].
That’s the core problem for LLMs in regulated domains. You cannot always label correctness for free-text tax advice or clinical notes. There’s no 'ground truth' to check if a model's output is correct or not, requiring statistical measures to figure out drift or performance degradation issues [4].
Practical statistical proxies include input distribution shift, output distribution shift, and proxy task performance. Input shift can be approximated with embedding cosine distance, n-gram overlap, or topic model KL divergence. Output shift can be tracked via length, refusal rate, sentiment, or entity counts. Proxy task performance uses rule-based checks, unit tests on known prompts, and sampled human-in-the-loop review.
UpTrain monitors the difference between the dataset the model was trained on and the real-world data it encounters during production [4]. That monitoring is the first line of defense before performance degradation becomes a business metric problem.
In banking and fintech, combine drift signals with risk signals. In health tech, combine drift with safety policy violations. In tax returns and education, combine drift with factual consistency checks. The dashboard should not try to replace human judgment. It should make the invisible visible fast enough that human reviewers can act before degradation compounds.
Model interpretability supports this process by exposing which features, prompt elements, or retrieval results drive outputs, making it easier to link drift signals to root causes in regulated contexts.
Responsible AI in regulated environments is ultimately about evidence velocity. Capture the four pillars, score what can be scored, monitor drift with statistical proxies where ground truth is absent, and reduce assessment time with tools like VERA. The technology exists. The discipline is making it run on every trace, every day.
References
- VERA: A Responsible AI Dashboard for Assessing LLM Deployments in Light of the EU AI Act — arxiv.org
- Launch HN: Evidently AI (YC S21) – Track and Debug ML Models in Production | Hacker News — news.ycombinator.com (7 July 2021)
- The Four Pillars of Data Observability | Metaplane — metaplane.dev (11 August 2022)
- Launch HN: UpTrain (YC W23) – Open-source performance monitoring for ML models — news.ycombinator.com (8 March 2023)
- Metrics Observability: High-Performance & Low-Cost | Oodle AI — blog.oodle.ai (24 September 2024)
- Oodle AI | Observability Built for Agents — oodle.ai (14 July 2026)