Balancing Pruning and Diversity

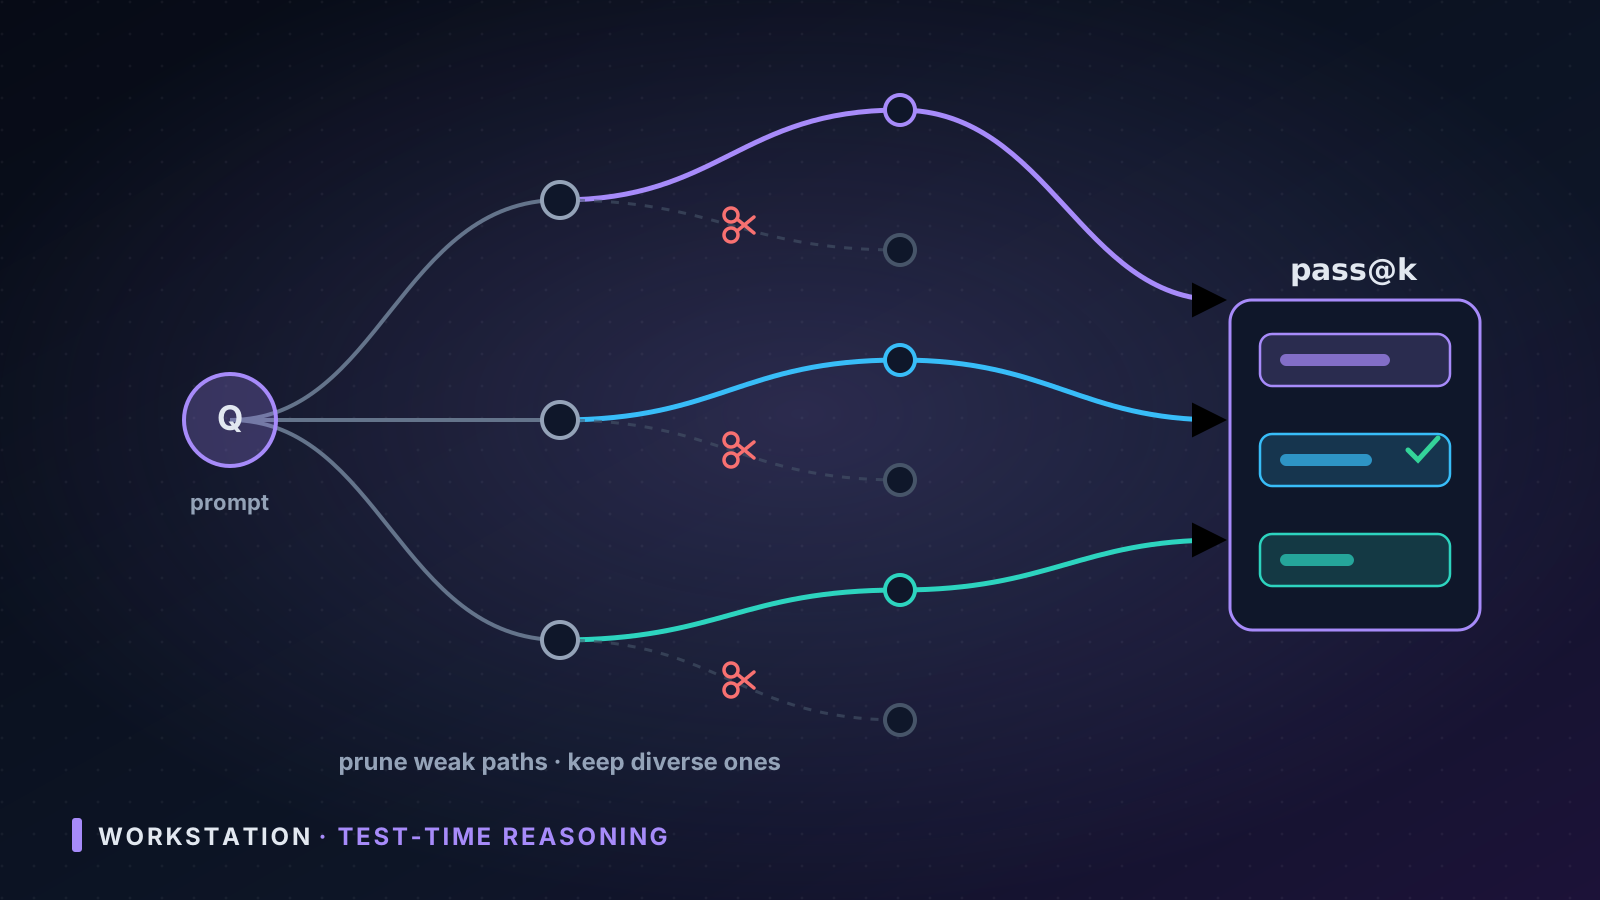
Test-time reasoning is increasingly the place where quality is won or lost. Generating many candidate reasoning paths and then selecting the best ones lets models solve harder problems without retraining, but the selection step itself is a bottleneck. Pruning too aggressively discards promising routes; pruning too conservatively wastes compute and drowns the final vote in noise.
This article defines the pruning trade-off, explains why quality and diversity are not a binary choice, and describes how direct Pass@$k$ optimization balances them for developers building reasoning systems under a budget.
What is Direct Pass@$k$ Optimization?
Pass@$k$ is an evaluation metric: the probability that at least one of $k$ samples is correct. Direct Pass@$k$ Optimization is an approach to test-time pruning that targets this metric explicitly rather than proxy objectives.
In the pruning literature, strategies are commonly grouped into two families. Quality-based methods assign a score to each partial solution and discard those predicted to ultimately lead to an incorrect final solution, while diversity-based methods select partial solutions that follow different reasoning trajectories and are therefore likely to cover different final solutions [1]. Direct Pass@$k$ Optimization treats the choice of which partial thoughts to keep as an optimization problem over the chance of eventual success with $k$ continuations.
The framing matters for regulated domains. In banking, education, HealthTech, FinTech and tax returns, a single correct final answer is often more valuable than a large set of plausible intermediates. The metric aligns with operational risk: does the system produce at least one correct, auditable reasoning trace within a budget?
The Trade-Off Between Quality and Diversity
Quality-focused pruning and diversity-focused pruning represent the classic exploration versus exploitation tension. Quality pruning exploits high-scoring prefixes; diversity pruning explores different reasoning trajectories to avoid correlated failures. The tension between these two objectives is an instance of exploration versus exploitation, yet little to no prior work on pruning exposes this trade-off directly, let alone optimizes it [1].
For developers, this shows up as the choice between a few high-confidence calculations and a broader set of alternative interpretations of ambiguous inputs. In education, it is the difference between selecting the most likely solution path and preserving pedagogically distinct approaches. In HealthTech and tax returns, where a wrong final answer carries compliance or safety consequences, both false negatives from over-pruning and false positives from under-pruning are costly.
A simple comparison of the two traditional families:
| Pruning family | What it optimizes | Typical strength | Typical weakness |
|---|---|---|---|
| Quality-based | Score of partial solution predicting final correctness | High precision on strong prefixes | Collapses to similar trajectories, misses rare correct paths |
| Diversity-based | Difference in reasoning trajectory | Coverage of distinct final solutions | Keeps low-quality branches, wastes compute |
Existing pruning strategies divide broadly into two categories: Quality-based methods assign a score to each partial solution and discard those predicted to ultimately lead to an incorrect final solution, while diversity-based methods select partial solutions that follow different reasoning trajectories and are therefore likely to cover different final solutions [1]. Direct Pass@$k$ Optimization does not pick one side. It learns a selection policy that balances the two in service of the probability of at least one correct completion.
Applying Direct Pass@$k$ Optimization to Thought Pruning
Thought pruning operates during test-time generation: a set of partial reasoning steps is generated, scored, and pruned, then the survivors are continued and the best final answer is chosen, often via self-consistency voting.
The key claim from recent work is that directly balancing quality and diversity during pruning improves Pass@$k$. Our method outperforms existing quality-based and diversity-based pruning strategies on eight open-weight reasoning models [1]. The gains are particularly pronounced when the pruning procedure keeps a moderate number of partial solutions for continued generation, highlighting the value of directly balancing quality and diversity during pruning [1].
That moderate-budget regime is exactly where production systems live. Latency budgets are tight and compute is metered. Interactive tutoring cannot afford to generate hundreds of full traces. A moderate budget keeps explainability tractable for review.
A typical pruning loop can be expressed as:
def prune_and_continue(prefixes, k_keep, k_final):
  # prefixes: list of partial reasoning traces
  # score each prefix for quality and diversity contribution
  scores = direct_passk_score(prefixes)
  kept = select_top_k(prefixes, scores, k_keep)
  completions = [continue_generation(p) for p in kept]
  return best_of_k(completions, k_final)
The scoring function is where the direct Pass@$k$ objective is encoded. The selection step is not a fixed heuristic; it is tuned to maximize the chance that at least one kept prefix yields a correct final answer.
The workflow can be visualized as a lifecycle:
This lifecycle makes the feedback explicit: pruning is not a one-off filter but a decision point that influences the downstream probability of success.
Benefits and Trade-Offs in Banking, Education, and HealthTech
The core mechanics of pruning and Pass@$k$ optimization are domain-agnostic. What changes across Banking, Education, HealthTech, FinTech and Tax Returns is the cost model and the definition of correctness.
In Banking and FinTech, correctness means numerical accuracy and regulatory traceability. A quality-biased prune may favor the most confident arithmetic path and miss an alternative interpretation of a fee schedule. A diversity-biased prune may keep too many variants and increase review time. Direct Pass@$k$ pruning aims for a set of traces where at least one passes reconciliation checks without exploding the audit log.
In Education, the value of diversity is pedagogical. Students benefit from seeing distinct solution strategies, not just the single most probable one. Pass@$k$ optimization still applies: the system wants at least one correct and explainable final solution within a time budget, while preserving a few pedagogically distinct prefixes for presentation. The trade-off is not safety but learning effectiveness and engagement.
In HealthTech and Tax Returns, the constraint is risk. A wrong final answer can have compliance or patient safety consequences. Here the benefit of direct optimization is risk reduction at a fixed compute budget. Keeping a moderate number of diverse, high-quality partial solutions increases the chance that the correct reasoning chain survives to completion, which is the operational meaning of Pass@$k$.
Across these sectors, the same limitation applies: pruning relies on reliable signals for partial quality and diversity. When those signals are weak, the optimizer can be misled. The method also adds complexity to the inference path, which matters for latency-sensitive services.
Social and ethical implications must be considered alongside technical performance. In high-stakes domains, pruning decisions determine which reasoning traces are even allowed to complete. Biased quality signals can systematically suppress valid but minority reasoning patterns, reducing fairness and auditability. In education, over-optimization for Pass@$k$ can prioritize a single correct answer over exposure to diverse pedagogical strategies. Transparency about the selection policy and human-in-the-loop review are necessary to mitigate these risks.
Real-World Applications and Future Directions
Current deployments of test-time pruning are most mature in reasoning-heavy back-office tasks: loan document extraction with multiple interpretation attempts, tax rule application with alternative parsing of forms, and clinical note summarization where a correct extraction must be guaranteed within a budget.
Future work is likely to focus on three areas. First, better estimators for partial solution quality without full generation. Second, adaptive budgets that change $k$ based on input difficulty. Third, integration with human-in-the-loop review, where the pruned set is presented to a domain expert for final selection rather than automated voting.
For teams building in Banking, Education, HealthTech, FinTech and Tax Returns, the practical takeaway is pragmatic: treat pruning as an optimization problem over Pass@$k$, not as a choice between quality and diversity. Measure the probability of at least one correct completion under your real latency and cost constraints, and tune the selector to that metric. The gains are most visible when you cannot afford to generate everything and cannot afford to prune too hard.
Conclusion
Quality-based and diversity-based pruning are not mutually exclusive alternatives. Existing pruning strategies divide broadly into two categories: Quality-based methods assign a score to each partial solution and discard those predicted to ultimately lead to an incorrect final solution, while diversity-based methods select partial solutions that follow different reasoning trajectories and are therefore likely to cover different final solutions [1]. The tension between these two objectives is an instance of exploration versus exploitation, yet little to no prior work on pruning exposes this trade-off directly, let alone optimizes it [1].
Direct Pass@$k$ Optimization makes the trade-off explicit and optimizable. Our method outperforms existing quality-based and diversity-based pruning strategies on eight open-weight reasoning models [1], with gains particularly pronounced when the pruning procedure keeps a moderate number of partial solutions for continued generation, highlighting the value of directly balancing quality and diversity during pruning [1].