مدونة Workstation
Observability
منشورات موسومة بـ Observability.
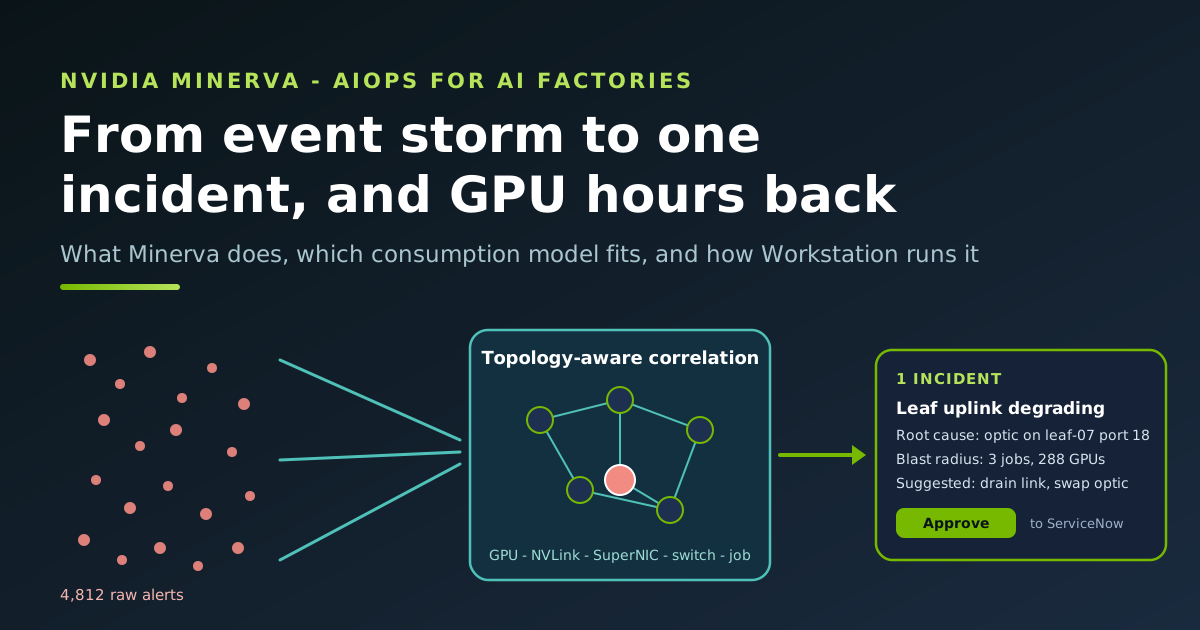
NVIDIA Minerva for AI Factories: Turning Alert Storms into Recovered GPU Hours
One degrading optic can raise thousands of alerts and stall a thousand GPUs. What NVIDIA Minerva does, what it is worth in GPU hours, goodput, MTBI, MTTR and tokens, which of its three consumption models fits, worked examples for a Vera Rubin NVL72 neocloud, a university Blackwell cluster and an enterprise with Grafana and ServiceNow, and how it relates to UFM.
 Balinder Waliaاقرأ
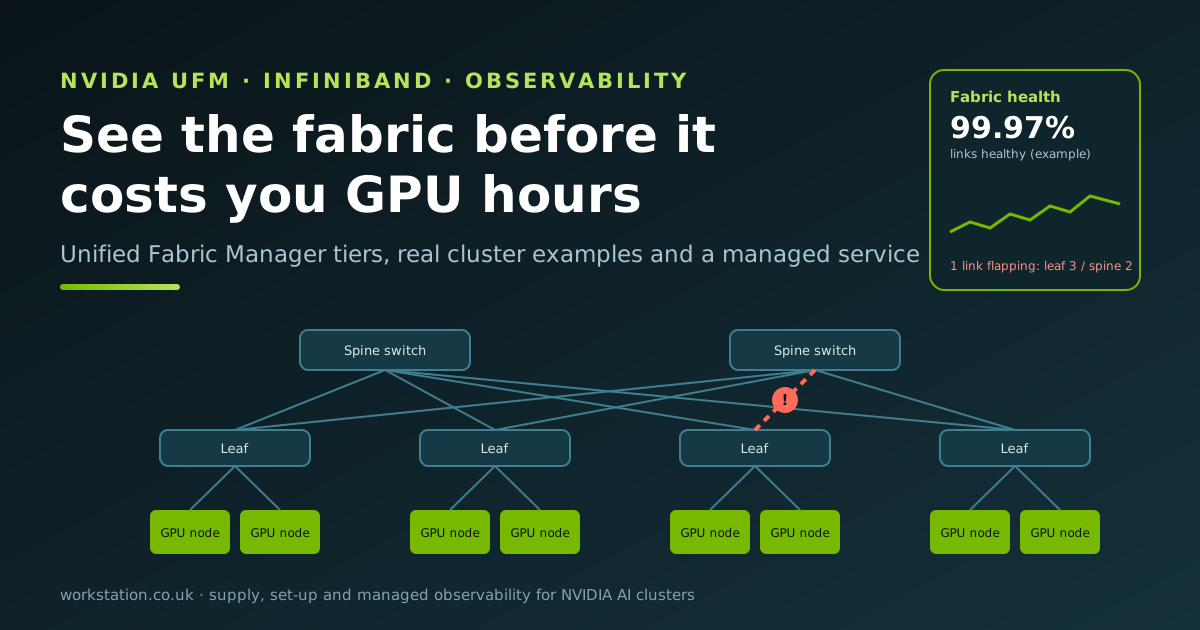
NVIDIA UFM for AI Clusters: Why InfiniBand Fabric Visibility Decides What Your GPUs Are Worth
One flapping InfiniBand link can stall a 256-GPU job. What NVIDIA Unified Fabric Manager does, when UFM Telemetry, Enterprise or Cyber-AI fits, worked examples for a 4-node DGX B300 cluster, a 32-node SuperPOD-style cluster and a university Slurm service, and what fabric visibility is worth in GPU hours.
Balinder Waliaاقرأ 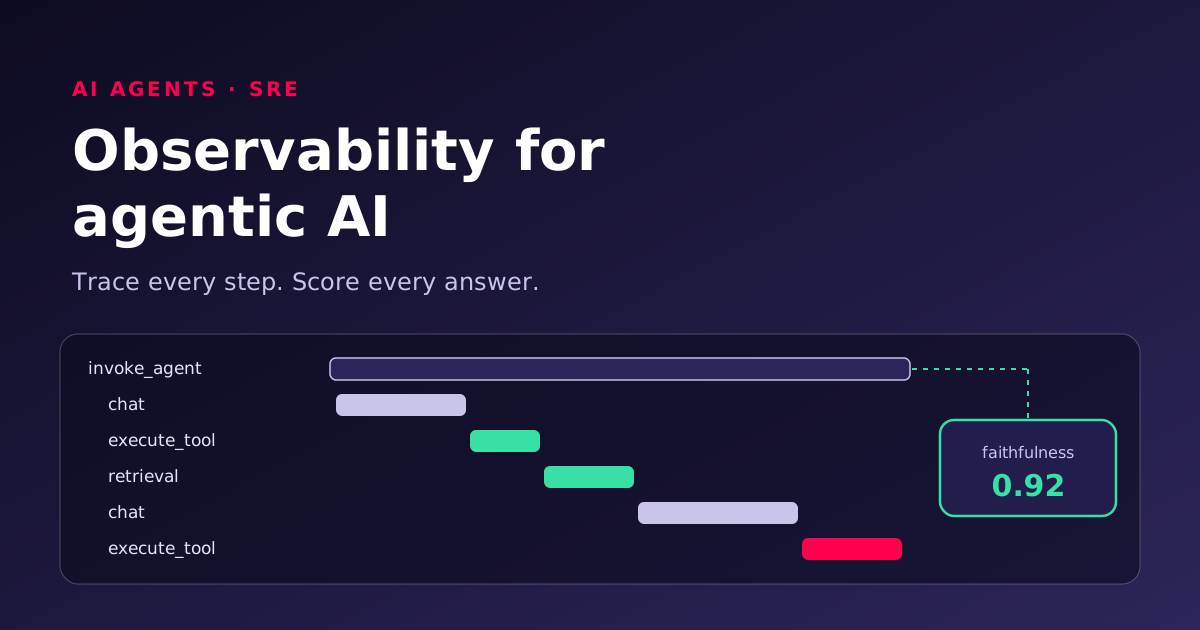
Observability for Agentic AI: Tracing, Evaluating and Auditing Agents
AI agents fail quietly: a confident answer from the wrong document, a tool called with the wrong argument. Learn how to trace every model, retrieval and tool step with OpenTelemetry, attach quality scores, and keep the records auditors ask for.
Beyond Unit Tests: Testing How Your System Fails and Recovers
Unit tests prove a function is correct, not that a system survives a slow database or a lost zone. A practical guide to cold-start integration tests, fault injection with Toxiproxy, circuit breakers, recovery drills and safely automated mitigation.
Agentic AI in Production: Permissions, Approval Gates, Traces and Evals
A practical playbook for running AI agents in production: classify every tool by side effect, gate mutations behind a human, set hard stop conditions, trace each step with OpenTelemetry and evaluate continuously.
Observability Is Not Optional: Make It a Business Standard
Why fragmented monitoring creates blind spots, duplicate spend, and slow incidents — and how to make centralised observability a non-negotiable company standard.
Balinder Waliaاقرأ 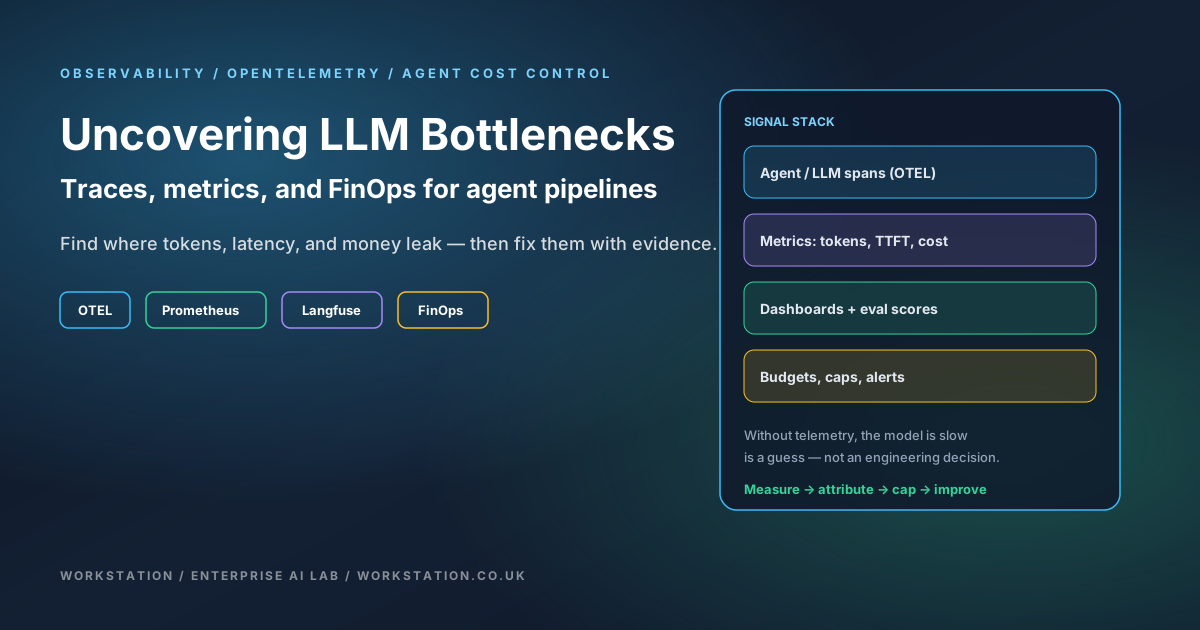
الكشف عن اختناقات LLM: إمكانية المراقبة، وOTEL، والتحكم في التكلفة
Workstation حول الكشف عن اختناقات وكيل LLM مع إمكانية المراقبة: OpenTelemetry، وPrometheus/Grafana/Thanos، وLangfuse - مع إيجابيات/سلبيات واضحة، ورافعات التكلفة، ومقاييس الاستخدام التي تحمي الهوامش.
Balinder Waliaاقرأ 
ترقيات Couchbase باستخدام بوابات الإيقاف المؤقت لـ CAO: نظرة عامة سهلة الاستخدام
نظرة عامة سهلة الدعم وجاهزة لـ SRE حول ترقيات خادم Couchbase تحت مشغل Couchbase المستقل (CAO)، باستخدام spec.paused لبوابة إعادة توازن المبادلة لعقدة واحدة في كل مرة - حتى تتمكن من تحقيق الاستقرار والتحقق من الصحة وإبقاء خيارات التراجع مفتوحة.
Balinder Waliaاقرأ 